Home Blog Page 10

5 ChatGPT Prompts for Ethical Competitor Research

0

Competitor research is useful when it helps you understand what customers can already choose, where public claims overlap, and which questions your own product still needs to answer. It becomes unreliable when a tidy summary is mistaken for evidence. It also crosses an ethical line when it depends on impersonation, private accounts, confidential material, or invented facts.

ChatGPT can help organize public or supplied information, but it does not have private knowledge of another company. The safest workflow is simple: collect the source material yourself, preserve the links and dates, ask for a structured analysis, and check every important conclusion against the original pages. This guide provides five prompts for that job. Each prompt creates an output a person can review rather than a verdict you are expected to trust.

The prompting method follows OpenAI’s current ChatGPT prompt engineering guidance: make the request clear, give enough context, review the first response, and refine the prompt when the result misses the point. OpenAI also warns that ChatGPT can produce wrong facts and fabricated references. Its truthfulness guidance recommends checking important information at reliable sources.

Set an ethical research boundary first

Before comparing anything, write down what information is allowed. Good inputs include public product pages, public pricing pages, published help articles, terms, press releases, public job listings, public reviews, and documents your organization owns or has permission to use. A customer interview can also be an input when the participant agreed to the use and personal details are removed where appropriate.

Do not ask ChatGPT to guess private revenue, nonpublic customer lists, unreleased plans, internal weaknesses, or the contents of a restricted account. Do not create fake identities to obtain sales material. Do not paste trade secrets, personal data, confidential proposals, or material covered by a nondisclosure agreement. Laws and contracts vary, so an internal legal or compliance review may be needed for sensitive projects.

Public does not mean timeless. A pricing page can change after you collect it. A review may describe an older version. Record the URL, page title, and access date for every source. When possible, quote the exact passage that supports a claim. If two sources disagree, keep the disagreement visible instead of asking ChatGPT to choose the answer that sounds most plausible.
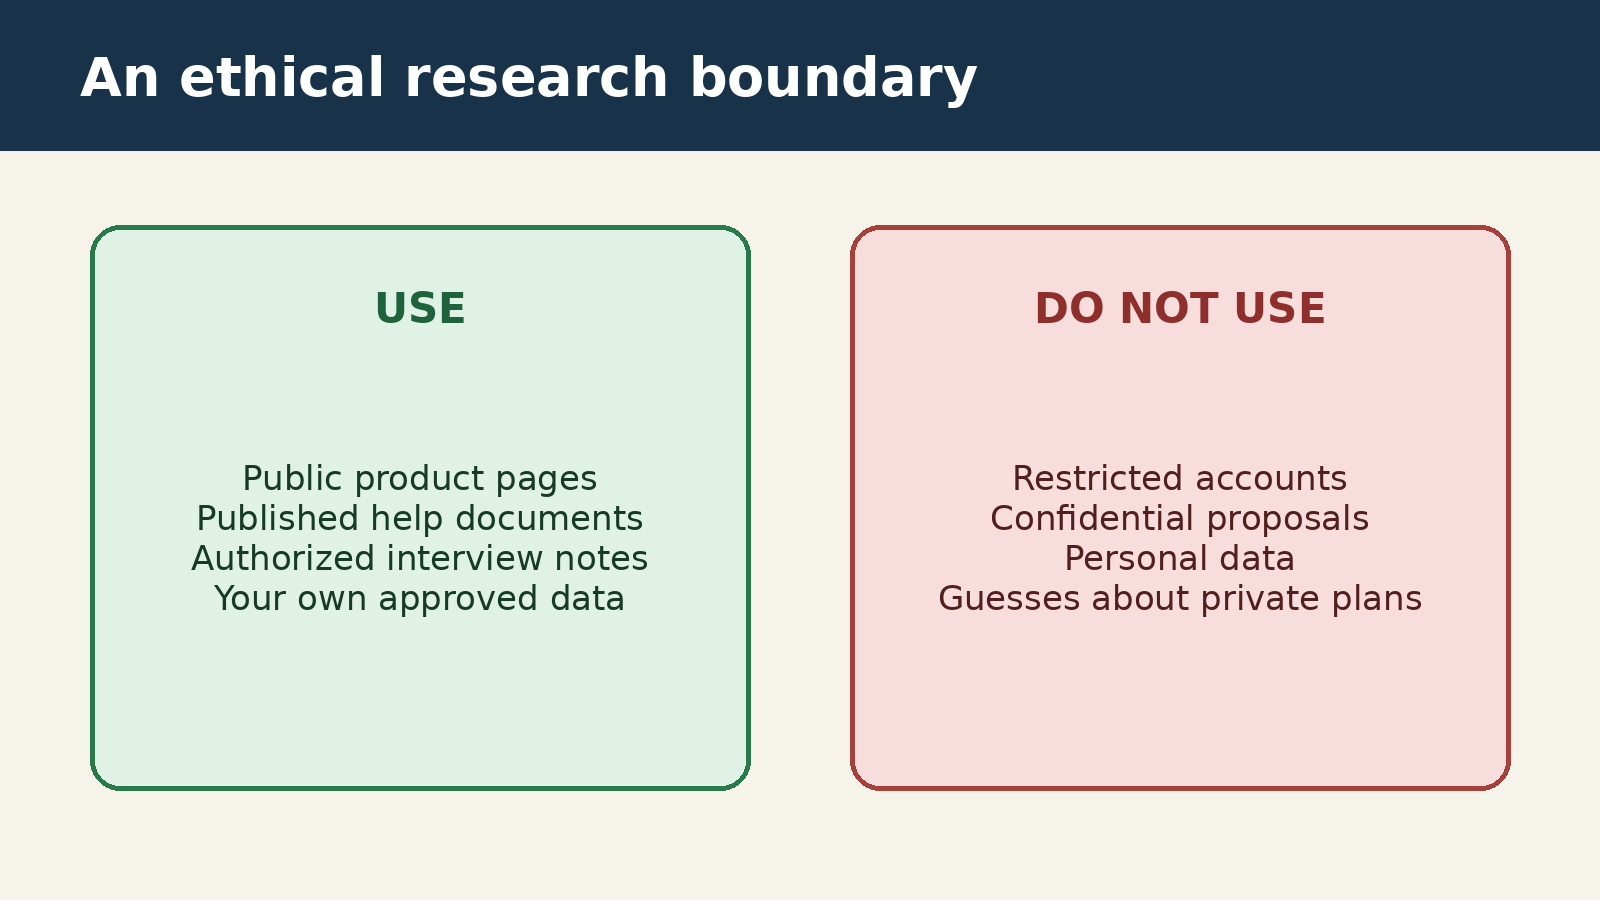
Ethical competitor research boundary separating public and supplied sources from private or restricted information

Prepare a small evidence packet

A competitor analysis works better with a narrow question than with a request to “analyze the market.” Decide what decision the work will support. You might need to revise a comparison page, prepare customer interview questions, review onboarding language, or identify topics for product documentation. That decision determines which evidence matters.

Create one evidence packet for each company. Use the same headings so the comparison is fair:

  • Company and product name as shown on the official site
  • Source URL, page title, publisher, and access date
  • Short relevant excerpt, copied accurately
  • Source type, such as official page, help document, or public review
  • Time period or product version, when stated
  • Notes about ambiguity, missing context, or possible bias

Keep official company claims separate from customer observations. An official page can establish what a vendor says. It does not prove that every customer experiences the product that way. A public review can describe one person’s experience. It does not establish a universal product fact. This separation prevents an attractive synthesis from flattening different kinds of evidence into one story.

If you want a broader primer before using the templates, read the site’s ChatGPT prompt engineering guide. The guide to common ChatGPT mistakes covers verification habits that also apply here.

How to use the five prompts

Replace every bracketed field. Paste only the evidence you are allowed to use. If the material is long, run the prompt on a few sources at a time, inspect the extraction, and then combine the reviewed tables. OpenAI’s developer guidance says headings and delimiters can separate instructions from source material. The templates use clear sections for that reason.

Ask ChatGPT to cite the source label beside each factual statement. A source label makes checking easier, but it does not prove the statement is correct. Open the original page and confirm the wording yourself. If ChatGPT has an available web research tool in your account, inspect every cited link and do not assume a search result is an authoritative source merely because it appears in the answer.

Prompt 1: build a claim ledger

Start by extracting claims before asking for strategy. This prompt turns a mixed evidence packet into a ledger with a visible trail back to each source.

Task:
Create a claim ledger from the supplied competitor research packet.

Research boundary:
Use only the text under SOURCES. Do not use background knowledge. Do not infer private plans, revenue, customers, performance, or intent.

For each distinct claim, return:
1. Claim in plain language
2. Company or product
3. Source label
4. Exact supporting quote
5. Source type: official claim, documentation, or public observation
6. Date or version stated in the source
7. Confidence: direct, ambiguous, or unsupported
8. What a reviewer should verify

Rules:
- Split combined claims into separate rows.
- Mark a claim unsupported if no quoted passage supports it.
- Keep conflicting claims in separate rows.
- Do not convert marketing adjectives into measured facts.

SOURCES:
[paste labeled public or authorized sources here]

Review the ledger row by row. Check that each quotation exists and that ChatGPT has not widened its meaning. For example, “works with selected file types” should not become “works with all business documents.” Delete duplicate rows, correct source labels, and keep unsupported claims out of later analysis.

Prompt 2: compare positioning without declaring a winner

Once the ledger is clean, compare how the companies describe the audience, problem, and value. The goal is to map positioning, not to award a score based on incomplete evidence.

Task:
Compare the public positioning in the reviewed claim ledger.

Decision this supports:
[example: revise our homepage explanation for small accounting firms]

Return these sections:
A. Audience named by each company
B. Problem each company says it solves
C. Outcomes each company explicitly claims
D. Proof offered for those claims
E. Important similarities
F. Important differences
G. Questions the public material does not answer

Evidence rules:
- Cite a source label after every factual statement.
- Distinguish quoted language from your summary.
- Do not rank companies or predict which will win.
- Do not treat absence from the packet as proof that a feature or policy does not exist.
- Label interpretation as interpretation.

REVIEWED CLAIM LEDGER:
[paste the checked ledger here]

Look for false symmetry in the output. Two pages may use the same word while meaning different things. Conversely, different language may describe similar work. Confirm that each comparison uses equivalent product levels, regions, and dates. If those details are unclear, turn the comparison into a research question rather than a conclusion.

Prompt 3: create a feature and policy matrix

Feature tables are easy to publish and easy to get wrong. Plans change, footnotes matter, and similar feature names may refer to different behavior. This prompt uses three states: documented, unclear, and not addressed in the supplied evidence. It does not use “missing” as a shortcut.

Task:
Build a reviewable feature and policy matrix for the products below.

Rows to examine:
[paste the exact feature, support, privacy, onboarding, or pricing questions]

Columns:
[our product, if relevant] For each cell include: - Status: documented, unclear, or not addressed in supplied evidence - Short explanation - Source label and exact quote - Plan, region, date, or version limitation - Verification needed before publication Rules: - Use only the supplied sources. - Do not treat "not addressed" as "not available." - Do not merge similarly named features without evidence that they work alike. - Keep prices in their stated currency and billing period. - Flag contradictory or outdated sources. SOURCES: [paste checked source excerpts here]

Check every cell against the original source. Pay close attention to monthly versus annual billing, taxes, introductory offers, usage limits, and plan names. If your final comparison will be public, add a visible “last checked” date and a correction channel. A matrix is a snapshot, not a permanent fact sheet.
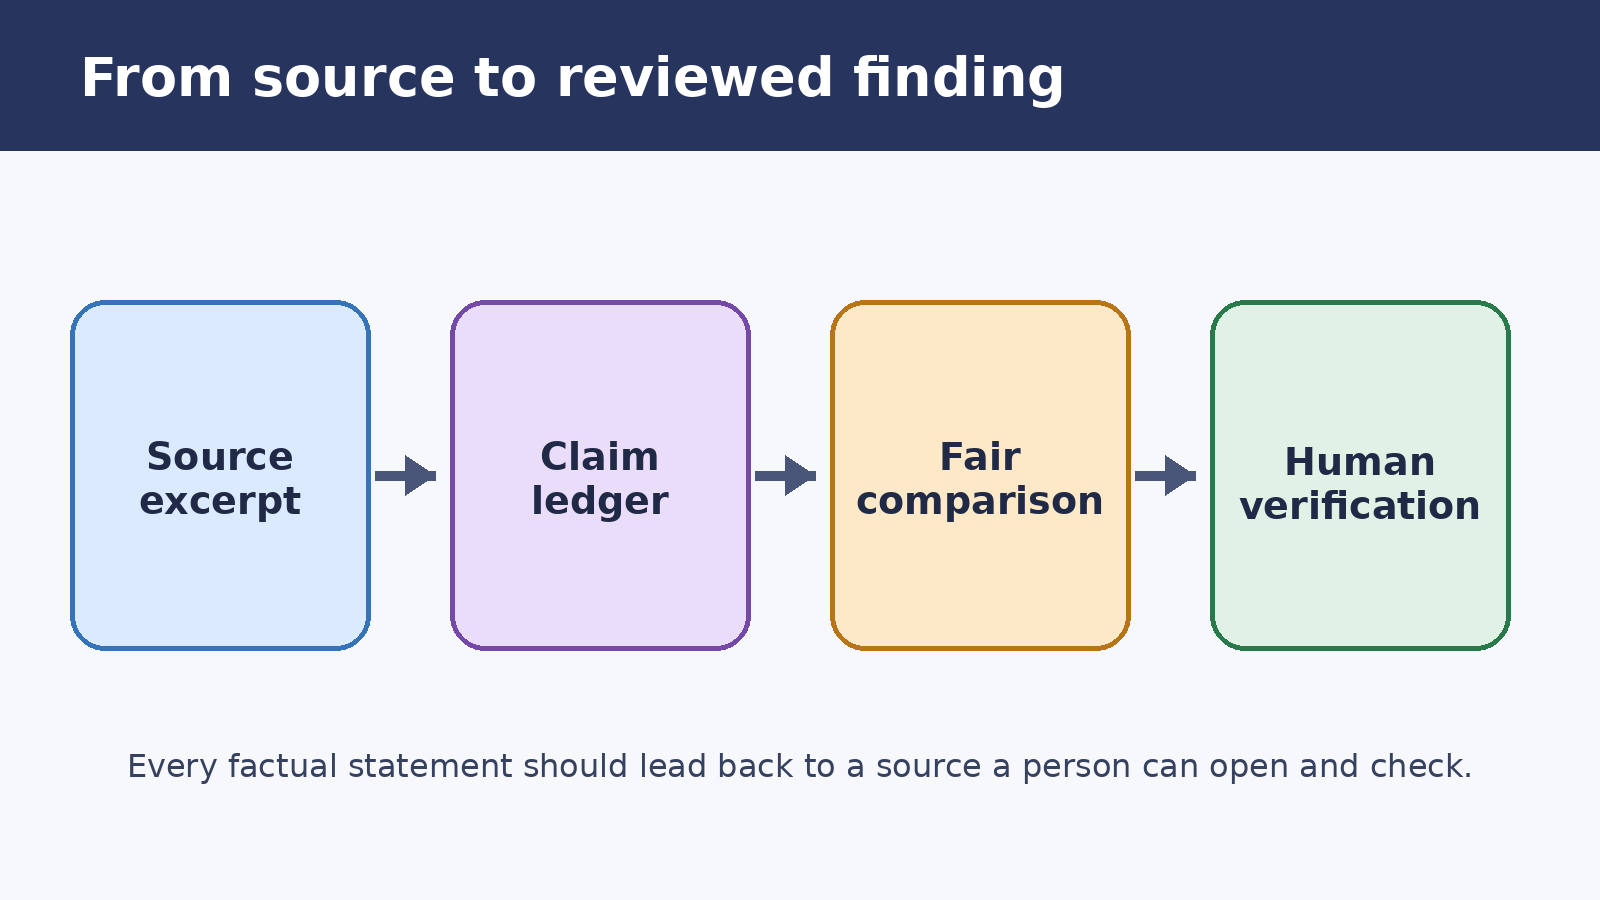
Review workflow for competitor claims moving from source excerpt to claim ledger, comparison, and human verification

Prompt 4: analyze public customer language carefully

Reviews, forum posts, and interview notes can reveal the words people use for a problem. They are not a representative survey unless the collection method supports that conclusion. Use this prompt to find themes while preserving counts, source types, and dissenting examples.

Task:
Analyze the supplied public reviews or authorized interview notes for language patterns.

Return:
1. Repeated jobs or situations described by participants
2. Phrases used to describe the problem
3. Positive experiences, with source labels
4. Friction or complaints, with source labels
5. Contradictory experiences
6. Questions for future customer interviews

For every theme include:
- Number of supplied items that mention it
- Source labels
- One or two short quotations
- A limitation note

Rules:
- Do not identify anonymous people.
- Do not infer demographics, motives, or diagnoses.
- Do not call a theme common unless the supplied count supports that wording.
- Do not claim the sample represents the full customer base.
- Keep product facts separate from personal opinions.

MATERIAL:
[paste de-identified, permitted material here]

Read the minority examples, not only the largest cluster. A small set of detailed complaints may point to a useful interview question, but it cannot establish market size. Remove personal details before sharing notes. If the material came from your own interviews, retain the consent and research records outside ChatGPT according to your organization’s policy.

Prompt 5: turn findings into testable research questions

The final prompt converts reviewed observations into questions and low risk tests. It deliberately avoids a confident strategy prescription. Your team still owns prioritization, customer contact, and interpretation.

Task:
Turn the reviewed competitor findings into a research backlog for our team.

Our decision:
[state the product, content, sales, or research decision]

For each backlog item return:
1. Observation from the evidence
2. Source labels
3. Why it may matter to the stated decision
4. Alternative explanations
5. A research question
6. A low risk validation method using our customers, our analytics, or public information
7. Evidence that would support the idea
8. Evidence that would weaken it
9. Owner role and review date, left blank for our team to fill

Rules:
- Do not predict revenue, market share, or competitor actions.
- Do not recommend deception, scraping behind access controls, or collection of personal data.
- Do not present an observation as a customer need until it is validated.
- Prefer reversible tests and direct customer research.

REVIEWED FINDINGS:
[paste checked findings here]

A useful backlog contains questions your team can answer. “Competitor A emphasizes quick setup” may lead to a usability study of your own setup process. It does not prove that speed is the main buying factor or that copying a competitor’s message will improve results. Record who will test the question, which evidence will count, and when the team will revisit it.

A practical review checklist

Before a comparison leaves your working document, run a human review. Open every source and check the quoted passage. Confirm the date, market, plan, and product version. Separate official claims from observed experiences. Search the draft for words such as “best,” “only,” “all,” and “never,” because these often overstate the evidence. Check that “not found” has not become “does not exist.” Remove any private or unnecessary personal information.

Then check the analysis itself. Could another reviewer reproduce the claim from the packet? Are alternative explanations visible? Does the output distinguish fact, summary, and interpretation? Is a current employee responsible for the final decision? If the answer will be published, give readers links, a checked date, and a way to report a correction.

OpenAI’s prompt engineering documentation recommends clear structure, relevant context, and examples where they help define the desired output. Those techniques make a research request easier to inspect. They do not make the model a source. Your evidence packet remains the source, and the reviewed analysis remains a working document.

Frequently asked questions

Can ChatGPT access a competitor’s private data?

No. You should not assume ChatGPT has access to private systems, internal documents, restricted accounts, or confidential plans. Use public sources and information you are authorized to provide. Do not ask it to invent missing private details.

Is public information always safe to reuse?

No. Public availability does not remove copyright, privacy, contractual, or legal concerns. Quote only what you need, attribute it accurately, respect site terms and access controls, and seek qualified advice when the project is sensitive.

How do I handle a feature that is not mentioned?

Label it “not addressed in the supplied evidence.” That wording describes your research packet. It does not claim the feature is unavailable. Add a verification task using an official source or a direct question to the company.

Should I publish ChatGPT’s comparison as written?

No. Treat the response as a draft analysis. Check every factual statement, quotation, date, and link. A person should review fairness, context, privacy, and legal risk before publication or a business decision.

Keep the conclusion proportional to the evidence

Competitor research rarely produces one final answer. It produces a dated record of claims, differences, uncertainties, and questions worth testing. ChatGPT can reduce the clerical work of sorting that record. It cannot replace source review, customer research, or accountable judgment.

Use the five prompts in sequence only when the sequence fits your decision. For a small copy review, the claim ledger and positioning comparison may be enough. For a public comparison page, the full matrix and verification pass are appropriate. Stop when the evidence stops. An honest blank cell is more useful than a confident guess.
5 ChatGPT Prompts to Shape Existing Skills Into Offer Ideas

0

A skill does not become an offer because a chatbot gives it a catchy name. The useful work comes earlier: describing what you can already do, identifying a person who may need that help, setting a narrow scope, and deciding how you would deliver it. ChatGPT can help you think through those choices, but it cannot confirm demand, set a guaranteed price, or promise that anyone will buy.

This guide gives you five prompt templates for examining an existing skill and turning it into possible service or product concepts. The templates are editorial examples created for this article. They are not official OpenAI commands, business results, or financial advice. Treat every response as a draft to inspect, not a verdict about what the market wants.

Start with evidence from your own work

Begin with work you have actually done. A spreadsheet you built for a volunteer group, a lesson plan you used with a student, a repair checklist you follow at home, or a set of photographs you edited all contains better evidence than a broad claim such as “I am good at organization.” You want examples, limits, preferences, and proof that you can repeat the task.

OpenAI’s prompt engineering guidance for ChatGPT recommends clear, specific instructions with enough context. Its separate article on creating a good prompt also suggests breaking complex work into focused requests and refining the result through follow-up prompts. Those product-behavior principles support the process below. The offer ideas, review questions, and templates themselves are our editorial examples.

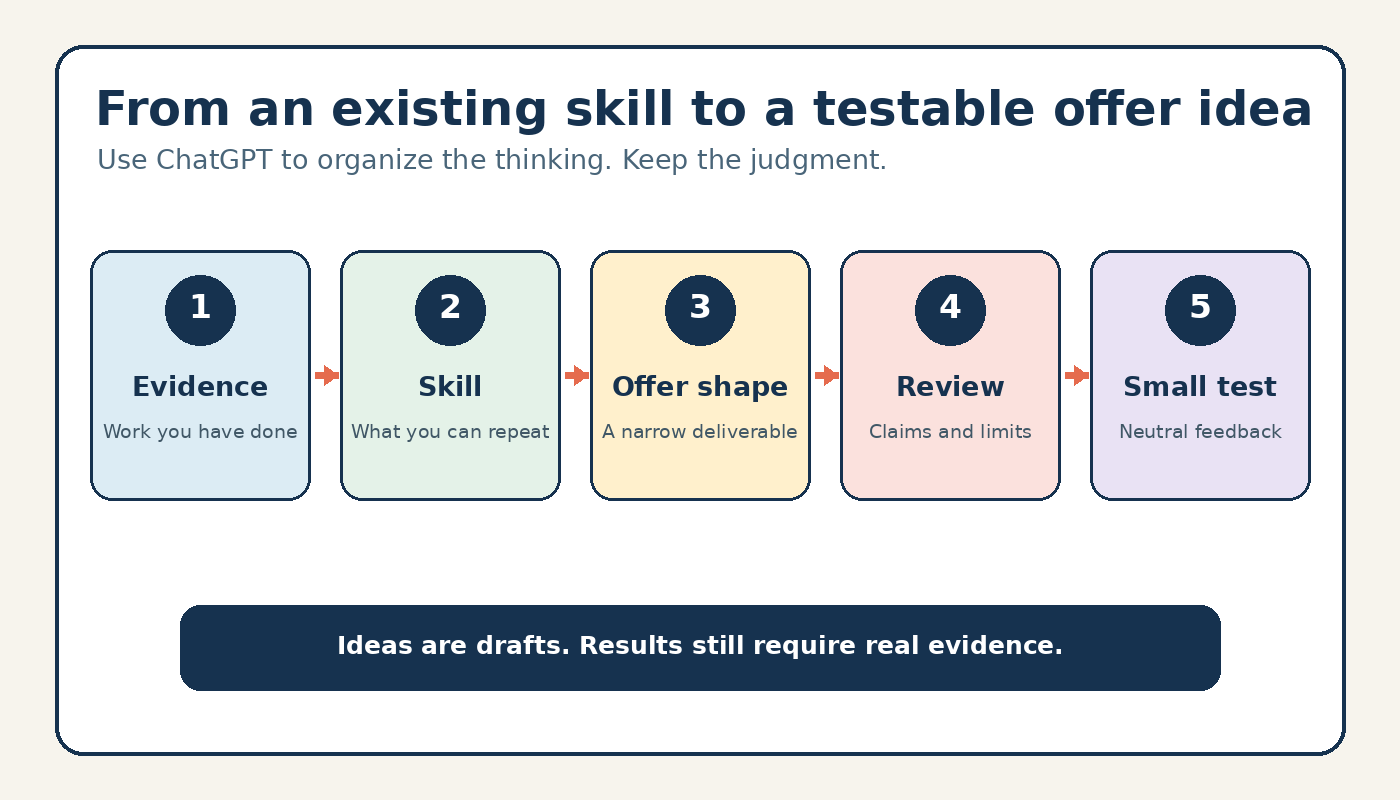
Five-step ChatGPT prompt workflow for mapping an existing skill to a testable offer idea
Move from evidence to a small test. A generated idea is only a starting point.

Prompt 1: make a factual skill inventory

The first prompt is deliberately unglamorous. It asks ChatGPT to separate demonstrated abilities from guesses. Paste only information you are comfortable sharing, and remove client names, private documents, account details, and confidential results.

Editorial prompt template:

I want to examine skills I already use. Based only on the evidence below, create a table with: demonstrated skill, example evidence, type of person who might need it, tasks I enjoy, tasks I avoid, and important limits. Do not invent credentials, results, demand, or experience. Mark missing information as "unknown" and ask up to five follow-up questions.

My evidence:
[Paste short examples of work, responsibilities, tools, feedback, or projects.]

Read the table with a red pen. Delete any skill that depends on a credential you do not have. Correct inflated language such as “expert” if your evidence shows beginner or intermediate experience. The best output is not the longest list. It is the list you can defend with real examples.

Prompt 2: translate one skill into several offer shapes

A single skill can support different forms of work. Someone who knows spreadsheet cleanup might offer a one-time file cleanup, a reusable template, a short training session, or a documented process. These are possibilities, not recommendations. Some will be impractical once you consider time, permissions, local rules, or the buyer’s actual problem.

Editorial prompt template:

Using this verified skill and evidence, suggest six narrowly scoped offer ideas. Include a mix of services, small digital resources, and teaching formats where appropriate. For each idea, state: intended user, specific problem, deliverable, information I would need from the user, what is outside scope, and the easiest assumption to test. Do not estimate income, promise demand, copy competitors, or claim legal, tax, medical, or financial suitability.

Skill and evidence:
[Paste one row from the corrected inventory.]

Look for a deliverable that can be described in one sentence. “Help businesses grow” is too broad. “Clean and document one existing inventory spreadsheet using the client’s current categories” is easier to discuss and review. Narrow scope also exposes missing expertise before you accept responsibility for it.

Prompt 3: write a plain-language offer brief

Choose one possible offer and ask for a brief, not a sales page. The brief should tell you what happens, what does not happen, and what the buyer must provide. Avoid testimonials, urgency, earnings claims, invented success rates, and phrases that imply a guaranteed outcome.

Editorial prompt template:

Draft a one-page internal offer brief for the idea below. Use plain English. Include: who it may suit, the problem it addresses, exact deliverables, delivery steps, buyer inputs, exclusions, revision boundary, risks or dependencies, and questions that remain unanswered. Do not write promotional copy. Do not invent proof, testimonials, scarcity, demand, pricing, or expected financial results.

Offer idea:
[Paste the selected idea and your corrections.]

This is where awkward details are useful. If delivery depends on clean source files, say so. If you can format a resume but cannot advise on immigration or employment law, put that boundary in writing. If you would need access to sensitive data, consider whether the offer should be redesigned to use a sample or redacted file.

Prompt 4: design a low-risk learning test

You do not need a large launch to learn whether the description makes sense. A test might be a conversation with a person in the intended audience, a review of a sample deliverable, or a small pilot with written scope. The aim is to gather specific feedback. It is not to manufacture a success story.

Editorial prompt template:

Help me design a small, ethical test of this offer description. I want to learn whether the problem and deliverable are understandable. Propose: who I could ask for feedback, five neutral interview questions, a sample or pilot boundary, what evidence would support revising the idea, and clear stop conditions. Do not predict sales, recommend paid advertising, create fake urgency, or treat compliments as proof of demand.

Offer brief:
[Paste the corrected brief.]

Neutral questions matter. “Would this save you hours every week?” plants the answer. “How do you handle this task now?” gives the other person room to describe a process that may work perfectly well. Record objections and confusion as carefully as positive reactions.

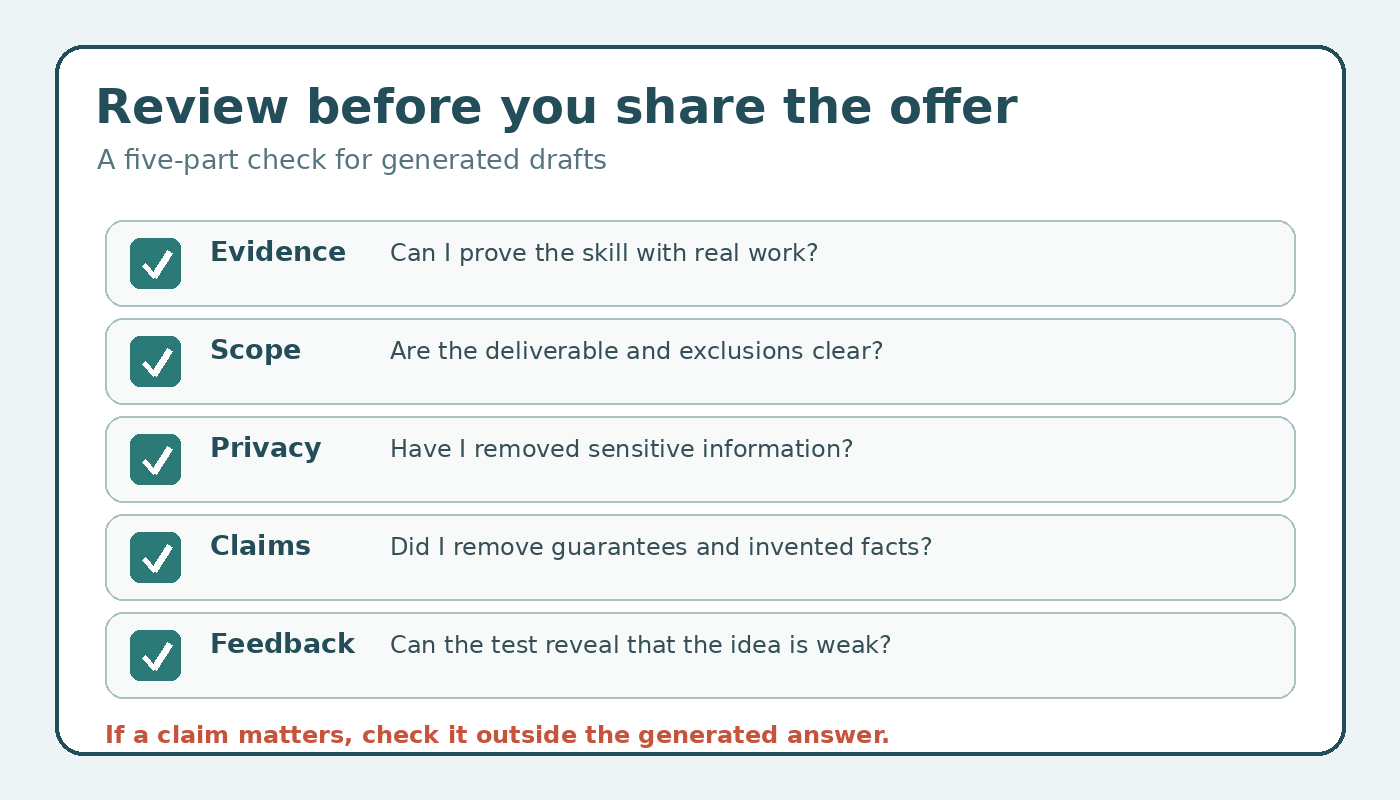
Checklist for reviewing a ChatGPT-generated skill offer before sharing it with a potential user
Check evidence, scope, privacy, claims, and feedback before sharing an offer.

Prompt 5: review the idea for unsupported claims

ChatGPT can sound confident when a statement is wrong. OpenAI’s guide Does ChatGPT tell the truth? warns that responses can include incorrect facts, fabricated references, and overconfident answers. It recommends checking important information against reliable sources. Apply that caution to every claim in your offer, especially claims about outcomes, rules, qualifications, prices, or what a buyer “needs.”

Editorial prompt template:

Audit the offer brief below as a skeptical editor. Quote each sentence that contains a factual claim, implied guarantee, unverified assumption, credential issue, privacy concern, or vague scope. For each, label it "supported by my evidence," "needs a source," "needs clarification," or "remove." Do not repair a claim by inventing a citation. Finish with questions I must answer myself.

My evidence:
[Paste the corrected skill evidence.]

Offer brief:
[Paste the current brief.]

The model’s audit also needs human review. Visit cited links. Check local professional rules where your work touches regulated fields. Ask a qualified professional about legal, tax, accounting, investment, health, or licensing questions. This article does not tell you whether an offer is lawful, profitable, or suitable for your circumstances.

How to judge the output without chasing polish

A polished paragraph can hide a weak idea. Judge the output against your evidence and the intended user’s words. Can you produce the stated deliverable? Is the input list realistic? Does the scope exclude work you cannot safely do? Can another person tell what they would receive? If an answer is unclear, add context and ask a focused follow-up question rather than requesting a complete rewrite.

This differs from a collection of general ChatGPT writing prompts. Here, the raw material is your documented skill and the output is a testable offer brief. It also differs from competitor research. You are not asking ChatGPT to imitate another provider, scrape private information, or declare that a market gap exists. You are clarifying your own scope, then checking it with real people and reliable sources.

If you plan to reuse personal context across chats, read the site’s guide to ChatGPT memory and controls. Regardless of settings, minimize the data you paste. Replace identifying details with placeholders and keep confidential client material out of a general brainstorming session unless you have an approved way to handle it.

A practical review card

  • The skill is supported by work you have actually done.
  • The intended user and problem are specific but not invented.
  • The deliverable, inputs, exclusions, and revision limit are written down.
  • No sentence guarantees demand, income, savings, ranking, approval, or another result.
  • Private data and regulated advice have been removed or handled through an appropriate process.
  • Important factual claims have reliable sources outside the generated answer.
  • Feedback questions are neutral and allow the idea to fail.

Frequently asked questions

Can ChatGPT tell me which skill will make the most money?

No. It can organize information you provide and suggest questions or possible formats, but it cannot guarantee demand, pricing, profit, or future income. Research the real situation and get relevant professional advice before making financial decisions.

Do I need to use all five prompts in one chat?

No. You can use one template at a time and correct the output before continuing. Separate steps often make it easier to notice unsupported assumptions and supply missing context.

Can I paste client work into these prompts?

Do not paste confidential, personal, or restricted material simply because it is convenient. Use redacted examples or invented placeholders, follow your agreements and workplace policies, and check the relevant ChatGPT data controls.

What should I do if ChatGPT invents a credential or result?

Remove it. Then restate the evidence and instruct the model to mark missing information as unknown. Verify every important claim yourself rather than asking the model to confirm its own answer.

Sources and editorial boundary

The OpenAI sources cited above support only the described behavior and prompting advice: give clear context, split complex work into focused requests, refine responses iteratively, and verify important facts. The five templates are editorial examples. They do not represent an OpenAI business method, a market forecast, financial advice, or a promise of results.

7 Best ChatGPT Writing Prompts for 2026

0

The best ChatGPT writing prompts are not magic sentences. They are reusable work orders for a particular stage of writing. One prompt helps you find an angle. Another turns rough notes into an outline. A different prompt diagnoses a draft without rewriting it too soon. Treating those jobs separately keeps your choices visible and makes weak output easier to repair.

This guide gives you seven prompt patterns and shows where each one belongs in a practical writing workflow. The examples are editorial templates, not official OpenAI commands. They work by applying principles from OpenAI’s current guidance: make the request clear and specific, include the context that affects the answer, describe the desired format, separate instructions from reference text, and improve the result through iteration.

ChatGPT can still produce incorrect facts, invented quotations, or references that do not exist. Use it to help with drafting and revision, but verify claims against original sources before you publish or submit the work. Keep private client material, personal data, and confidential documents out of a prompt unless you are authorized to use them there.

A writing workflow built from seven prompts

You do not need to run every pattern for every assignment. A short email may need only a draft and a tightening pass. A sourced article may need all seven. The useful distinction is between deciding, drafting, and checking. If you ask ChatGPT to do all three at once, it can quietly make decisions that should have remained yours.

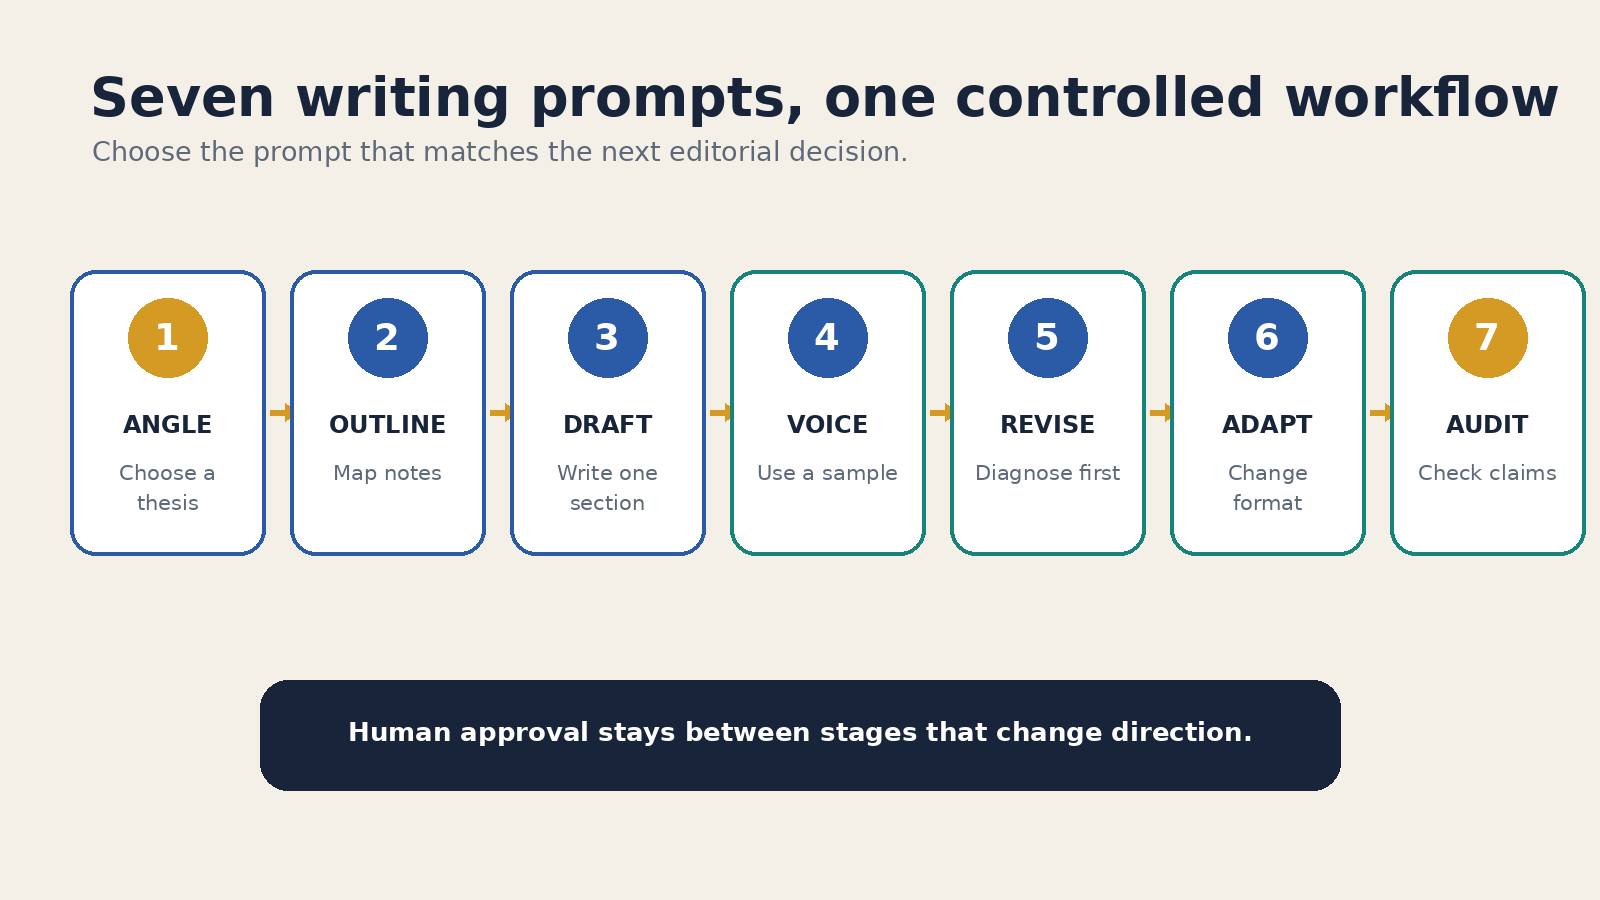
  1. Define the brief and choose an angle.
  2. Build an outline from supplied material.
  3. Draft one controlled section.
  4. Match a voice from a real sample.
  5. Diagnose the draft before revising it.
  6. Adapt the approved copy for another format.
  7. Audit factual claims and citations.

OpenAI’s prompt engineering best practices recommend placing instructions early, being specific about context and outcome, and showing the desired format when it matters. Those recommendations are useful for writing because they force you to state what the piece is supposed to do.

Seven ChatGPT writing prompt patterns arranged as a workflow from brief to source audit

1. The angle finder

Use this pattern when you have a topic but no clear point of view. The prompt should not ask for a random list of catchy ideas. Give it the audience, purpose, evidence you already have, and boundaries. Then ask for a small set of meaningfully different angles that you can compare.

Topic: [topic]
Reader: [specific audience]
Purpose: [what the piece should help the reader understand or do]
Material I already have: [notes, observations, source summary]
Do not cover: [out-of-scope claims or tired angles]

Propose five distinct angles. For each one, give:
1. a one-sentence thesis
2. the reader question it answers
3. the evidence I would need
4. the main risk or weakness

Do not draft the article. End by asking me to choose or combine angles.

The last instruction matters. Brainstorming and drafting are different decisions. If the model writes an introduction immediately, its first angle can become the default before you have compared alternatives. Review the options yourself. Reject any angle that depends on evidence you cannot obtain.

For creative fiction, replace “evidence” with the story elements you want to preserve, such as setting, point of view, central conflict, or an ending you have already chosen. The pattern still works because it asks for alternatives inside stated boundaries.

2. The source-bound outline builder

Once you know the angle, use your notes to build a structure. Separate the instructions from the source material with headings or clear delimiters. OpenAI’s developer documentation explains that Markdown headings and lists can communicate hierarchy, while delimiters can mark the boundary around supporting text. In an ordinary chat, simple labels are usually enough.

Task:
Create an outline for a 1,200-word guide based only on my notes.

Audience:
[reader and level of knowledge]

Thesis:
[approved thesis]

Outline rules:
- Give each section one job.
- Put the sections in a logical reading order.
- Under each heading, list the note IDs that support it.
- Mark unsupported sections as "source needed."
- Do not invent examples, statistics, quotations, or citations.

Notes:
[N1] ...
[N2] ...
[N3] ...

Numbering the notes creates a simple trail from outline to source. It does not guarantee that the interpretation is correct, but it makes unsupported sections easier to spot. If a heading has no note ID, either find a source or remove the heading. Do that before prose makes the gap less obvious.

This pattern is deliberately narrower than a general guide to prompt construction. If you need help organizing long instructions, read the site’s ChatGPT prompt engineering guide. For this workflow, the outline is an editorial checkpoint, not an excuse to make the prompt longer.

3. The controlled section drafter

Draft one section after you approve the outline. Supply the section’s purpose, the source notes it may use, the claims it must not make, and a concrete output shape. A page full of constraints can become self-defeating, so keep only the rules that you will actually check.

Draft the section "[heading]" from the approved outline.

Section job:
[what this section must explain]

Use only these notes:
[paste the relevant notes]

Requirements:
- 250 to 350 words
- plain English for [audience]
- open with the practical problem, not a broad trend
- explain each technical term on first use
- retain the source labels in parentheses for my review

Do not write the introduction, conclusion, or next section.
If the notes do not support a requested detail, insert [SOURCE NEEDED].

This is where specificity helps most. “Write an engaging section” leaves the model to decide what engagement means. A section job and a word range give you something observable to review. OpenAI’s guidance also recommends describing what you want rather than relying only on prohibitions. Tell the model to open with the reader’s practical problem instead of merely saying “do not be generic.”

4. The voice sample matcher

Tone labels such as “professional” or “friendly” are broad. A short sample of writing you own or are allowed to use gives the model a more concrete pattern. Ask it to identify useful characteristics before it rewrites anything. Do not ask for imitation of a living writer or paste material you do not have permission to share.

Study the writing sample below. Describe its observable traits:
- typical sentence length and rhythm
- level of formality
- paragraph length
- use of examples
- words or habits to avoid

Then revise my draft to match those traits without copying phrases from the sample.
Preserve every factual claim, number, name, quotation, and citation.
Do not add facts.

Writing sample:
[approved sample]

Draft:
[your draft]

Review the trait summary before accepting the rewrite. The model may focus on superficial features while missing why the sample works. You can correct that with a follow-up such as, “Keep the short paragraphs, but remove the sales language and preserve my technical terms.” If you often need the same baseline preferences, the site’s guide to ChatGPT custom instructions explains the difference between reusable preferences and details that belong in the current task.

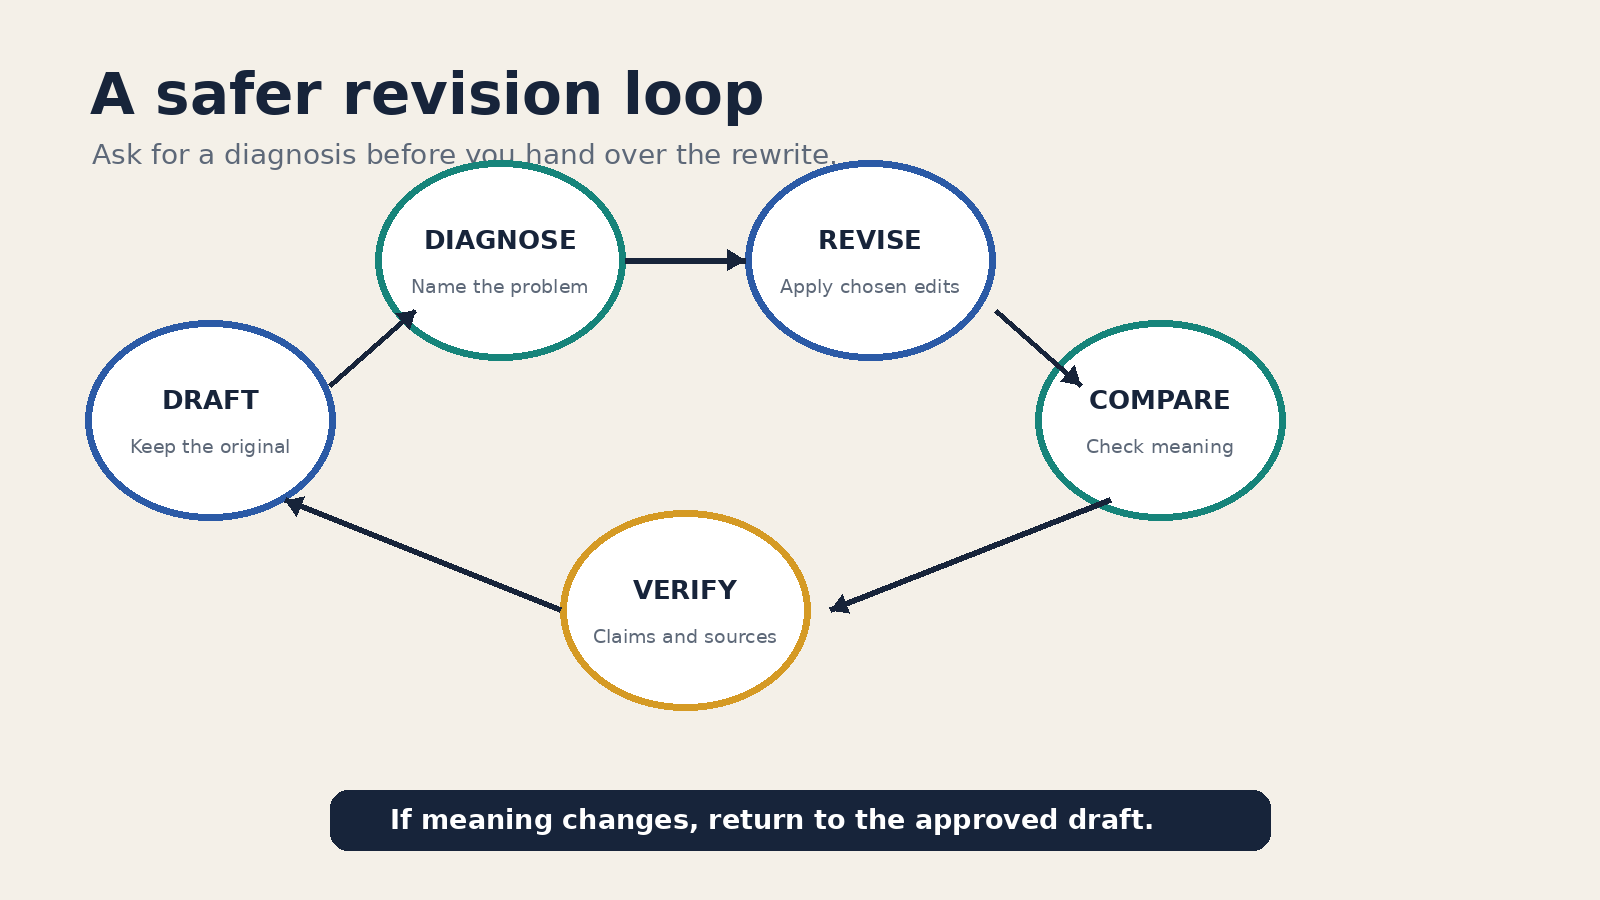
ChatGPT writing revision loop showing draft, diagnose, revise, compare, and verify stages

5. The revision diagnostician

A common mistake is asking ChatGPT to “improve” a draft and accepting a complete rewrite. That can erase a deliberate voice, change a qualified claim, or introduce polished filler. Ask for a diagnosis first. You stay in control of which problems deserve a revision.

Review this draft as an editor. Do not rewrite it yet.

Evaluate:
- whether the opening states a clear purpose
- where the logic jumps or repeats
- claims that need evidence
- sentences that are vague or overloaded
- sections that do not serve the reader

Return a table with four columns:
Passage | Problem | Why it matters | Smallest useful fix

After the table, list the three highest-priority edits.
Draft:
[paste draft]

Choose the edits you agree with, then request a constrained revision: “Apply priorities one and three only. Show the revised paragraphs followed by a short change log.” This two-step exchange makes it easier to compare the result with your original. It also follows OpenAI’s advice to work iteratively rather than expecting one prompt to settle every detail.

Read the revised copy aloud. Check whether sentence length varies naturally, whether transitions say something useful, and whether the model has turned specific language into generic advice. The goal is not maximum polish. It is a draft that sounds like the intended writer and does its assigned job.

6. The format adapter

Only adapt a piece after the source version is approved. Otherwise, you may reproduce the same weak claim across an email, post, summary, and script. Tell ChatGPT which facts and wording must survive, what the new format is for, and what can be cut.

Adapt the approved article excerpt into a customer email.

Audience: [audience]
Purpose: [single purpose]
Length: 140 to 180 words
Required details: [facts, date, link, action]
Tone: direct and calm

Preserve the meaning of all factual statements.
Do not introduce urgency, discounts, testimonials, or new claims.
Use one subject line, a short body, and one call to action.

Approved source copy:
[paste copy]

Format adaptation is not summarization by default. An email needs a reason to read and a clear action. A social post may need one self-contained idea. A script needs language that sounds natural when spoken. Change the prompt’s purpose and acceptance criteria for each destination rather than asking for every format in one batch.

If email is your main use case, the related ChatGPT email writing guide provides task-specific examples. Keep the approved long-form version as the reference copy so you can compare every adaptation against it.

7. The claim and citation auditor

Run the final pattern before publication, submission, or client delivery. It is an inventory, not an automatic fact checker. OpenAI warns that ChatGPT can state incorrect information confidently and can fabricate quotes, studies, citations, or references. Asking it to verify itself does not remove that risk.

Audit the draft below. Do not rewrite it.

Create three lists:
A. Externally verifiable factual claims
B. Quotations, numbers, dates, and named references
C. Statements that are opinion, advice, or interpretation

For every item in A and B, quote the exact draft sentence and identify the source currently attached to it. If no source is attached, write "unverified."
Do not create or guess a citation.

Draft:
[paste final draft]

Open each cited source yourself and check that it exists, supports the exact wording, and is current enough for the claim. The OpenAI accuracy guidance for ChatGPT specifically recommends checking important quotations, data, technical information, and external references. For high-stakes work, use the review process required by your field or organization.

How to run the full sequence without losing control

Start a working document outside the chat. Save the approved brief, chosen angle, source notes, outline, and latest draft as separate blocks. Chat history is useful context, but your own document should remain the record of what you approved.

At each handoff, paste only what the next prompt needs. The outline builder needs the brief and notes. The section drafter needs the approved heading and its supporting notes. The revision prompt needs the current draft and your review criteria. This reduces the chance that an abandoned idea from an earlier exchange returns later.

When an answer misses the mark, change one meaningful variable. Add a missing audience detail, narrow the section job, provide a better sample, or clarify the output. Do not keep typing “try again” without saying what failed. Iteration works when the feedback is specific enough to guide the next attempt.

A compact quality check for every prompt

  • Task: Is the requested action visible in the first lines?
  • Context: Did you include the facts that change the answer?
  • Boundaries: Is source material clearly separated from instructions?
  • Output: Can you describe and inspect the requested deliverable?
  • Review: Does a person decide what to keep and verify?

If a prompt fails this check, repair the missing part instead of adding decorative language. A useful writing prompt should make the editorial decision easier to see.

Frequently asked questions

Should I use all seven ChatGPT writing prompts for every piece?

No. Use the patterns that match the risk and complexity of the assignment. A short internal note may need a drafting prompt and a quick revision. A sourced public guide benefits from an outline, controlled drafting, revision diagnosis, and a claim audit.

Can one long prompt replace the whole workflow?

It can contain the same instructions, but that removes your chance to approve the angle, outline, and evidence before drafting. Separate prompts are most useful where a human decision changes the next step. Combine stages only when the task is simple and the result is easy to check.

Do detailed prompts guarantee accurate writing?

No. Detail can clarify the task and format, but it does not guarantee factual accuracy. ChatGPT may still produce incorrect information or fabricated references. Verify important claims and citations at their original sources.

What should I do when ChatGPT changes my meaning during revision?

Return to the original passage and identify the exact claim, qualification, or term that must stay. Ask for the smallest useful edit, preserve named facts and citations, and compare the revised paragraph line by line. If the change still alters the meaning, keep your original wording.

Sources and editorial boundary

The seven templates above are practical editorial examples created for this guide. OpenAI documents the underlying prompting and accuracy principles, but it does not present these seven patterns as official commands or promise a particular writing outcome.

Custom GPTs for Repeated Tasks: A Practical Setup Guide

0

A custom GPT is useful when you keep repeating the same setup in new ChatGPT conversations. Instead of pasting the same role, reference notes, output rules, and opening questions each time, you configure a version of ChatGPT for one defined purpose. That can make a recurring task easier to start and easier to review. It does not turn ChatGPT into reliable software, remove the need for judgment, or guarantee that every answer follows the configuration.

OpenAI describes GPTs as versions of ChatGPT configured for a specific purpose. They can combine instructions, uploaded knowledge, selected capabilities, apps, or actions. The practical question is not whether you can build one. It is whether the work is stable enough to deserve a reusable configuration. This guide uses only current OpenAI documentation for product behavior and keeps plan and workspace claims conditional where OpenAI does.

Start with the shape of the work

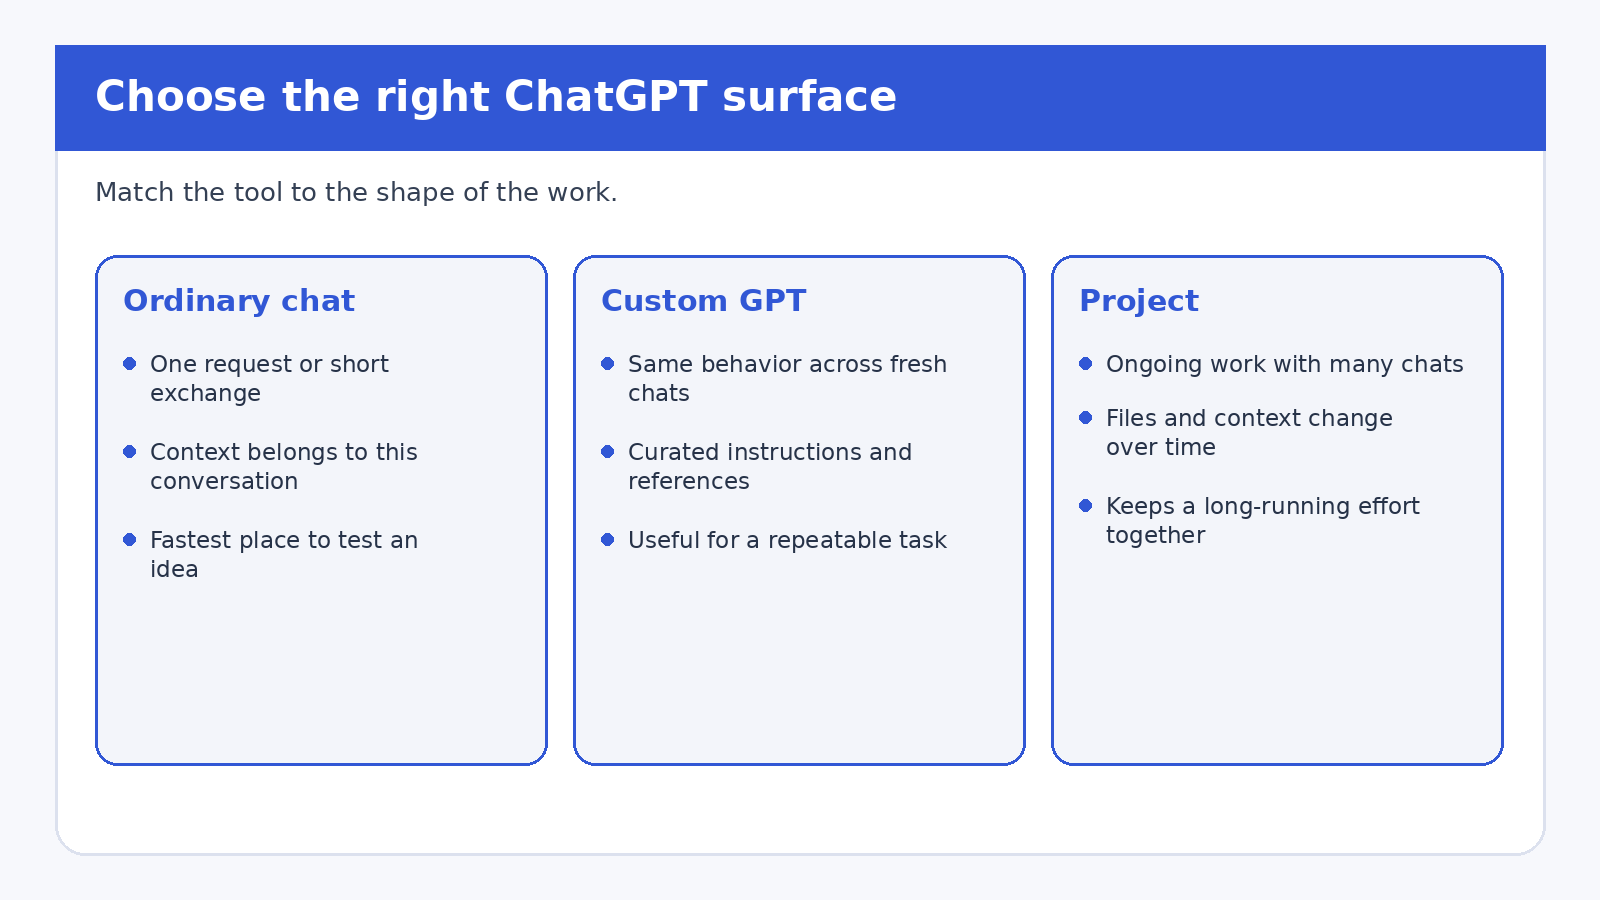
Use an ordinary chat when the request is temporary, the context is small, or you are still discovering what you need. A custom GPT makes more sense after you have repeated a task enough to identify stable rules. A Project is usually the better home for a long-running effort whose chats, files, and context keep changing over time.

Decision chart comparing ordinary ChatGPT chats, custom GPTs, and Projects for repeated work

The distinction matters because these surfaces solve different problems. According to OpenAI’s overview of GPTs in ChatGPT, custom GPTs are tailored versions of ChatGPT that start each conversation fresh. They do not use saved memory, global custom instructions, or previous conversations. A GPT can still be reused, but its continuity comes from its configuration, not from remembering earlier sessions.

OpenAI’s Projects documentation describes Projects as workspaces that group chats, files, and instructions around an ongoing effort. Project memory can draw on conversations inside that project, subject to the documented memory mode and account or workspace settings. If you are managing a research project over several weeks, a Project can preserve the evolving context. If you want a fresh assistant to apply the same editorial checklist whenever anyone opens it, a custom GPT is the clearer fit.

An ordinary chat remains underrated. Build nothing until a simple conversation proves that the task has a repeatable shape. Draft your instructions in a regular chat, try them on several examples, and note the decisions you keep correcting. Those corrections are the raw material for a useful GPT.

A five-question fit test

A task is a reasonable custom GPT candidate when you can answer yes to most of these questions:

  1. Does the task recur? You perform substantially the same job in separate conversations, such as checking a brief against a house style or explaining a fixed policy handbook.
  2. Are the rules stable? The desired behavior can be written as clear steps, boundaries, and output criteria rather than reconstructed from changing history.
  3. Can a user verify the result? Someone can check the answer against a source, calculation, checklist, or professional review.
  4. Is a fresh start acceptable? The task does not depend on the GPT remembering last week’s conversation.
  5. Can the data be handled safely? The intended users are authorized to provide the material, and any external service involved is understood and trusted.

Do not build a GPT merely to give a one-off prompt a permanent icon. A narrow GPT that handles one recurring job is easier to test than a general “company assistant” with vague authority. It also creates fewer opportunities for conflicting instructions and accidental disclosure.

Write instructions as an operating procedure

Instructions define behavior. OpenAI’s current creating and editing GPTs guide recommends explicit step structure for multi-step workflows, positive and concrete directions, clear sections, and examples when the GPT must apply definitions or classifications. Translate your task into an observable procedure.

A workable first draft can include these sections:

  • Purpose: one sentence naming the task and intended user.
  • Required input: what the user must provide before the GPT begins.
  • Process: the order in which it should inspect, ask, compare, and respond.
  • Boundaries: decisions it must leave to a person and claims it must not invent.
  • Output: the exact sections, labels, or table columns a reviewer expects.
  • Failure behavior: what to say when information is missing, conflicting, or outside scope.

For example, a policy explainer might first identify the user’s jurisdiction and policy version, then retrieve the relevant passage, quote it with a section label, explain it in plain language, and mark any question the files do not answer. The instructions should forbid pretending that silence in the source is a rule. They should also tell the GPT to recommend an authorized human contact when the answer requires interpretation or an exception.

Conversation starters are different. They are user-facing examples that show how to begin. A starter such as “Compare this draft with our accessibility checklist” is useful only if the GPT then asks for the draft or provides a safe way to supply it. Treat starters as doors into the procedure, not as hidden instructions.

Use knowledge files for sources, not behavior

Knowledge files give the GPT reference material. Instructions tell it what to do with that material. OpenAI explicitly recommends putting rules, tone, and workflow guidance in instructions rather than burying them in uploaded files. This separation makes maintenance simpler: update the procedure when behavior changes, and replace the source file when the underlying facts change.

Choose clear, text-forward files where possible. Complex layouts can be harder for the GPT to use. OpenAI says a GPT can have up to 20 files, each up to 512 MB, but the product limit is not a target. A smaller, curated collection is easier to inspect for stale versions, duplicates, and contradictory passages. Remove old copies rather than hoping the GPT will infer which one governs.

If answers need citations to the uploaded material, say so in the instructions and specify a format, such as document title plus section heading. Then test whether citations actually point to the claimed text. A neat citation can still support the wrong interpretation. For consequential work, open the cited source yourself and check the passage.

Knowledge files also have a retention consequence. OpenAI’s File Uploads FAQ says files uploaded as custom GPT knowledge are retained until the custom GPT is deleted. Do not upload secrets, personal records, client data, copyrighted material you lack permission to use, or an internal document simply because it would make testing convenient.

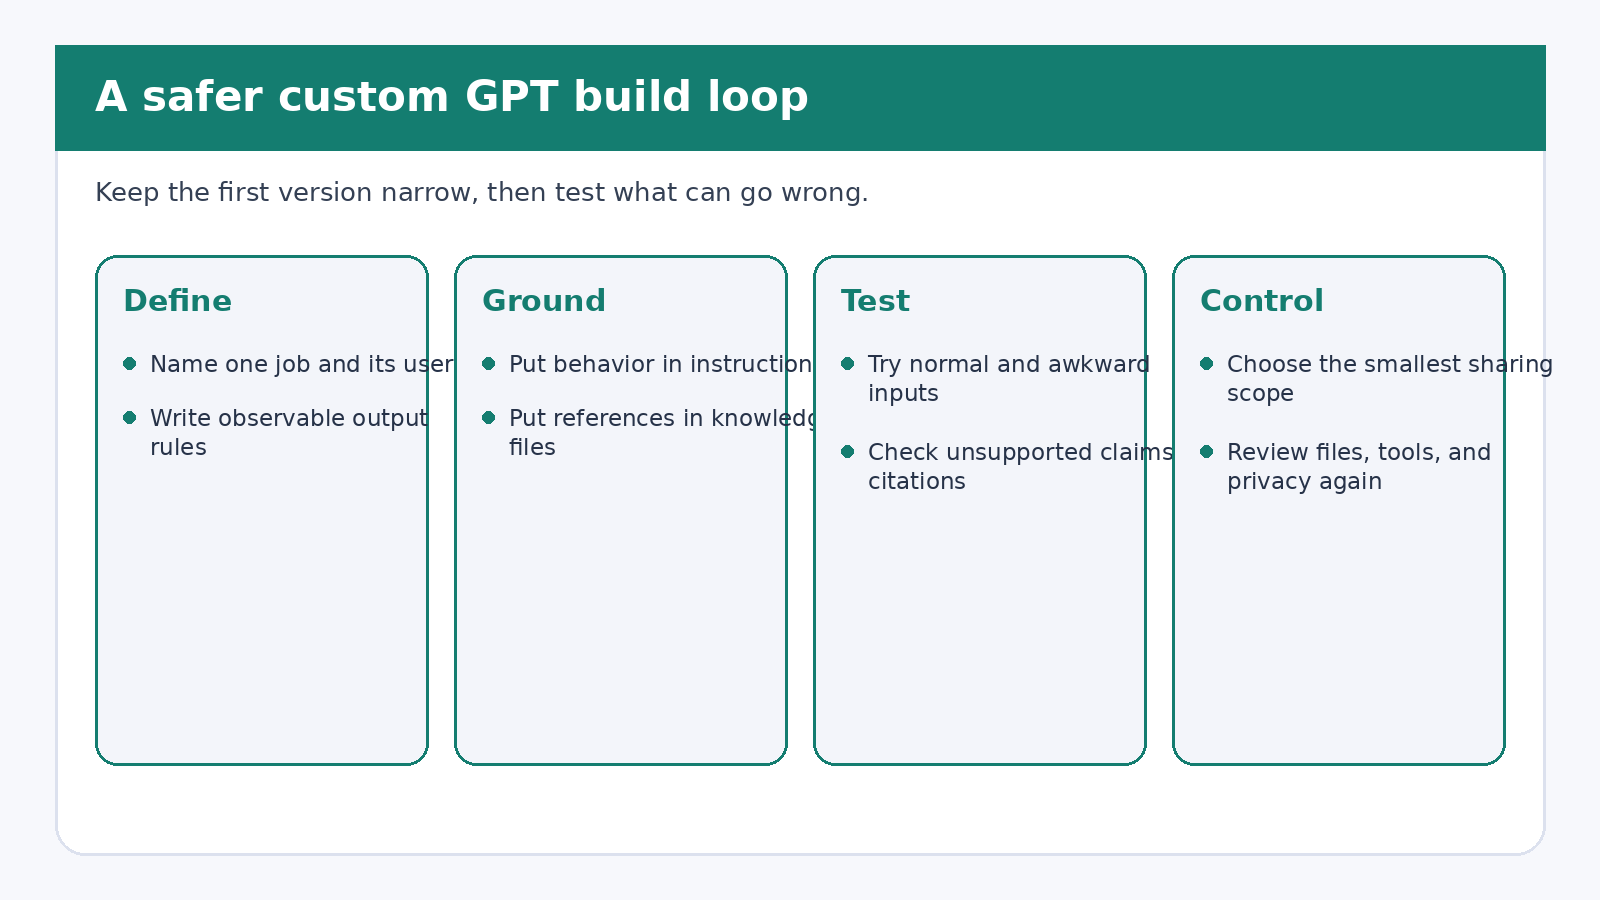
Custom GPT build loop showing define, ground, test, and control stages

Add capabilities only when the task requires them

A GPT can use selected capabilities such as web search, image generation, Canvas, or data analysis when those options are available for the account, workspace, and region. It can also connect to apps or to actions that call APIs. OpenAI notes that a GPT can use apps or actions, but not both at the same time.

Every tool widens the test surface. If a document reviewer only needs uploaded guidance and structured text output, it may not need web search or an external action. Start with instructions and knowledge. Add a capability only when you can name the input it needs, the result it should return, and the failure case a user must see.

External connections deserve special caution. OpenAI says relevant parts of a user’s input may be sent to a third-party service when a GPT uses apps or external APIs. OpenAI does not control how that service stores or uses the data. Review the service, its data practices, and the exact information the GPT might transmit. Do not assume that the GPT builder’s inability to read chats also prevents an external API from receiving data sent through an action.

Test for failure, not just a good demo

The GPT editor includes Preview, and OpenAI recommends testing there before sharing. A friendly first response is not enough. Build a small evaluation set that represents the work you expect and the mistakes you fear.

  • Try a normal, complete request and check every required output field.
  • Leave out a required input and see whether the GPT asks for it.
  • Provide conflicting source passages and check whether it exposes the conflict.
  • Ask for a fact that is absent from the knowledge files.
  • Use an edge case that should be escalated to a person.
  • If citations are required, open each cited passage and compare it with the answer.
  • If a tool can send or change data, test confirmation, cancellation, and service failure.

Record the prompts, expected behavior, actual result, and revision made. This can be a short table. Repeat the set after changing instructions, files, capabilities, or actions. Version history can help restore an earlier configuration, but a version label does not prove that the answers remain correct.

For a broader approach to checking factual output, see our guide to using ChatGPT for research without trusting made-up citations. If your main problem is reusable account-wide preferences rather than a specialized assistant, read the practical guide to ChatGPT custom instructions.

Choose the smallest useful sharing scope

Keep the GPT private while you build and test it. OpenAI documents several possible sharing levels, but the options depend on the plan, workspace settings, role permissions, and the GPT’s configuration. They may include invite-only access, workspace sharing, anyone with the link, or the GPT Store. Do not promise a sharing option until you see it in the current editor for that account.

The official sharing and publishing guide also distinguishes permission levels. Depending on the sharing level, people may only chat, may be able to view settings and duplicate the GPT, or may be allowed to edit it. Public link and GPT Store sharing do not support permission to view settings. In a managed workspace, administrators can limit or disable broader sharing.

Public publishing adds requirements. A builder profile may need completion, policy checks may apply, and public actions need a valid Privacy Policy URL. Apps can also block some public sharing or publishing choices. Publishing is a distribution decision, not evidence that the GPT is accurate, private enough for every input, or suitable for professional reliance.

Privacy boundaries users should understand

OpenAI says GPT builders cannot view individual conversations that users have with their GPTs. That is an important boundary, but it is not the whole privacy picture. Training treatment depends on the user’s plan and data controls. OpenAI says Business, Enterprise, and Edu data is not used for training by default. For consumer plans, conversations may be used depending on whether the user has opted out.

Users should still avoid entering data they are not authorized to disclose. If the GPT uses an app or action, relevant input may go to an external service. If a team shares configuration access, some permission levels can expose the GPT’s settings or permit edits. Review these paths separately instead of relying on a single “private” label.

Maintain it like a small internal tool

A useful GPT needs an owner. Set a review date for knowledge files and instructions. Keep a short note of which source version is current. Re-run the evaluation set after each change. Remove capabilities that no longer serve the task. If the GPT is shared, tell users what changed when the update affects required inputs, output format, or risk.

Retire the GPT when the process stops being stable. Move the work to a Project if it depends on accumulating chats and changing context. Use the API if you need an assistant inside a website or application, because OpenAI says custom GPTs are built and used within ChatGPT and are not an embedding mechanism. Return to ordinary chats when the task has become exploratory again.

Frequently asked questions

Do custom GPTs remember previous conversations?

No. OpenAI says GPTs do not use saved memory, global custom instructions, or previous conversations. Each conversation starts fresh. Use a Project when the work needs continuity across chats, subject to the Project’s memory settings.

Should rules go in instructions or knowledge files?

Put behavior, workflow, tone, and boundaries in instructions. Use knowledge files for reference material such as handbooks or documentation. OpenAI recommends this separation, and it makes testing and updates easier.

Can a GPT builder read users’ chats?

OpenAI says builders cannot view individual conversations with their GPTs. However, an app or external API connected to the GPT may receive relevant parts of a user’s input. Users should review and trust any connected service before sending sensitive information.

Is a custom GPT better than a Project for repeated work?

It depends on what must persist. A custom GPT applies a reusable configuration to fresh conversations. A Project keeps chats, files, instructions, and project context together for an ongoing effort. Use an ordinary chat when neither kind of reusable setup is needed.

Sources and review note

This guide was reviewed against current OpenAI Help Center pages for GPTs, creation and editing, Projects, sharing, and file uploads. It describes documented product behavior, not personal product testing. OpenAI can change features and workspace controls, so check the linked help pages and the options visible in your account before relying on a specific setting.

From Robot Demo to Real Deployment: An Industrial Robotics Evidence Checklist

0

From Robot Demo to Real Deployment: An Industrial Robotics Evidence Checklist

A robot can look flawless for ninety seconds and still be nowhere near ready for a factory or warehouse. A polished video answers a narrow question: can the machine complete this behavior under the conditions shown? A production deployment must answer a much less forgiving set of questions. Can it keep pace for a full shift, recover when the work is imperfect, coexist with people, connect to the surrounding operation, and leave behind records that help a team understand what happened?

This distinction matters more as mobile manipulators and humanoid robots move into industrial trials. The shape of the machine is not the deciding factor. A fixed arm, a collaborative arm, a mobile case handler, and a biped all face the same operational test: the robot has to become a dependable part of a larger process. Hardware is only one layer. The deployment also includes tooling, work presentation, safety functions, software, network behavior, fleet supervision, maintenance, training, and ownership inside the customer organization.

The practical way to judge progress is not to ask whether a demonstration was impressive. Ask what evidence exists. The checklist below uses only official company reports and major official documentation. Vendor figures are identified as vendor-reported results, not treated as independent audits. That attribution is important because a credible evaluation separates an observable operational fact from a supplier’s interpretation of it.

1. Start with a production-shaped task

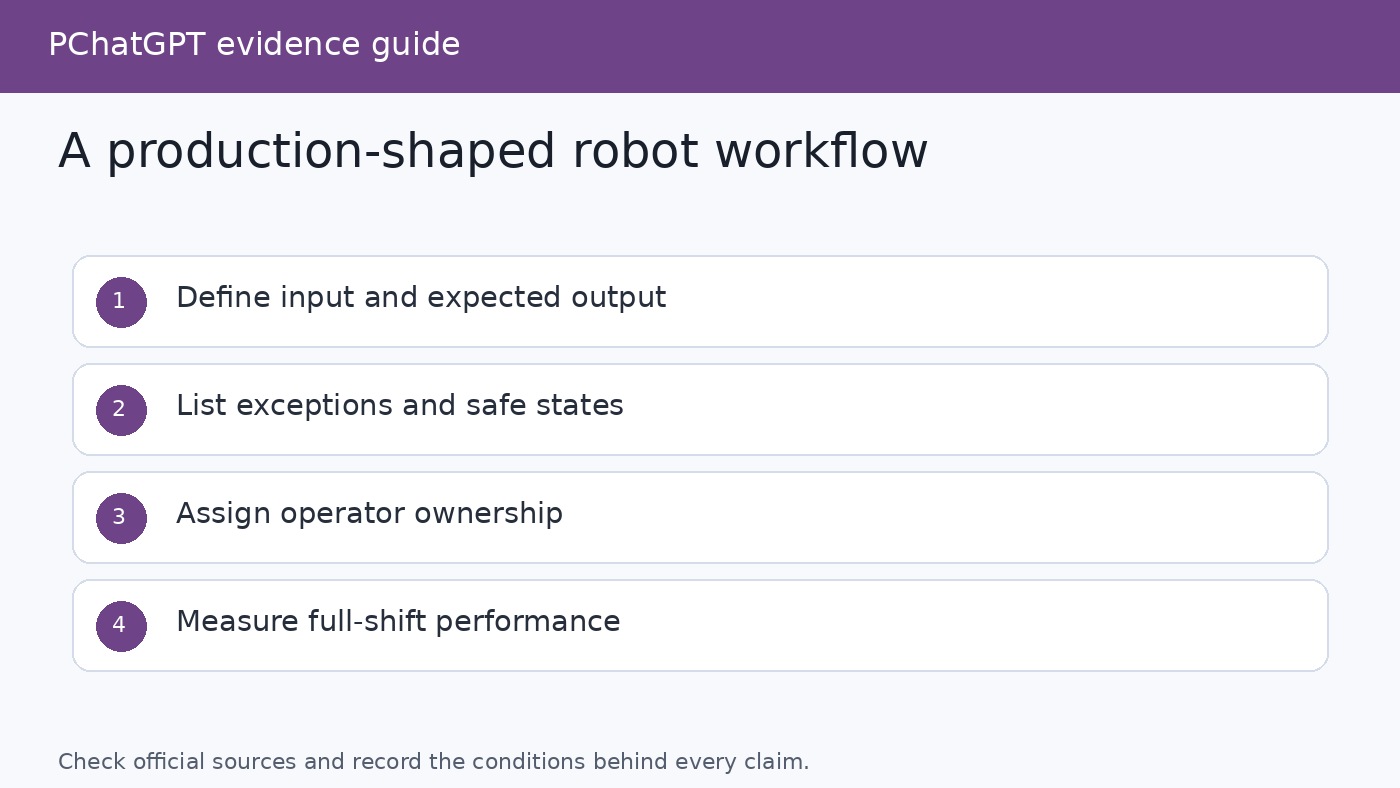
A demo often begins with a capability, then searches for an attractive scene. A deployment begins in the opposite direction. It identifies a bounded piece of work with a clear input, output, takt requirement, exception path, and human owner. “Handle boxes” is not a production specification. “Unload eligible cases from these trailer types onto this conveyor during these shifts” is much closer.

Look for a written task envelope. It should describe object dimensions and weights, presentation variability, lighting, floor conditions, reach limits, required placement tolerance, upstream arrival pattern, and downstream capacity. It should also say what is excluded. An honest exclusion is useful evidence. It shows that the team knows where autonomous operation ends and where another process must take over.

Figure’s official account of its Figure 02 work at BMW Group Plant Spartanburg offers a concrete example of production-shaped measurement. Figure says the use case loaded three sheet-metal parts onto a welding fixture. The company identified three critical KPIs: total cycle time, correct loading of all three parts, and human interventions. It reported an 84-second total cycle requirement, a 37-second load phase, a target above 99 percent successful placement per shift, and a goal of zero interventions per shift. Those details are more informative than a statement that the robot can perform pick and place. They connect the motion to the line’s acceptance conditions.

Before approving a trial, require the same clarity. What event starts a cycle? What counts as complete? When does the system time out? What conditions cause a safe stop? Who deals with a rejected object? If these questions have no precise answers, the project is still exploring a behavior rather than operating a process.

Industrial robot deployment workflow showing defined inputs, outputs, exceptions, and operator ownership
A production review should connect each robot cycle to a defined input, accepted output, exception path, and accountable operator.

2. Demand shift-level evidence, not a best run

Peak speed is seductive because it fits neatly in a caption. Operations teams need distributions. They need completed cycles per hour by shift, intervention frequency, downtime by cause, restart time, and the share of incoming work that falls inside the robot’s envelope. A single successful cycle tells you nothing about drift, thermal limits, depleted batteries, dirty sensors, changing illumination, congested aisles, or awkward objects that arrive late in the shift.

The strongest public deployment reports expose duration as well as output. Figure says its BMW deployment ran ten-hour shifts from Monday through Friday and accumulated more than 1,250 runtime hours. It also reports more than 90,000 loaded parts and a contribution to production of more than 30,000 X3 vehicles. These are Figure’s own figures, but their structure is useful: runtime, schedule, task output, and connection to finished production appear together.

Agility Robotics uses a different cumulative unit. In November 2025, the company reported that Digit had moved more than 100,000 totes at GXO’s Flowery Branch facility. Agility describes the work as part of an existing operational workflow, including interaction with proprietary facility systems, rather than an isolated behavior. The milestone does not reveal every reliability statistic a buyer would need, but it is stronger evidence than a staged tote transfer because it represents repeated work in a live facility.

Boston Dynamics and DHL provide another useful pattern. In a May 2025 joint announcement published by Boston Dynamics, the companies said deployed Stretch robots had reached case unloading rates of up to 700 cases per hour. The same announcement states that commercial introduction at DHL Supply Chain began in North America in 2023 and later expanded to the United Kingdom and continental Europe. “Up to” is not an average and should never be rewritten as one. Still, a named task, customer, deployment history, and measured rate create a trail that evaluators can investigate.

For an internal gate review, ask for at least median and lower-percentile throughput, not only the fastest hour. Break downtime into robot faults, blocked upstream flow, full downstream equipment, planned breaks, network loss, and operator-caused pauses. Otherwise the team may optimize the robot while the cell remains unproductive, or blame the robot for time when no eligible work was available.

3. Count interventions and test recovery

Autonomy is not a yes-or-no label. A robot that finishes 99 cycles alone and needs a specialist for the next one has a different operating model from a robot that needs a nearby associate every ten cycles but can be reset in seconds. Both the frequency and the cost of intervention matter.

Define intervention levels before collecting results. A simple operator reset might be Level 1. Clearing an object or adjusting work presentation might be Level 2. Remote engineering support could be Level 3. A hardware replacement or safety investigation could be Level 4. Record who performed the action, how long normal flow was interrupted, and whether work in process had to be discarded or rerouted.

Recovery tests should be deliberate. Present a missing part, a shifted container, an unreachable object, a blocked path, a communications interruption, and an emergency stop followed by the approved restart procedure. Confirm that the machine reaches a safe state, communicates the reason in language an operator can act on, and resumes without corrupting task state. A deployment that only works while nothing goes wrong is a long demonstration.

Figure’s BMW account is revealing because it discusses a failure-prone subsystem rather than presenting an entirely frictionless story. Figure identifies the forearm as Figure 02’s top hardware failure point at the site and says lessons from that subsystem informed a redesign of Figure 03 wrist electronics. The company says it removed a distribution board and dynamic cabling so each wrist motor controller communicates directly with the main computer. Whether or not another project uses similar hardware, the general evidence pattern is valuable: field failure, identified cause area, design response, and a path to verifying the revised system.

4. Treat safety as an application property

A safe robot component does not automatically produce a safe application. The gripper, payload, fixtures, conveyors, traffic pattern, maintenance access, and foreseeable human behavior all affect risk. This is why a production review should reject vague statements such as “the robot is collaborative” as a complete safety case.

The official ISO page for ISO 10218-2:2025 describes requirements for industrial robot applications and robot cells across integration, commissioning, operation, maintenance, decommissioning, and disposal. It also emphasizes the integration of the robot with end effectors and other system components. The practical lesson is straightforward: safety work follows the complete application lifecycle, not just the robot purchase.

Require a documented risk assessment for the actual site and use case, with identified hazards, protective measures, validation records, residual risks, and operating procedures. Include normal production, teaching, clearing jams, cleaning, tool changes, battery or energy isolation, maintenance, and decommissioning. Verify emergency stop behavior and restart conditions at the integrated cell level. Record changes, because a new payload, faster motion, altered route, or revised gripper can invalidate an earlier assumption.

Safety evidence also includes usability. Operators need unambiguous status indications and a known escalation path. Maintenance staff need controlled access and isolation procedures. Supervisors need to know when the robot is unavailable and how work will continue. If safe recovery routinely requires a robotics engineer, scale will be constrained even when the underlying protective functions work correctly.

5. Verify integration with the whole operation

Real work crosses boundaries. A warehouse robot may receive jobs from a warehouse management or execution layer, negotiate access to a conveyor, coordinate with autonomous mobile robots, and report completion. A factory robot may need part identity, fixture state, line permission, quality results, and traceability records. Manual job entry during a demo can hide most of this burden.

Ask for an interface inventory with owners, schemas, timing assumptions, authentication, retry behavior, and behavior during partial failure. Test duplicate messages, stale jobs, unavailable downstream equipment, clock errors, and delayed acknowledgments. Make idempotency explicit so a retried command does not create a duplicate move or duplicate production record.

Middleware configuration can affect whether the robot merely works on a lab network or behaves predictably on a site network. The official ROS 2 Jazzy documentation explains that Quality of Service policies cover history, queue depth, reliability, durability, deadline, lifespan, and liveliness. It also documents events for missed deadlines, lost liveliness, and incompatible QoS. If ROS 2 is part of a system, those policies should be selected and tested per data stream rather than accepted blindly. A high-rate sensor feed may tolerate lost samples, while a task-state transition may require a different delivery policy.

Integration should also be observable. Correlate a business job ID with robot actions, cell events, errors, and final disposition. Use synchronized timestamps. Keep enough diagnostic context to reproduce failures without recording more personal or operational data than necessary. This resembles the discipline required when teams build AI agents that actually work in production: tool access is only the beginning, while state, permissions, recovery, and evaluation determine whether the system can be trusted.

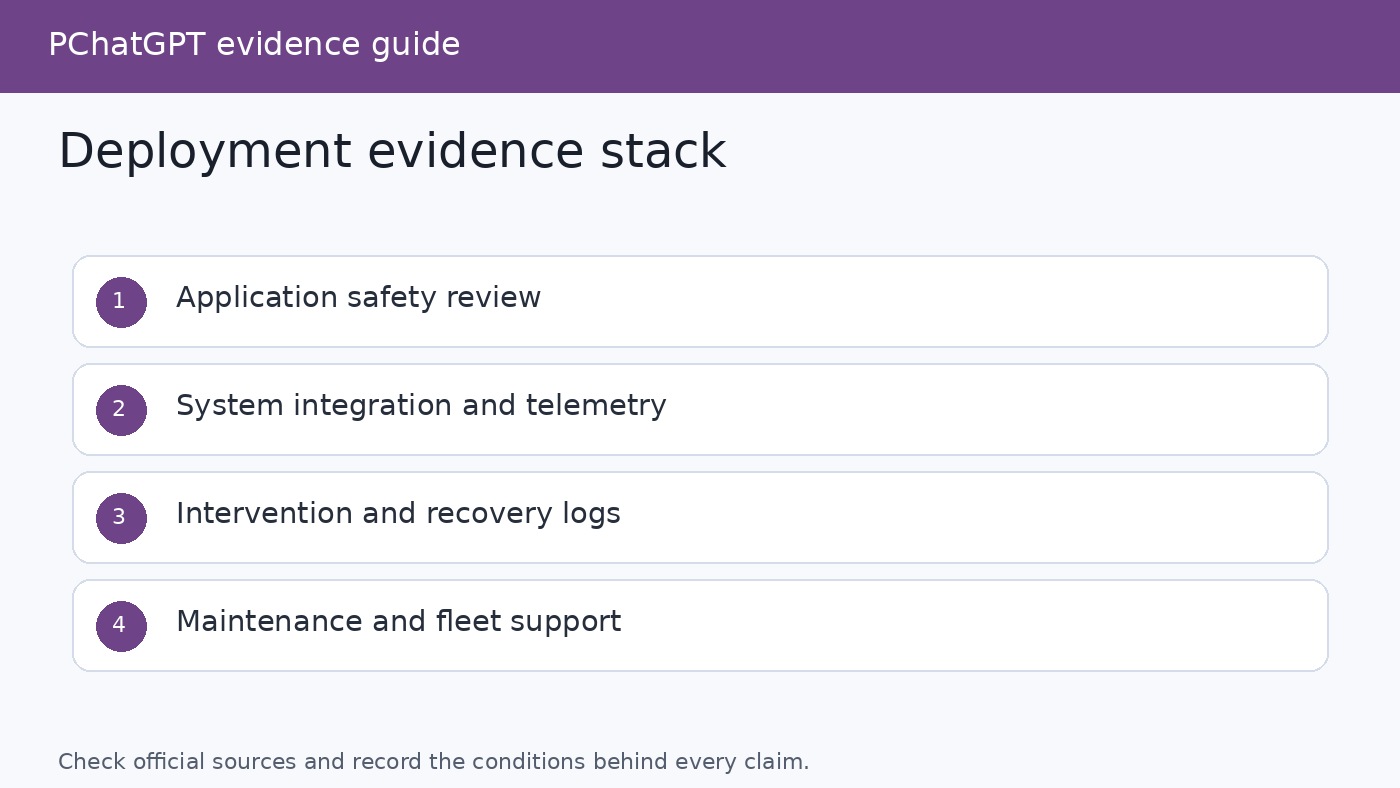
Industrial robotics evidence stack covering safety, integration, telemetry, recovery, and fleet operations
Deployment evidence spans the robot, safety system, site interfaces, telemetry, recovery workflow, and the people responsible for daily operation.

6. Prove operability, maintenance, and fleet control

The buyer is not acquiring a video. The buyer is accepting a long-lived asset with software versions, replacement parts, calibration needs, batteries, wear items, security credentials, and support obligations. A serious deployment plan therefore names the people who can start, stop, inspect, reset, and maintain the system on every operating shift.

Ask what the operator sees when performance degrades. Is the alert actionable? Can first-line staff distinguish blocked work from a robot fault? What is the expected time to acknowledge, diagnose, and restore service? Which repairs happen on site, which require a field technician, and which require depot return? Are spare modules stocked near the facility? Is there a tested rollback if a software update reduces performance?

Fleet operation adds another layer. Teams need controlled rollout groups, configuration tracking, health monitoring, job allocation, audit logs, and a way to remove a unit from service without confusing the work scheduler. Agility says its Arc platform supports facility mapping, workflow definition, operational management, and troubleshooting for Digit fleets. That is an official product claim, not proof that every deployment has the same configuration. It does, however, show the categories of capability a buyer should demand and validate.

Cybersecurity belongs in the same review. Official ROS 2 security documentation says ROS 2 can use underlying DDS security capabilities for authentication, encryption, and access-control policies, with configuration files for graph participants. Enabling a feature is not the same as completing a threat model. Inventory identities and certificates, restrict privileges, define credential rotation and revocation, protect update paths, log administrative actions, and decide how the cell behaves if a cloud or remote-support connection is lost.

7. Build an acceptance gate that can say no

A pilot needs exit criteria before installation. Without them, every result can be reframed as learning and the trial can continue indefinitely. Set thresholds for safe operation, throughput, quality, intervention rate, availability, recovery time, eligible-work coverage, and support response. Specify the measurement window and excluded downtime in advance.

The gate should compare the automated process with the real alternative, including the surrounding labor and equipment. Count loading, exception handling, inspection, supervision, maintenance, floor space, integration effort, spares, and expected upgrades. Do not hide these items behind a headline cycle rate. Equally, do not ignore improvements that are central to the use case, such as reducing work in difficult trailer conditions. Boston Dynamics and DHL explicitly connect Stretch deployment with reducing physically demanding unloading in hot or cold trailers. That outcome should be measured with an agreed operational indicator rather than left as a slogan.

Use staged gates. First, validate the task envelope off line. Next, run on site without controlling production. Then operate a limited shift with an approved fallback. Extend to representative shifts and product mixes. Finally, transfer routine ownership to operations and maintenance. A technical team standing beside the machine can be appropriate during commissioning, but it should not be mistaken for the steady-state staffing model.

The decision can be “scale,” “revise and repeat,” or “stop.” A stop is not necessarily a failure. It may show that work presentation needs redesign, the current robot is mismatched to the task, or integration cost exceeds the value. Honest gates protect both the plant and the robotics supplier from an endless showcase.

8. Read public deployment claims with precision

Official examples are useful, but they are still selected by the organizations publishing them. Read the verbs carefully. “Tested,” “piloted,” “deployed,” “commercially introduced,” and “planned” describe different levels of commitment. A memorandum of understanding is not the same thing as completed installations. Boston Dynamics’ 2025 announcement says the DHL agreement paves the way for more than 1,000 additional units. The completed evidence in that release is the prior deployment history and reported unloading performance, while the additional units are forward-looking.

Likewise, cumulative item counts need context. Ask how many robots contributed, over what period, across which shifts, with what intervention rate, and against which eligible work. A large total proves repetition but does not by itself establish availability or economics. A long runtime number is stronger when paired with fault categories and output quality. A customer logo is not an acceptance test.

This careful reading is also useful when assessing software that acts in digital environments. Our review of AI browser agents similarly distinguishes an advertised capability from the controls and fit needed for actual work. In physical automation, the stakes include moving machinery, production interruption, and maintenance access, so the evidence bar must be at least as explicit.

A compact deployment evidence pack

Before calling a robotics project a production deployment, request one evidence pack that an operations leader can review without reconstructing the story from slide decks:

  • Use-case specification: task boundary, eligible work, exclusions, takt, quality requirement, and fallback flow.
  • Safety file: application risk assessment, protective measures, validation, procedures, training, residual risks, and change history.
  • Performance report: shift-level throughput distribution, quality, availability, interventions, recovery time, and downtime causes.
  • Integration map: upstream and downstream systems, interface ownership, data contracts, timing, retries, and degraded modes.
  • Operations plan: roles by shift, alerts, escalation, remote support, maintenance intervals, spares, and service targets.
  • Software and security record: versions, configuration, identities, permissions, update process, rollback, logs, and incident response.
  • Acceptance decision: thresholds, measurement window, actual results, open risks, accountable signatories, and the next gate.

A demo proves possibility. A deployment proves repeatability inside someone else’s constraints. The most persuasive robot is therefore not the one with the most cinematic motion. It is the one whose team can show where it works, where it does not, how often people step in, what happens after a fault, how safety was validated, and who owns Monday morning.

Frequently asked questions

What is the clearest sign that a robot has moved beyond a demo?

The clearest sign is sustained operation against predefined production acceptance criteria, with recorded throughput, quality, interventions, downtime, and recovery. A named customer or a large item count helps, but neither replaces shift-level evidence and an approved operating process.

How long should an industrial robot pilot run?

There is no universal duration. It should run long enough to cover representative shifts, work mixes, operators, environmental variation, maintenance events, and credible faults. The correct endpoint is evidence coverage, not an arbitrary number of calendar days.

Does a collaborative or humanoid form make the application safe?

No. Safety depends on the integrated application, including tooling, payloads, motion, surrounding equipment, access, and foreseeable human interaction. ISO 10218-2:2025 addresses industrial robot applications and cells across integration and their lifecycle, which is why a site-specific risk assessment and validation are essential.

Which metric matters most when evaluating production readiness?

No single metric is sufficient. Throughput without quality is misleading, and availability without eligible-work coverage can hide a narrow task envelope. A useful minimum set combines output quality, cycle-time distribution, availability, intervention frequency, recovery time, and safety performance.

Sources

Meta AI Across Consumer Apps: What Runs on Your Device and What Uses the Cloud

0

Meta AI Across Consumer Apps: What Runs on Your Device and What Uses the Cloud

Meta AI now appears across several familiar consumer products, but that does not mean every answer is generated on your phone. This guide separates the assistant people use in Meta apps from the lightweight Llama models that developers can run locally, then explains what that distinction means for privacy, speed, availability, and everyday use.

Meta AI can feel like one continuous assistant because it is accessible through WhatsApp, Instagram, Facebook, Messenger, the web, a standalone app, and supported AI glasses. The interface may sit inside an app on your phone, but the location of the interface does not tell you where the underlying computation happens. A chat box is local software. Generating an answer may still require remote infrastructure, web search, account context, or another online service.

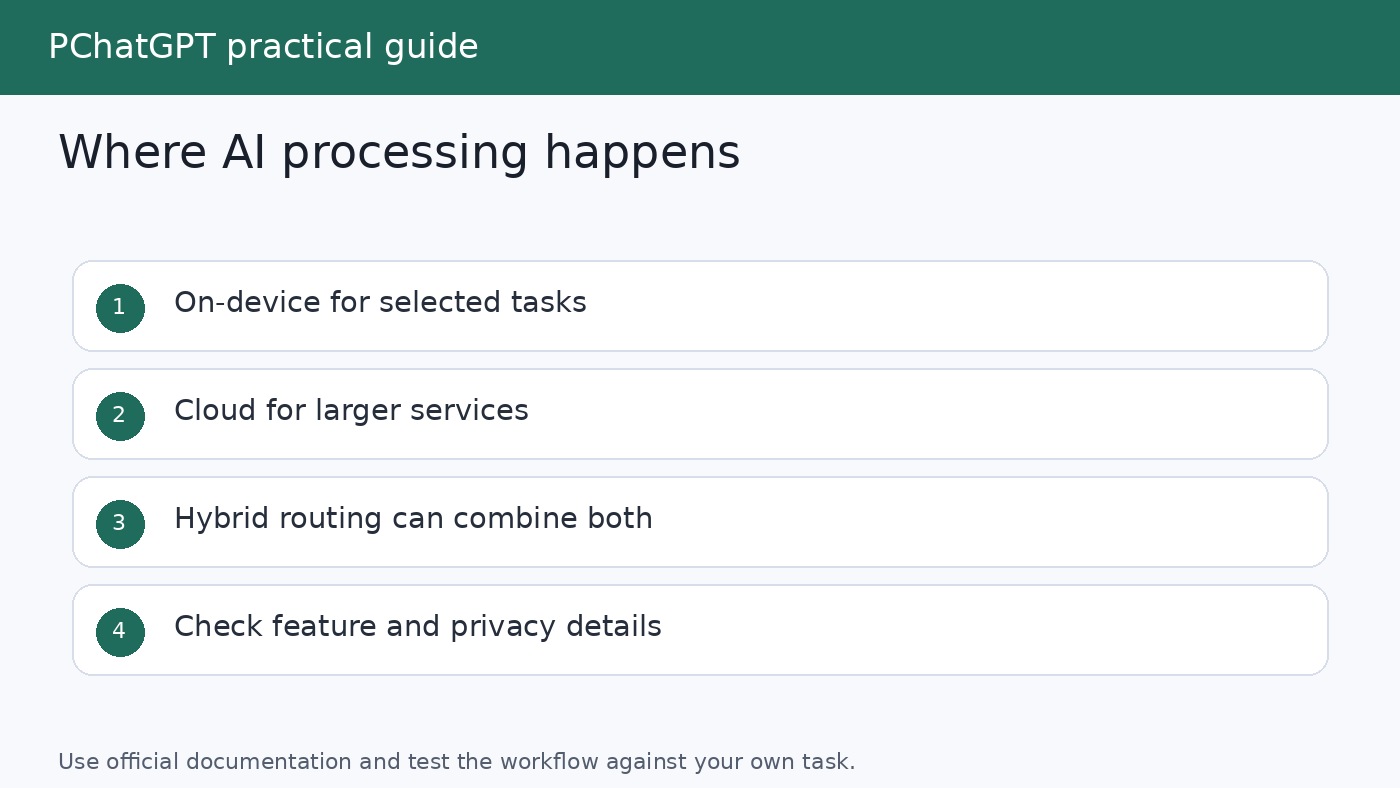
That distinction matters. The phrase on-device AI has a specific technical meaning: a model or task runs locally on the phone, computer, glasses, or other hardware in front of you. Cloud AI sends a request to remote servers for processing. A product can also use a hybrid design, keeping some work local while sending harder tasks to a larger model in the cloud. Meta has published lightweight Llama models intended for local use, but this alone is not evidence that every Meta AI feature in every consumer app runs locally.

The safest reading of Meta’s official material is therefore simple. Meta is expanding access to its AI assistant across consumer apps and devices. Separately, it offers Llama models that developers and hardware partners can deploy on selected edge and mobile devices. Those are related parts of Meta’s AI strategy, not interchangeable claims.

Meta AI is a service across several surfaces

Meta’s April 2024 announcement described Meta AI in Facebook, Instagram, WhatsApp, and Messenger, as well as on the Meta AI website. It highlighted uses such as answering questions, helping with planning, finding information from the web, and generating images. Access was being rolled out by country, language, and feature, so the announcement should not be treated as a promise that every function is present for every account.

Meta added a standalone Meta AI app in April 2025. According to the company, that first version was built with Llama 4 and focused strongly on voice conversations. The app also connected with image generation and editing, included a Discover feed, and could provide personalized responses in supported markets. Meta said that nothing was posted to the Discover feed unless the user chose to share it.

Meta AI assistant shown across WhatsApp, Instagram, Facebook, Messenger, web, and the standalone app

The standalone app also took over companion duties associated with Ray-Ban Meta glasses. Meta described continuity among the app, the web, and glasses, but with a limit: a conversation could begin on the glasses and later appear in app or web history, while a conversation begun in the app or on the web could not simply be resumed on the glasses. This is a useful example of why an apparently unified assistant can still behave differently on each surface.

Consumers should think of these surfaces as doors into a broader service. Each door can offer its own controls, input methods, account context, and regional availability. The visible experience can change without establishing that the model itself moved onto the local device.

What on-device, cloud, and hybrid AI actually mean

In a genuinely local workflow, the device stores the relevant model and performs inference using its own processor and memory. A well designed local feature can respond with low latency, work without sending the prompt to a remote model, and continue functioning when connectivity is limited. These benefits depend on the exact app and implementation. Merely downloading an app does not make its AI local.

Cloud processing gives a service access to larger models, more computing capacity, web retrieval, shared safety systems, and frequently updated tools. It also means the service must transmit at least the information needed to fulfill a request. Features that search the live web, synchronize conversations between devices, or use remote account context are strong signs that the overall experience involves online services, even if some supporting operations happen locally.

A hybrid system divides the work. A small local model might classify a request, summarize private text, or decide whether a larger model is needed. The device can then send selected tasks to the cloud. Meta’s Llama 3.2 announcement explicitly presented this as an application design option: developers can control which queries remain on the device and which need a larger cloud model.

Hybrid architecture is not a single privacy guarantee. Its value depends on what stays local, what leaves the device, what is retained, and which controls are available. Those details must come from documentation for the specific feature. A general statement about a model family cannot answer them for every consumer product.

What Meta’s official sources confirm, and what they do not

Meta released lightweight, text only Llama 3.2 models with 1 billion and 3 billion parameters in 2024. The company said these models could fit on selected edge and mobile devices. It described potential developer uses such as summarizing recent messages, extracting action items, and calling tools. Meta also named Arm, MediaTek, and Qualcomm among its on-device partners for that release.

That announcement supports a precise statement: some Llama models are designed to support local applications on selected hardware. It does not support the much broader statement that Meta AI across WhatsApp, Instagram, Facebook, Messenger, the standalone app, or glasses performs every generative task on the device. Llama is a family of models and a foundation for products. Meta AI is a consumer assistant with its own interfaces, services, and integrations.

Meta’s December 2024 review reinforced the range of possible deployments. It said Llama could be optimized for on-device and on-premises use, as well as managed service APIs from cloud partners. In the same article, Meta discussed Meta AI across apps, the web, and Ray-Ban Meta glasses. The important point is range, not uniformity. A model ecosystem can support local, private infrastructure and public cloud deployments at the same time.

Diagram comparing on-device AI, cloud AI, and a hybrid workflow that routes selected requests

The Meta AI app announcement offers further clues about service dependencies. Meta said its standard assistant could search the web and provide recommendations, and that personalized answers could draw on information people had chosen to share on Meta products in supported markets. It separately described an experimental full duplex voice demo that did not have web or real time information. These distinctions show that capabilities can depend on the selected mode, country, and product version.

Do not infer processing location from model size, marketing language, or the hardware used to open the assistant. Look for a direct statement that a named feature processes a named category of data locally. If Meta does not make that statement for the feature you are using, assume that an online assistant may contact Meta’s services.

Why the distinction matters to everyday users

Privacy: Local processing can reduce the need to transmit a prompt, but privacy depends on the whole workflow. A local model can still connect to online tools, backups, analytics, or account services. Conversely, a cloud feature can provide meaningful controls and safeguards while still requiring data transfer. The useful question is not simply whether an app contains AI. Ask what information the specific feature receives, where it is processed, how it is used, and what controls apply.

Connectivity: A truly local function may work without a network after its model and required assets are installed. Meta AI features that depend on web search, server models, or synchronized history need connectivity. Users should not assume that an assistant available on a phone is fully available offline.

Performance: Local models can avoid a network round trip, while cloud models can use much more computing power. Actual response time also depends on the device, connection, model, prompt, and product design. There is no honest universal claim that one approach is always faster.

Capability: Lightweight models are practical for constrained tasks, but a larger remote model may handle more complex requests. A hybrid product can route tasks according to difficulty or sensitivity. That choice can change over time as software and hardware improve.

Battery and storage: Local inference consumes device resources and model files occupy storage. Cloud inference shifts much of the computation away from the device but still uses the network and client software. Product documentation and device settings are the right places to check actual requirements.

Use Meta AI with clear privacy boundaries

Meta’s privacy explanation says that information shared directly with its generative AI features can be used to provide responses and improve products, among other stated purposes. It also says certain questions may be shared with trusted partners, such as search providers, to supply relevant and current answers. This is a good reason not to enter passwords, financial account details, confidential work material, private health records, or another person’s sensitive information into a general assistant.

Private messages with friends and family are not the same as messages intentionally sent to an AI. Meta’s updated privacy article says it does not use private messages with friends and family to train its AIs unless someone in the chat chooses to share those messages with an AI feature. It also states that, in supported group chat behavior, Meta AI reads messages that invoke it rather than the rest of the conversation. Users should still review the current notice and controls shown inside their own app because policies and product behavior can change.

Personalization deserves separate attention. Meta said the standalone assistant could remember details that a user provides and, in supported markets, draw on profile information and content the person has engaged with. Accounts connected through Accounts Center may provide more context. Personalization can make answers more relevant, but users should decide whether that tradeoff fits the task before sharing details.

Generated answers can also be incomplete or wrong. Use the assistant for drafts, exploration, and low stakes planning, then verify consequential information with primary sources. A polished response is not proof of accuracy, and access to web search does not remove the need to check citations.

A practical checklist before you use an AI feature

  1. Name the exact surface. Note whether you are using WhatsApp, Instagram, Facebook, Messenger, meta.ai, the standalone app, or glasses. Controls and capabilities can differ.
  2. Check the current in-app notice. Availability varies by country, language, account, device, and rollout stage. An older announcement is context, not a live compatibility list.
  3. Look for explicit local processing language. Terms such as “on your phone” or “available in the app” are not enough. Find documentation that says the relevant processing occurs on the device.
  4. Review personalization and history controls. Understand whether conversations are saved, whether memory is active, and which linked account information may inform responses.
  5. Limit sensitive input. Share only the minimum information needed for the task.
  6. Verify important output. Check source documents for medical, legal, financial, safety, travel, or purchasing decisions.

If your priority is a local model that you control, read our guide to local LLM tools and models. For a broader framework focused on fit rather than brand recognition, see the guide to choosing AI apps. Mobile users can also compare practical categories in our mobile AI apps guide.

The bottom line

Meta is making its assistant easier to reach across apps, the web, and connected devices. It is also developing small Llama models that can run locally in applications built for compatible hardware. Both developments are real, but combining them into the claim that all Meta AI is on-device would be inaccurate.

For consumers, the right model is feature by feature. Treat Meta AI as an online service unless the documentation for your exact feature clearly says that its processing stays local. Then review data controls, personalization, connectivity, and availability in the product you actually use. That approach is less dramatic than a sweeping label, but it is far more useful.

Frequently asked questions

Does Meta AI run entirely on my phone?

Do not assume that it does. Meta has released lightweight Llama models that developers can run on selected devices, but its official consumer announcements also describe features that use web search, synchronization, personalization, and online services. Check the documentation for the exact app and feature before treating processing as local.

Is Llama the same thing as Meta AI?

No. Llama is Meta’s family of AI models. Meta AI is a consumer assistant built with models from that family and delivered through apps, the web, and devices. A Llama model can also be used by developers in products that have nothing to do with the Meta AI consumer interface.

Can Meta AI read every message in a group chat?

Meta’s privacy explanation says that its conversational AI in WhatsApp, Instagram, or Messenger reads messages that invoke Meta AI in the supported group chat flow, not every other message in the conversation. Product behavior and controls can evolve, so review the current information presented inside your app.

Will Meta AI work without an internet connection?

Some independently built applications using a local Llama model may be able to perform supported tasks offline once everything is installed. That does not establish offline support for Meta AI itself. Features that rely on cloud models, web information, account context, or synchronized history need an online connection.

Official Meta sources

Related update: Perplexity AI Raises $1B for Answer Engine Expansion: What It Means for Global Content Creators.

Perplexity Comet browser: how to use answer engines without losing source control

0

An answer engine can save time by searching, reading, and turning several pages into a direct response. The danger is equally simple: a smooth answer can make you forget which page supported which sentence.

Perplexity’s official guide describes Comet as a Chromium-based browser with Perplexity AI built in. It also says Comet retains familiar browser functions, including bookmarks, page translation, and support for most Chrome extensions. Comet Intelligence can use browsing history for personal search, while the setup tools can import selected data from another browser.[1] Those are product features. They do not, by themselves, prove that an answer is accurate or that every cited page supports the wording you received.

This guide focuses on a practical discipline: use Comet to find, organize, and question material, but keep the evidence visible and make the final judgment yourself. Whenever this article labels a step as editorial advice, it is a recommended workflow rather than a feature promised by Perplexity.

What Comet changes, and what it does not

In an ordinary research session, the browser and the chatbot are often separate. You copy a passage, switch tabs, ask a question, then return to the source. Comet reduces some of that movement because AI assistance is part of the browser. The official documentation presents it as both a standard browser and an AI-enabled environment.[1]

That integration can make context easier to provide, especially when you want to ask about a page or a set of tabs. It can also blur the line between the text on screen, information found elsewhere, and the model’s own synthesis. A concise answer may combine those layers without making the boundary obvious in every sentence.

Editorial rule: treat Comet’s response as a research map, not as the evidence itself. The response can point you toward claims, pages, and disagreements. Your evidence remains the original material that you open, read, and record.

Workflow diagram for using Perplexity Comet while checking sources, tabs, summaries, and final notes

Define source control before you ask a question

Source control in this context does not mean software version control. It means knowing where a claim came from, what the source actually says, and whether you can reproduce the path from evidence to conclusion. You lose control when a citation looks relevant but does not support the sentence, when a summary quietly merges different dates or definitions, or when you cannot tell whether a statement came from an open tab or a broader search.

Write an evidence target

Start with a question that names the evidence you need. “Is this product good?” invites a broad opinion. “Which functions does the vendor document, and which limitations are stated on the same page?” creates a checkable task. For a comparison, specify the date, plan, operating system, and feature category where those details matter.

A useful prompt can also state what should be excluded: forum speculation, copied press releases, undated feature lists, or pages that merely repeat another article. This does not guarantee perfect retrieval. It does make your standard visible, so you can judge the result against it.

Separate discovery from verification

Use one pass to discover candidate sources and a second pass to verify claims. During discovery, ask for relevant official pages and a short explanation of why each page matters. Do not draft the final article yet. Open the candidates, discard weak matches, and note the pages that contain direct support.

During verification, work claim by claim. Ask whether the selected page supports the exact wording, not merely the general topic. A page about Perplexity as a company cannot automatically support a claim about Comet. A partnership announcement cannot establish a browser feature. Shared branding is not shared evidence.

Keep a small evidence table

Editorial advice: record four fields for every important claim: the proposed wording, the source URL, the supporting passage, and your verification status. “Verified” should mean you read the passage yourself. Use “partial” when the page supports only part of the sentence, and “remove” when the match fails.

This modest table prevents citation drift. It also makes later editing safer. If a sentence changes, you can compare the new wording with the passage instead of assuming the old citation still fits.

A controlled workflow inside Comet

1. Begin with a clean research window

Open only the tabs needed for the current question. Keep personal accounts, payment pages, private dashboards, and unrelated work outside the session. This is editorial risk control, not a statement that Comet mishandles those pages. A narrower workspace simply reduces accidental context mixing and makes it easier to see what the assistant could be using.

If you are evaluating Comet rather than adopting it, use a separate browser profile and import only what you need. Perplexity’s setup guide says users can choose which items to import, and it explains that Comet may request keychain access to store sensitive information used for password management, autofill, and Comet Intelligence.[1] Read the prompt before approving it rather than treating installation dialogs as routine.

2. Ask for a source list before a synthesis

Request candidate pages first. For example: “Find the official documentation that defines Comet, explains installation, and describes data import. Return the title and URL of each page. Do not summarize yet.” This gives you a visible retrieval stage. Open every candidate and confirm that the page is official, current enough for your task, and specific to the claim.

Only then ask for a summary based on the approved pages. Name those pages in the prompt when possible. The aim is not to force a particular answer. It is to limit silent substitution of convenient but weaker material.

3. Make the answer expose its support

Ask for one citation next to each factual statement and request a short supporting excerpt. Then check the excerpt on the source page. Citations can be wrong, incomplete, or attached at paragraph level even when only one sentence is supported. The verification step belongs to the reader.

For numerical, legal, medical, financial, or safety-related material, raise the standard. Look for a primary document, confirm the date and scope, and get qualified review where the consequences warrant it. A browser assistant can organize research, but it does not transfer responsibility away from the person publishing or acting on the result.

4. Compare the response with the live page

Do not verify from the AI’s quotation alone. Search the open page for a distinctive phrase, read the sentences around it, and check headings or footnotes that define its scope. A sentence can be copied accurately while losing an exception in the next paragraph.

Also check whether the page has changed since the answer was generated. Product documentation is especially fluid. Record an access date for claims that may change, and avoid writing permanent language such as “always” unless the source truly supports it.

5. Draft from notes, then run a claim audit

Once the evidence table is complete, draft from that table rather than from the assistant’s prose. This reduces the chance that polished but unsupported phrasing survives into your article. After drafting, underline every externally checkable statement. Each one should have direct support, be clearly framed as analysis, or be removed.

Finally, click every citation in the finished draft. Link testing catches broken URLs, redirects, and citations accidentally moved during editing. It is dull work, but it is faster than correcting a published claim.

Prompts that preserve an audit trail

The wording below is editorial guidance. It describes ways to structure requests, not guaranteed Comet behavior.

  • “List candidate primary sources for this question. Give each page title, publisher, URL, and the claim it may support. Do not write a conclusion.”
  • “Using only the tabs I name, create a table with one factual claim per row, the supporting page, an exact excerpt, and any limitation stated near that excerpt.”
  • “Review this paragraph sentence by sentence. Mark supported, partially supported, or unsupported. Explain any mismatch without rewriting the paragraph.”
  • “Find disagreement between these sources. Keep their dates, definitions, and scopes separate rather than averaging them into one answer.”
  • “Create a verification checklist for the draft. Include dates, names, figures, quotations, plan restrictions, regional limits, and links.”

Notice what these prompts avoid. They do not ask the answer engine to sound certain, fill missing details, or make the result publication-ready in one pass. They create intermediate outputs that a person can inspect.

Use Comet Shortcuts without automating judgment

Perplexity’s separate Shortcuts documentation describes reusable prompts that can be called with a slash in Comet. A shortcut can point to sources, files, or tabs, and its setup can include a search mode, model, and source. The same page says entering a shortcut does not run it automatically. You can add context before submitting it.[2]

That makes Shortcuts suitable for repeatable research checks. You might create one that asks for claim-by-claim evidence or another that flags missing dates. Keep the shortcut narrow enough to review. A long instruction that searches, judges evidence, rewrites the article, and initiates an external action may be convenient, but it hides too many decisions inside one run.

Editorial rule: automate the checklist, not the approval. Let a shortcut produce the evidence table, identify uncited sentences, or format a source list. A person should still decide whether a source is authoritative, whether the excerpt supports the claim, and whether the draft is ready to publish.

Checklist for reviewing AI browser permissions, history use, connectors, and source citations

Common ways source control breaks

A relevant citation is mistaken for supporting evidence

A page can discuss the right company and still fail to support the sentence beside it. Check the exact claim, including qualifiers. If the source says a feature is available under certain conditions, a sentence that presents it as universal goes too far.

Several sources are blended into one stronger claim

An answer engine may synthesize related material into wording that appears to have a single foundation. Split the statement into smaller claims and cite each one separately. If no individual source supports the combined conclusion, label it as your interpretation or leave it out.

Official, reported, and editorial statements are mixed

Use explicit labels. “Perplexity documents” introduces an official product claim. “A reviewer reported” identifies an outside observation. “Our recommendation” marks editorial judgment. This is more honest than giving every sentence the same authoritative tone.

The assistant becomes an action layer too soon

Research and execution have different consequences. Asking for a summary produces text you can reject. Sending a message, submitting a form, changing an account, or publishing a post affects an external system. Keep those stages separate and require a final human review before any consequential action.

How Comet fits into an AI browser comparison

Comet should be compared as both a browser and an answer-engine interface. Browser basics matter: extension compatibility, updates, imports, profile separation, and familiar navigation. Research controls matter too: visible sources, the ability to constrain context, and the effort required to verify a response.

For a broader map of product categories and trade-offs, read our guide to AI browser uses, pros, cons, and options. If you want a test-oriented framework, continue with our tested AI browser comparison. Use the same research question across products and count verification time, not only response time.

A sensible trial uses low-risk material and a separate profile. Measure whether Comet helps you locate primary documents, reduces repetitive navigation, and keeps citations easy to inspect. If the tool produces a faster first draft but adds a long verification burden, the net gain may be smaller than it looks.

A source-control checklist for every session

  1. Define the exact claim or decision you are researching.
  2. State which source types are acceptable and which are excluded.
  3. Collect candidate pages before asking for a narrative answer.
  4. Open each important source and read the relevant section in context.
  5. Record one claim, URL, excerpt, and status per evidence row.
  6. Keep official product facts separate from your own recommendations.
  7. Check dates, plans, regions, and conditions before generalizing.
  8. Draft from verified notes rather than copying the AI response.
  9. Audit every checkable sentence and click every final link.
  10. Require human approval before messages, forms, purchases, or publishing.

This process adds friction in the right place. The browser can accelerate discovery and organization, while the final claims remain tied to pages a reader can inspect.

The habit worth keeping

Comet’s integration of browsing and AI can make research feel like one continuous conversation. Use that continuity for navigation and questioning, but do not let it flatten the distinction between answer and evidence. Ask for sources early, verify them in context, and preserve a short record of how each important claim earned its place.

The best outcome is not the longest answer or the quickest summary. It is a draft whose factual sentences can be traced back to appropriate sources without guesswork. If you can reproduce that path after closing the assistant panel, you still have source control.

FAQ

Is Comet a separate browser or only a Perplexity extension?

Perplexity describes Comet as a Chromium-based browser with integrated AI capabilities. Its official getting-started guide also lists standard browser functions and support for most Chrome extensions.[1]

Can I trust every citation in a Comet answer?

No citation should be trusted solely because it appears beside an answer. Open the page, locate the supporting passage, read its context, and confirm that it supports the exact wording. This is editorial verification advice, not a claim that every Comet citation is faulty.

Should I import all my browser data into Comet?

Perplexity says the import process lets you select items from a previous browser.[1] Import only what you need for your planned use, and review permission or keychain prompts before approval. A limited trial profile is easier to audit than a complete migration.

What is the safest useful task for a first Comet test?

Try a reversible research task using public material. Ask Comet to find official pages, organize claims, and build an evidence table. Verify the output yourself. Avoid forms, purchases, publishing, or sensitive logged-in pages until you understand the controls and have decided that the workflow is appropriate.

Sources

  1. Perplexity Help Center, “Getting Started with Comet”. Official overview of Comet, installation, keychain access, default-browser setup, and data import.
  2. Perplexity Help Center, “Comet Shortcuts”. Official instructions for creating, configuring, and using reusable prompts in Comet.

Perplexity publisher program: what creators should verify before relying on AI answer traffic

0

AI answer engines are changing a familiar publishing exchange. A search engine traditionally sends a reader to a page where the publisher can present the full article, build recognition, invite a subscription, or show advertising. An answer engine may instead assemble a response from several sources and place citations beside it. A citation can lead to a publisher, but the answer may also satisfy the reader before any click happens.

Perplexity’s Publishers Program is one attempt to address that tension. The company announced the program in July 2024 with six launch partners: TIME, Der Spiegel, Fortune, Entrepreneur, The Texas Tribune, and WordPress.com. Its announcement described revenue sharing, access to Perplexity APIs and developer support, and one year of Enterprise Pro for employees of partner organizations.[1] A December 2024 update added more media partners and said participating publishers would also receive analytics while they remained in the program.[2]

Those are concrete features, but they are not enough to support a traffic or revenue forecast. Creators should read the program as a partnership offer whose practical value depends on details that the two public announcements do not fully explain. Before relying on AI answer traffic, verify how citations appear, what the reporting measures, which uses generate compensation, and what happens if the product changes.

Diagram mapping Perplexity publisher program evidence from citations to revenue sharing and analytics review

What Perplexity has publicly promised

The first announcement says Perplexity has included citations in its answers from the beginning. It connects those citations with publisher credit and user trust, then describes a program intended to support media organizations and online creators as the answer engine grows.[1] That wording matters. Citation is the baseline product behavior described in the post; formal program benefits are a separate layer available to partners.

Revenue sharing tied to referenced content

Perplexity said it planned to introduce advertising through related questions. Brands would be able to pay to place specific follow up questions in the answer interface and on Pages. When Perplexity earned revenue from an interaction in which a publisher’s content was referenced, the publisher would receive a share.[1] The later expansion post says participating publishers share revenue generated from advertising.[2]

This is more specific than a general promise to support journalism, but it still leaves important commercial questions open in the public material. Neither announcement gives a percentage, a sample calculation, a payment threshold, or a schedule for reporting and settlement. The posts also do not define every event that counts as an eligible interaction. A creator assessing a contract should therefore ask for the actual formula and definitions rather than model expected income from the announcement alone.

Tools publishers can use on their own sites

Program partners were offered free access to Perplexity’s Online LLM APIs and developer support. The launch post says a publisher could use those resources to build a custom answer engine that answers visitors’ questions while citing only that publisher’s content. It also says partners could integrate related questions into their stories.[1]

That benefit is different from referral traffic. It gives a publisher a possible on-site product, but the publisher would still need to decide what readers need, how answers should be presented, and how errors or weak citations will be handled. API access is an input, not a finished audience strategy. Ask who pays for implementation, what usage limits apply, how support works, and whether access continues if the partnership ends.

Research access and analytics

The original offer included one year of Enterprise Pro for all employees of a publisher partner. Perplexity described this version as having enhanced data privacy and security capabilities and positioned it as a research and fact checking tool for creators.[1] The expansion announcement repeated the one-year organization-wide benefit. It also said partners would receive analytics to track trends and content performance for as long as they stayed in the program.[2]

Analytics may be the most useful part of the offer for an editorial team trying to understand answer engines, but only if the measurements are clear. A dashboard can count citations, exposures, referrals, eligible interactions, or other events. Those numbers are not interchangeable. Publishers need a data dictionary and enough detail to reconcile platform reporting with their own analytics.

The distinction between citation, exposure, and a visit

A creator can be cited without receiving a visit. A source link may be visible, collapsed, attached to a sentence, or presented among several references. Even when a reader notices it, that reader may already have the information needed. This does not make citation meaningless. It does mean that citation volume should not be reported as website traffic.

Use separate terms in internal reports:

  • Citation: the publisher’s page or domain appears as a source in an answer.
  • Exposure: a user had a reasonable chance to see the citation, based on the platform’s stated measurement.
  • Referral: a user clicked through to the publisher’s site.
  • Engaged visit: the referred reader did something the publisher considers meaningful, such as reading further or joining a newsletter.
  • Compensated interaction: an event that meets the program’s contractual revenue-sharing rules.

Only the last three can be connected directly to a publisher’s site analytics or commercial records, and even then attribution settings matter. Perplexity’s announcements do not claim that every citation produces a referral or a payment. They describe citations as a standard part of answers and revenue sharing as a program benefit tied to advertising revenue and referenced content.[1] Keeping those ideas separate prevents an impressive citation count from becoming an unsupported business projection.

Questions to settle before joining or depending on the program

Who is eligible, and what content is covered?

The two official posts identify launch partners and later additions, including publishers in the United Kingdom, Japan, Spain, and Latin America. They cover large news organizations, specialist publications, local reporting groups, and publishing platforms.[2] That variety shows the program was not limited to one editorial category. It does not establish open eligibility for every independent creator.

Ask whether participation is by invitation or application, whether an individual site can qualify, and whether all pages on an accepted domain are covered. A network should confirm how its member sites are treated. A creator using a hosted platform should also establish whether the platform’s participation gives the creator any direct reporting or financial rights. WordPress.com’s presence among the launch partners should not be treated as proof that every WordPress site automatically receives every program benefit.[1]

How is compensation calculated?

Request the current agreement, not a summary of the 2024 announcement. It should explain what revenue enters the pool, how referenced content is matched to an interaction, whether several cited publishers divide a share, and which deductions apply. Confirm payment currency, thresholds, timing, dispute procedures, and tax documentation. None of these details appears in the two public posts.

There is also a timing issue. The launch announcement described related-question advertising as something Perplexity would introduce in the coming months.[1] The December update says partners would share advertising revenue, but it does not publish operating results or a standard payout example.[2] Creators should verify the present product and terms rather than assuming the launch description still maps exactly to current practice.

What does the analytics dashboard measure?

Ask for field definitions before evaluating a dashboard. Does a citation count each generated answer, each user session, or each distinct source URL? Can the publisher see the query, country, device, answer placement, and destination page? Are bots and repeated requests removed? How long is data retained, and can it be exported?

Then compare platform data with first-party records. Use tagged links where available, inspect referrer information, and monitor landing-page behavior. A mismatch is not automatically evidence that either side is wrong. The systems may count different stages of the journey. The goal is to know what each number represents well enough to make editorial decisions without pretending that unlike measures are the same.

How are attribution and corrections handled?

The launch post says Perplexity updated how its systems index and cite sources and was gathering publisher feedback for its product roadmap.[1] That indicates citation behavior can change. Publishers should ask how they can report a missing citation, an incorrect attribution, a stale excerpt, or an answer that misrepresents the cited page. The response process needs an owner, a channel, and a reasonable expected time frame.

Run periodic checks using questions for which your site has strong, original material. Record whether the page is cited, where the citation appears, and whether the answer accurately reflects the article. Do not optimize around one test. Answer generation can vary, and a small manual sample cannot stand in for program analytics. It can, however, reveal obvious attribution problems worth escalating.

Checklist for creators reviewing AI answer traffic, citations, referral quality, and publisher analytics

A practical measurement plan for creators

Start with a limited review period and a written baseline. Record existing referrals from Perplexity, the landing pages receiving them, engagement on those pages, and any measurable reader actions. Keep this baseline separate from referrals from conventional search or social platforms. If the site has no meaningful Perplexity traffic yet, that is still a useful starting point.

Next, build a small content sample. Include reporting or guides that are original, updated, and likely to answer a defined question. Avoid changing the entire editorial calendar in response to an untested distribution channel. For each page, note publication and update dates, referral sessions, engagement, citations reported by the partner tools, and any compensated interactions. Review the sample at a fixed interval.

Qualitative checks belong beside the numbers. Is the citation attached to the part of the answer your page supports? Does the answer preserve qualifications from the article? Is another site credited for your original work? Does the referral land on the correct canonical page? These checks help a publisher distinguish a traffic question from an attribution or content-quality problem.

For a broader look at answer engines and creator strategy, see what answer engines mean for creators. When testing generated answers, use a repeatable source-checking process rather than accepting fluent output at face value. This guide to research, deep research, and verification explains the habits that make those checks more reliable.

Build for direct readers as well as answer engines

A partnership can add distribution, tools, and data, but it should not become the only route between a creator and an audience. Keep investing in reasons to visit the original page: firsthand reporting, useful context, transparent sourcing, clear corrections, and material that cannot be reduced cleanly to a short answer. Once a referred reader arrives, the site should make the next useful action obvious without burying the article under prompts.

Maintain channels the publisher can reach directly, such as email subscriptions or member accounts, when those channels fit the publication. The point is not to reject AI discovery. It is to avoid confusing access to a third-party product with ownership of the reader relationship. Program terms, answer layouts, citation practices, and advertising products can change. A direct audience gives the publisher a steadier reference point when evaluating those changes.

Perplexity said in its first announcement that the program could adapt and mentioned bundled subscriptions as one possible future collaboration.[1] That language is a proposal, not a commitment that a specific bundle will be available to every partner. Treat future features the same way: evaluate them when terms, technical requirements, and reporting are concrete.

A decision standard that does not depend on hype

The Publishers Program has identifiable components. Perplexity publicly described advertising revenue sharing, API access with developer support, employee access to Enterprise Pro for one year, and partner analytics.[1][2] It also expanded the partner list after launch and reported interest from more than 100 publishers in the December 2024 post.[2] Those facts show activity around the program, but they do not establish a typical result for an individual creator.

A sensible decision rests on verifiable terms and observed outcomes. Join or test the program if the agreement is understandable, the reporting can be audited, the integration cost is proportionate, and the relationship improves something the publication already values. Reassess if citation grows without useful referrals, if compensation cannot be reconciled, or if technical work absorbs more resources than the benefits justify.

Most of all, avoid building a forecast from the word “citation.” Ask what was displayed, what was clicked, what was compensated, and what the publisher learned. That is a less exciting story than guaranteed AI traffic, but it is the one the available evidence supports.

FAQ

Does a Perplexity citation guarantee traffic to a publisher?

No. The official announcements say Perplexity includes citations in answers, but they do not promise that every citation will produce a click or a visit.[1] Publishers should measure referrals in their own analytics and keep citation counts separate.

Does every cited creator receive revenue sharing?

The public posts describe revenue sharing as a benefit for publishers in the program. They do not say that every site cited by Perplexity automatically receives payment.[1] A creator should confirm eligibility and obtain the current agreement before expecting compensation.

What benefits did Perplexity announce for program partners?

The launch post listed advertising revenue sharing, free access to Online LLM APIs with developer support, and one year of Enterprise Pro for partner employees. The later post also described analytics for partners while they remain in the program.[1][2]

What should a small publisher verify first?

Confirm whether the site is eligible and which content is covered. Then ask for the revenue formula, analytics definitions, payment rules, correction process, API limits, and exit terms. Compare reported citations and interactions with first-party referral and engagement data before changing the publication’s strategy.

Sources

  1. Perplexity, “Introducing the Perplexity Publishers’ Program,” July 30, 2024.
  2. Perplexity, “Perplexity expands publisher program with 15 new media partners,” December 5, 2024.

Related update: Perplexity AI Raises $1B for Answer Engine Expansion: What It Means for Global Content Creators.

Anthropic Life Sciences: What Is Actually Confirmed

0

Correction: the claim that Anthropic acquired Coefficient Bio for $400 million is not supported by an announcement in Anthropic’s official newsroom that we could locate during this review. Anthropic’s official material does document a substantial life sciences initiative, but that is not evidence that this reported transaction occurred or that the stated price is accurate. This article therefore does not present the acquisition claim as fact. The historical URL is retained so existing links continue to work, while the page now explains what can be verified and how to assess similar claims.

The distinction matters. A partnership, customer relationship, product integration, hiring move, investment, and completed acquisition are different events. Even when several secondary reports repeat the same number, repetition does not replace confirmation from a named party or a reliable transaction record. Readers need a method that separates verified facts from plausible interpretation, especially when a dramatic business headline is tied to health, biology, or drug research.

What Anthropic officially says about life sciences

Anthropic announced Claude for Life Sciences in its official newsroom. That announcement describes an effort to support work across research, early discovery, translation, and commercialization. It names examples such as literature review, hypothesis development, protocol drafting, bioinformatics, data analysis, and assistance with clinical or regulatory documents. These are Anthropic’s descriptions of intended uses and product direction, not independent proof that a model can produce a valid scientific result without expert review.

The same announcement describes connectors to scientific platforms and access to research sources, along with Agent Skills and a life sciences prompt library. A connector can make records or tools available to a model, but it does not automatically make the model’s interpretation correct. The quality of an answer still depends on the source record, permissions, configuration, task definition, and review process. A draft protocol remains a draft. A proposed hypothesis remains a hypothesis. An analysis output remains subject to methodological and scientific validation.

Anthropic also names customers, partners, and scientific organizations in the announcement. Those relationships show that Claude is being explored or used in the sector. They do not support a separate claim about Coefficient Bio or a transaction price. This is a useful reading habit: evidence for a broad strategy should not be stretched into evidence for a specific deal.

Five-step evidence ladder for verifying an AI company acquisition claim
Define the claim, check the parties, trace the original report, test every detail, and label uncertainty.

How to verify an acquisition headline

Start with the exact claim. Write down the buyer, target, transaction type, completion status, announced value, announcement date, and source. Words such as acquired, agreed to acquire, invested in, partnered with, and hired the team are not interchangeable. A headline can become misleading when it removes a qualifier or turns an unsigned report into a completed event.

Next, search the official newsroom and company pages of both named parties. An official announcement should clearly identify the parties and describe the event. If the value is material to your article, the primary source should support that value. Do not derive a price from an estimate, employee count, funding rumor, or unnamed source and then write it as a settled figure. If neither party confirms the event, say that official confirmation was not located. Absence from a newsroom is not absolute proof that an event never happened, but it is a strong reason not to state the headline as confirmed.

Then check whether the source is independent or circular. Several pages may trace back to one paywalled report, one social post, or one unattributed paragraph. Count the underlying sources, not the number of search results. Open each page and look for a direct company statement, named spokesperson, filed document, or clearly attributed interview. If every article points to another article, the evidence has not become stronger.

Finally, preserve the uncertainty in your wording. Suitable language includes “reported by” or “not confirmed in the company’s official newsroom,” provided that the attribution is accurate. Avoid adding details that the source did not establish, such as the payment structure, employee destination, product roadmap, closing date, or strategic motive. A careful correction should remove unsupported specifics rather than replace them with a new story that merely sounds reasonable.

A practical evidence ladder

For a completed acquisition, the strongest public evidence usually comes from the parties themselves or a formal record that clearly identifies the event. A named executive statement or official newsroom post can establish what a company chose to announce. Regulatory or corporate filings may provide additional detail when they exist. A reputable news organization with named sourcing can be useful, but readers should still distinguish its reporting from company confirmation.

Lower on the ladder are anonymous social posts, copied summaries, search snippets, generated answers, and articles that do not link to their basis. They can help locate a lead, but they should not carry the final claim. Search snippets are especially weak because they may be stale, truncated, or generated from text that has since changed. An AI answer can also combine separate events into a confident but unsupported narrative.

A simple claim ledger prevents that drift. Create one row for each material statement. Record the exact wording, primary source URL, source date, what the source actually establishes, and any limitation. Label the row confirmed, reported, interpretation, or unsupported. Remove unsupported rows before publication. The PChatGPT guide to web search and source verification explains why linked answers still need this manual review.

What Claude can help with in life sciences

Within an authorized workflow, a language model can organize a literature set, extract candidate facts for review, compare document versions, explain code, draft analysis scripts, outline a protocol, or turn notes into a structured report. These tasks can reduce clerical effort and make a large body of material easier to inspect. They are most useful when the model is asked to show its sources, mark uncertainty, preserve identifiers, and produce output that a qualified reviewer can audit.

The model should not be treated as the source of record. It can misread a paper, invent a citation, omit a contradictory result, confuse an assay with a clinical outcome, or produce code that runs but answers the wrong question. Scientific language can make an answer sound more established than it is. Require the output to distinguish quotation, extraction, calculation, and interpretation. Then compare every consequential statement with the underlying record.

For literature work, define the search boundary and record the query, databases, dates, filters, and inclusion rules. For data analysis, preserve the dataset version, preprocessing decisions, environment, code, random seeds where relevant, and review notes. For protocol drafting, identify which sections came from approved templates and which were newly generated. This creates a trail that another person can inspect instead of relying on a polished chat transcript.

Where AI assistance must stop

A model output is not laboratory validation, clinical evidence, regulatory approval, or medical advice. It should not independently decide patient care, declare a target safe, interpret an ambiguous result as a diagnosis, or approve a submission. Anthropic’s current Usage Policy places additional requirements on high risk healthcare uses, including qualified human review for advice or decisions that directly affect individuals and disclosure when AI contributes to outputs presented to them.

Even low risk drafting can become high consequence when the output enters a clinical, quality, or regulatory workflow. Define who owns the decision, what evidence is required, who can approve the result, and how an error is corrected. A reviewer needs the source material and reasoning trail, not just the final prose. If the team cannot reproduce how an answer was produced, it should not use that answer as a critical record.

Five-stage reviewable life sciences AI workflow from approved sources to independent validation
A responsible workflow keeps approved sources, data minimization, AI assistance, expert review, and validation visible.

Protect sensitive scientific and health data

Before uploading data, classify it. Separate public papers from confidential research, personal data, health information, credentials, unpublished intellectual property, and regulated records. Use only an approved product and account configuration for the classification involved. Do not assume that a consumer chat and a managed commercial workspace have identical data handling. Anthropic’s commercial product training explanation says inputs and outputs from commercial products are not used for model training by default, while also describing exceptions such as feedback or an explicit choice to allow use.

Training use is only one privacy question. Teams should also assess retention, access, geographic requirements, contracts, connector permissions, incident response, audit logs, and deletion processes. Minimize data before submission. Replace direct identifiers where the task allows it, restrict access to the smallest appropriate group, and avoid placing secrets in prompts. The site’s broader AI data governance guide provides a practical framework for owners, permissions, approval rules, and review cycles.

Connectors deserve their own review because they can broaden what the model can retrieve. List each source, the account used, scopes granted, records reachable, actions allowed, and person responsible. Prefer read only access when the task is analysis. A model that can draft a document usually does not need permission to publish it, alter a laboratory record, or message an external party. Keep those actions behind a clear human checkpoint.

A controlled evaluation workflow

  • Define the task: choose one narrow workflow and state what a useful output must contain.
  • Choose approved data: document the classification, source, permission, and any required minimization.
  • Create a reference set: use reviewed examples that represent ordinary cases and important failure modes.
  • Set review criteria: check source fidelity, completeness, methodological fit, privacy, and unsupported claims.
  • Limit tools: grant only the connectors, files, and actions needed for the evaluation.
  • Record the run: preserve prompts, model information, source versions, outputs, corrections, and reviewer decisions.
  • Escalate exceptions: route ambiguous, sensitive, or consequential results to the appropriate qualified expert.
  • Decide from evidence: expand only if the workflow performs acceptably under the team’s predefined criteria.

Do not invent a success rate from a small pilot or report only the best examples. Track the full set, including abstentions, unsupported citations, missed facts, and corrections. The purpose of a pilot is to discover where the workflow fails and whether review can reliably catch those failures. If a metric is used, define its numerator, denominator, scoring method, and reviewer process before drawing a conclusion.

Questions to ask a vendor or project owner

  • Which exact product, model, account type, and connectors are in scope?
  • What data can the system read, retain, transform, and send?
  • Which claims come from official documentation, and which are internal observations?
  • How are citations opened and checked against the original text?
  • Who reviews scientific, clinical, quality, and regulatory outputs?
  • Which actions require approval, and can permissions be revoked quickly?
  • How are model changes, source updates, errors, and corrections recorded?
  • What happens when the model lacks evidence or sources conflict?

Official sources used for this correction

This correction relies on Anthropic’s official Claude for Life Sciences announcement for the documented life sciences direction and examples, the official Privacy Center article for commercial product training use, and Anthropic’s official Usage Policy for current use boundaries and high risk requirements. None of those official pages supports the original acquisition headline or the stated $400 million value. Product terms, policies, and capabilities can change, so open the current pages before making a procurement, compliance, research, or publication decision.

FAQ

Did Anthropic acquire Coefficient Bio for $400 million?

We could not locate an official Anthropic newsroom announcement supporting that acquisition and price during this review, so this page does not treat the claim as confirmed. That finding is not proof that no private event occurred. It means the headline lacks the primary official support needed to present it as fact.

What has Anthropic officially announced for life sciences?

Anthropic officially announced Claude for Life Sciences and described research, literature, protocol, bioinformatics, data analysis, and clinical or regulatory document workflows, plus connectors and skills. These are documented product directions and use cases, not proof of a specific acquisition or proof that model output replaces scientific validation.

Can Claude safely analyze confidential biomedical data?

Only an organization can decide that after reviewing the exact product, contract, configuration, data classification, permissions, retention, security controls, and legal duties. Use an approved environment, minimize data, limit access, review connectors, keep audit records, and involve privacy, security, scientific, and compliance owners as appropriate.

How should I verify a similar AI acquisition claim?

Write down the exact parties, event, status, value, and date. Look for an official announcement from the named companies and any relevant formal record. Trace secondary reports to their original source, check whether the value is actually supported, and label uncertainty clearly. Remove details that cannot be tied to reliable evidence.

How to Build AI Agents That Actually Work in Production

0

An agent demo does not show how the system will behave under production conditions. It must interpret imperfect requests, choose among tools, handle stale or hostile data, survive network failures, respect permissions, and leave an understandable record of what happened. The hard part is not making a model call a function. It is making every possible action safe enough, observable enough, and recoverable enough for real users.

This guide presents an engineering workflow for production AI agents. It focuses on the design choices that remain important even as models and product interfaces change: narrow outcomes, explicit tool contracts, approval at the point of consequence, repeatable evaluation, operational visibility, and controlled rollout. It draws on OpenAI’s current agents overview, function calling guide, guardrails and human review guidance, agent evaluation guidance, safety best practices, and production best practices. Treat those official pages as the source for current API details.

Begin with a job that deserves an agent

An agent is useful when a language model must manage a multistep workflow, decide which tools to use, and adapt to context. Not every AI feature needs that freedom. Classification, field extraction, a fixed transformation, or a known sequence of API calls may be simpler and safer as ordinary software. OpenAI’s practical guide to building agents recommends agents for work with nuanced decisions, difficult rules, or substantial unstructured data. That is a better starting test than asking where an agent might look impressive.

Write the job as an outcome a user can recognize. “Help with support” is too broad. “Answer questions from approved support articles, collect missing account details, and prepare a refund request for human approval” is testable. Name what the agent may read, what it may change, and what it must never do. Define success, abstention, escalation, timeout, and cancellation before selecting a model.

A useful scope document fits on one page. It lists the user, trigger, allowed data, permitted tools, completion condition, approval points, and owner. It also names foreseeable harm. Could the agent disclose another customer’s data, send an incorrect message, duplicate a payment, overwrite a record, or follow an instruction hidden in a web page? These questions turn vague safety concerns into requirements engineers can implement.

If you are still choosing between chat, agents, scheduled tasks, and conventional automation, the PChatGPT comparison of AI productivity tools and workflow automation offers a user facing view of those categories. The important decision is how much initiative the system needs, not how many features it can advertise.

Design the workflow before writing the prompt

Draw the happy path and the failure paths. A support agent might identify intent, retrieve policy, check account state, propose an action, request approval, execute once, verify the result, and summarize. Beside each step, record the input, output, authority, timeout, retry rule, and evidence to retain. This map becomes the basis for tools, logs, tests, and the user interface.

Keep deterministic work deterministic. Authentication, authorization, money calculations, date validation, policy thresholds, schema validation, and idempotency belong in code. Let the model handle tasks that benefit from language understanding or flexible reasoning, such as identifying a request, choosing relevant evidence, or explaining an outcome. The model can recommend an action, but the service should enforce whether that action is allowed.

Start with one agent when possible. A single bounded loop is easier to inspect than a network of specialists. Split the system only when separate instructions, permissions, or context clearly improve reliability. Multiple agents add handoffs, more state, more opportunities for inconsistent decisions, and a harder debugging story. Architecture should follow measured need rather than fashion.

Five stage production AI agent control path from authenticated request through model decision, policy enforcement, approval, execution, and verification

Make every tool a narrow contract

Tool access is where an agent becomes consequential. OpenAI’s function calling guide describes a loop in which the application provides tool definitions, receives a tool call, executes it, returns the result, and lets the model continue. Your application remains responsible for the execution. A tool call is a proposed structured action, not proof that the action is correct or authorized.

Give each tool one clear purpose. Prefer get_order_status and request_refund over a broad manage_order tool. Use typed parameters, required fields, enumerated values where appropriate, and strict schemas. Validate arguments again on the server. Never build database statements, shell commands, file paths, or destination addresses by blindly concatenating model output.

Separate read tools from write tools. Reading a product catalog does not carry the same risk as changing a price. Use least privilege credentials for each tool and derive user authorization from trusted application state, not from a claim inside the conversation. A model should not be able to increase its own permissions by asking for a different role.

Return structured results that distinguish success, rejection, retryable failure, permanent failure, and unknown outcome. Include stable record identifiers rather than relying on prose. When a timeout happens after a request was sent, the agent may not know whether the side effect occurred. The recovery path should query the system of record before trying again.

For side effects, use idempotency keys or an equivalent deduplication design. A retry should not create a second refund, ticket, email, or reservation. Record the proposed arguments, policy decision, approval identity when applicable, execution response, and verification result. Redact secrets and unnecessary personal data from that record.

Put approvals beside consequences

Guardrails and approvals solve different problems. OpenAI’s current Agents SDK guidance describes input guardrails for requests, output guardrails for final responses, tool guardrails around function calls, and human approval for side effects. A general instruction such as “be careful” is not a substitute for a control at the action boundary.

Require approval when an action is costly, difficult to reverse, external, privileged, or sensitive. Examples include sending a message, changing an account, deleting a file, publishing content, purchasing an item, cancelling an order, and running a command. Show the reviewer the exact action, target, important arguments, supporting evidence, and expected consequence. “Approve agent plan” is too vague.

Approval should pause the run before execution. After a reviewer approves, recheck authorization and any time sensitive preconditions. An old approval should not permit an action after the account, price, policy, or destination has changed. Record who approved what, and give the reviewer a clear way to reject or edit the proposal.

Prompt injection needs architectural defenses. Treat text from web pages, documents, email, and tool results as untrusted data. Do not let retrieved text redefine the system’s permissions. Limit the tools available for the current step, keep sensitive values outside model context when possible, validate tool arguments, and require approval for meaningful side effects. Readers evaluating agents that operate in websites can also use PChatGPT’s AI browser agent safety guide to think through the added risk of acting through interfaces.

Build a failure model, not just a happy path

List failures by layer. The model can misunderstand intent, select the wrong tool, omit a required step, or produce unsupported text. A tool can time out, reject arguments, return stale data, or report a partial result. The surrounding service can lose state, exceed a limit, or receive two copies of the same event. A person can approve the wrong target. Your design needs a response for each class.

Set bounded retries with backoff for failures that are genuinely temporary. Do not retry validation errors or denied actions. Cap model turns and tool calls so a confused loop cannot run forever. Give the system a terminal state such as needs human help rather than forcing every request to complete autonomously.

Make cancellation real. The interface can stop future steps, but it cannot pretend an action already completed never happened. Track committed side effects and define compensating actions where practical. For example, a created draft might be deleted, but a sent email can only be followed by a correction. The final response should state what completed, what failed, and what remains uncertain.

Persist state at meaningful checkpoints. A long workflow should resume from verified state instead of replaying every action. Store the minimum context needed to continue safely, with retention and access controls appropriate to the data. Version instructions, tool schemas, policies, and model configuration so an incident can be reconstructed.

Evaluate the whole trajectory

Final answer quality is not enough. An agent can produce a plausible response after using an unauthorized source, calling an unnecessary tool, leaking sensitive data into a log, or attempting the same action twice. Evaluate the path: tool choice, argument quality, evidence use, policy compliance, approval behavior, stopping behavior, and final communication.

OpenAI’s agent evaluation guide recommends starting with traces while debugging, then moving to datasets and repeatable eval runs. A trace provides the sequence of model calls, tools, guardrails, and handoffs. Turn observed failures into durable test cases. Your dataset should include normal requests, ambiguous requests, missing data, malformed tool output, prompt injection, permission failures, outages, duplicate events, and requests the agent must refuse or escalate.

Use deterministic checks whenever possible. Did the agent call only allowed tools? Did every write have approval? Were required fields present? Was the final status verified? Was private data absent from the response? Human review or model based graders can assess softer qualities such as relevance and clarity, but calibrate them against examples and inspect disagreements.

Choose metrics tied to the job. Useful measures include successful task completion, correct abstention, unsafe action attempts, duplicate side effects, escalation quality, tool error recovery, latency, and resource use. A single average can conceal a severe failure class. Break results down by intent, risk tier, language, customer segment, tool, and workflow version where those dimensions matter.

Four layer AI agent evaluation stack covering deterministic checks, scenario datasets, trajectory review, and production monitoring

Observe production without collecting everything

Operators need to answer four questions quickly: what did the user ask, what path did the agent take, what changed in an external system, and why did the run stop? Use a correlation identifier across model calls, tools, approval events, and application logs. Record timing, status, schema version, and error category. Keep an audit trail for consequential actions.

Observability should respect privacy. Do not log API keys, authentication tokens, raw secrets, or full sensitive documents by default. Classify data before launch, redact fields at ingestion, restrict access, and define retention periods. Separate diagnostic detail from analytics. More logging is not automatically better if nobody can safely search or interpret it.

Alert on symptoms users feel and controls you cannot afford to lose: elevated task failures, rising tool timeouts, approval bypass attempts, repeated actions, unusual permission denials, and sudden changes in escalation. Dashboards are useful, but sampled trace review often reveals behavior that a count cannot explain.

Treat security and operations as product features

OpenAI’s safety guidance recommends adversarial testing, human review where possible, constrained inputs and outputs, clear limitation communication, and issue reporting. Apply those ideas to the complete service. Authenticate users, authorize every resource access, rate limit expensive or risky operations, scan uploaded content where appropriate, and offer a visible route for reporting bad behavior.

Keep credentials in a secret manager or protected environment, never in prompts or source code. Use separate development, staging, and production projects. OpenAI’s production guidance recommends protecting API keys and separating environments as systems scale. Give production access only to people and services that need it. Rotate compromised credentials and test the rotation process before an incident.

Plan capacity and degraded behavior. Rate limits, provider incidents, and downstream outages are normal operating conditions. Decide whether the agent should queue, retry, provide a read only response, or hand the work to a person. Communicate status instead of leaving the user watching an endless spinner. Cost controls should cap runaway loops while preserving enough diagnostic evidence to understand them.

Roll out in stages and earn autonomy

Begin in shadow mode if the workflow allows it. Let the agent propose decisions while the existing process remains authoritative. Compare proposals with real outcomes and capture disagreements. Next, allow it to prepare drafts for review. Grant limited execution only after the relevant failure rates and approval behavior meet your acceptance criteria.

Use a small audience, narrow tool set, and reversible actions first. Establish a kill switch that operators can use without deploying code. Keep a deterministic fallback or human queue. Increase autonomy by action class, not with one global switch. An agent might safely look up an order while still requiring approval to refund it.

Every release should identify what changed: model, prompt, tool schema, retrieval source, policy, or orchestration code. Run regression evals before deployment and monitor the same risk slices afterward. Roll back when a change degrades important behavior. Production quality is a continuing practice, not a launch milestone.

A practical production readiness checklist

  • Task: The outcome, non-goals, completion state, and escalation path are explicit.
  • Authority: Every tool uses least privilege and server-side authorization.
  • Contracts: Arguments and results use validated schemas with clear error states.
  • Side effects: Writes are idempotent, recorded, verified, and approved when consequential.
  • Untrusted data: Retrieved content cannot silently change permissions or policy.
  • Failure: Retries are bounded, uncertain outcomes are reconciled, and cancellation is defined.
  • Evaluation: Tests cover trajectories, edge cases, attacks, abstention, and regression.
  • Operations: Traces, alerts, ownership, rollback, privacy controls, and incident response exist.
  • User experience: The product communicates progress, limitations, approvals, and final state clearly.

If any answer is vague, keep the system in a lower autonomy mode. Human review is not a sign that the agent failed. It is a deliberate part of the product when consequences require judgment.

FAQ about production AI agents

What makes an AI agent different from a chatbot?

A chatbot may simply generate a response. An agent manages steps toward an outcome and can select tools that read data or take actions. That extra authority creates a need for explicit permissions, tool validation, traceable state, failure recovery, and approval before consequential side effects.

Should a production agent use multiple specialist agents?

Not by default. Start with one bounded agent because it is easier to evaluate and operate. Add specialists when separate context, instructions, ownership, or permissions produce a measured improvement. Each handoff adds state and another place where errors can occur.

Where should human approval be required?

Place approval immediately before actions that are external, costly, privileged, sensitive, or hard to reverse. The reviewer should see the exact target, arguments, evidence, and consequence. Recheck authorization and changing preconditions after approval and before execution.

How do you know an agent is ready for production?

Readiness is evidence, not a successful demo. The system should pass representative and adversarial evals, preserve permissions, handle tool failures, prevent duplicate side effects, pause correctly for approvals, produce useful traces, protect sensitive data, and support rollback. Launch narrowly and confirm that production behavior matches the tested behavior.

Decide what can ship

Before release, ask an operator to trace a failed run, reject a proposed action, and stop the workflow. If the product cannot support those tasks, keep it in draft-only mode until it can. Use evaluation and operating evidence to decide which actions can run without review.