Home Blog Page 5

11 Underrated ChatGPT Features That Save Serious Time

0

Most people meet ChatGPT through a blank message box. That makes the product look like a writing assistant, even though some of its best time savers live around the conversation itself. The useful gains come from keeping context organized, editing only the passage that needs work, checking a spreadsheet with executable analysis, or asking for a reminder that returns when it matters.

This guide covers 11 underrated ChatGPT features for practical work. Each one solves a different kind of friction. You do not need to adopt all of them. Pick the feature that removes a repeated step from a task you already do, test the result on low risk work, and keep human review at the point where an error would matter.

Quick answer: Start with Projects for recurring work, Custom Instructions for stable preferences, and Search for current facts. Use Canvas when a draft needs several revisions, Data Analysis when numbers need calculation, Deep Research when a question needs many sources, and Scheduled Tasks when the value depends on timing. Memory can reduce repetition, while Temporary Chat gives you a cleaner context when personalization is not wanted.

1. Projects keep recurring work from starting at zero

A long running job rarely fits neatly in one chat. A client launch might involve a brief, audience notes, research, drafts, and weekly decisions. Copying that context into every new conversation wastes time and increases the chance that an old instruction gets missed.

OpenAI describes Projects as workspaces that group chats, reference files, and project instructions. Create one for a real stream of work rather than a vague topic. A project called “May customer newsletter” is more useful than one called “Writing.” Add the approved style guide, current product notes, and a short instruction that defines the audience and output format.

The underrated move is saving a strong ChatGPT response as a project source. A confirmed decision, final outline, or approved terminology list can then become context for later conversations. Review the sources occasionally, remove stale files, and remember that project instructions can override your global custom instructions inside that project.

2. Project instructions create a local working style

Global preferences are convenient, but every job does not need the same voice. A legal document review, a lesson plan, and a friendly newsletter should not inherit identical rules. Project instructions let you define behavior for one body of work without repeatedly pasting a large prompt.

Write instructions like a compact editorial card: state the reader, goal, constraints, preferred structure, and what the assistant must flag rather than invent. For example: “Write for first time managers. Use plain English. Put risks before recommendations. If a figure is absent from the source files, label it unknown.” That is specific enough to guide responses without burying the task in ceremony.

Keep these instructions short and test them with two different requests. If both outputs make the same mistake, repair the instruction once. This turns prompt correction into maintenance of a reusable setting instead of a repeated conversation.

3. Custom Instructions remove everyday repetition

Some preferences really do apply almost everywhere. Perhaps you want concise answers, measurements in metric units, accessible explanations, or a clear distinction between facts and assumptions. Custom Instructions let you store guidance that ChatGPT considers across chats.

The best entries are durable. Include your role only if it changes the answer, name the formats you routinely use, and specify a behavior you can observe. “Ask before assuming a budget” is testable. “Always be brilliant” is not. Avoid loading this field with confidential client details or temporary campaign facts. Those belong in an appropriate controlled workspace or the individual prompt.

Revisit the setting after a few weeks. Preferences that sounded useful can create awkward answers in unrelated chats. A small, current set of instructions saves more time than a long personal manifesto.

4. Memory can carry useful context between conversations

Memory addresses the small facts you otherwise repeat: your dietary preference, the level of technical detail you understand, or a continuing goal. According to OpenAI’s current Memory FAQ, memory can use context from chats, files, and connected apps when enabled, and its controls live under Personalization.

Use memory deliberately. Ask ChatGPT what it remembers, correct information that has changed, and remove details that should not influence future answers. A remembered preference is helpful only while it is accurate. Do not treat memory as an authoritative database or a substitute for giving the current requirements of an important task.

A good rule is to let memory hold stable preferences, while the prompt holds today’s objective and constraints. That division reduces setup time without allowing old context to quietly steer a high stakes answer.
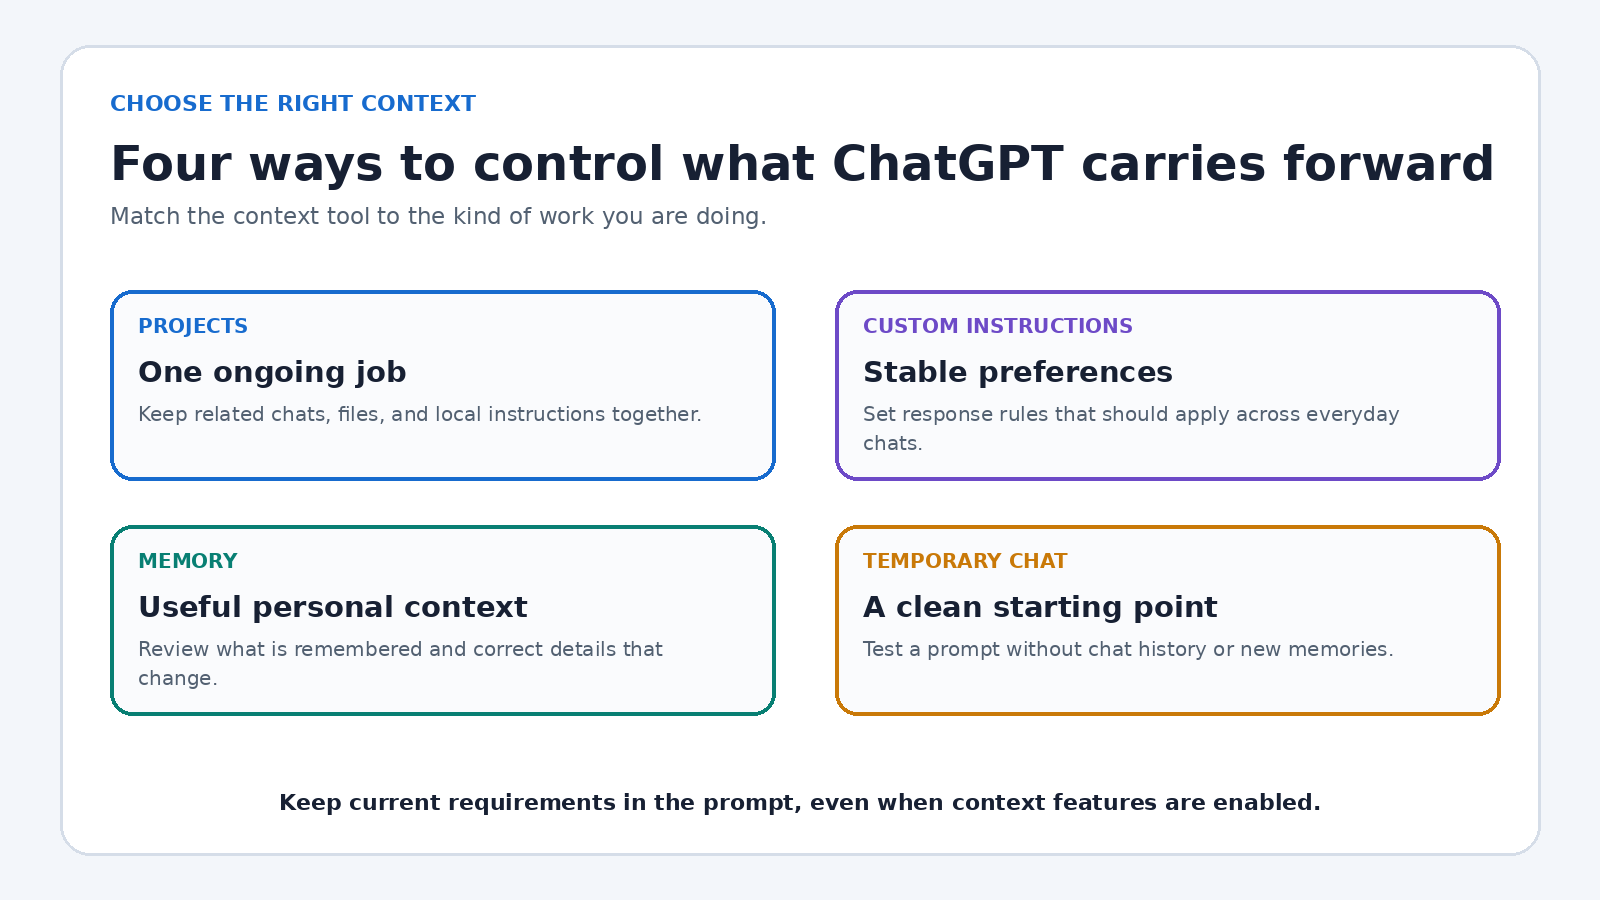
Decision guide comparing Projects, Custom Instructions, Memory, and Temporary Chat for controlling ChatGPT context
Choose a context feature based on whether the information belongs to one project, most chats, future personalization, or no memory at all.

5. Temporary Chat gives you a clean room

Personalization is not always useful. You may want to test whether a prompt stands on its own, explore an unrelated topic, or avoid adding a conversation to history and memory. OpenAI’s Temporary Chat documentation says these conversations begin with a blank slate, do not appear in history, and do not create memories. Custom instructions may still apply, so a temporary chat is not necessarily free of every account level preference.

This feature saves time during quality control. Open the same prompt in a temporary chat and compare the answer with your regular conversation. If the clean version is confusing, your original result may depend on context that a colleague or customer will not have. That quick test is useful before publishing a reusable prompt or documenting a process.

Temporary Chat is a context control, not a blanket promise that any sensitive material is safe to paste. Follow your organization’s policies and review OpenAI’s current data controls before handling confidential information.

6. File uploads replace long copy and paste sessions

If the source already exists as a document, upload it rather than feeding fragments through dozens of messages. Projects can hold PDFs, spreadsheets, documents, images, and pasted text, subject to current plan and workspace limits. A file gives the model more coherent context and leaves you with a clearer record of what was consulted.

Ask for a bounded result. Useful examples include extracting action items with page references, listing contradictions between two policies, converting headings into a study plan, or identifying missing fields in a brief. Tell ChatGPT to distinguish direct evidence from inference and to quote the relevant passage when precision matters.

File quality still sets the ceiling. Scanned pages, complicated layouts, hidden spreadsheet logic, and obsolete versions can produce incomplete answers. Confirm names, figures, dates, and citations against the original. For a broader workflow on files and research, see our practical ChatGPT how to guide.

7. Data Analysis turns questions into inspectable calculations

A spreadsheet does not need to become a manual sequence of filters and formulas. OpenAI’s guide to Data Analysis with ChatGPT says the tool can inspect supported files, summarize trends and outliers, create tables and charts, and run Python based calculations for some tasks.

Prepare the sheet before uploading it. Put descriptive headers in the first row, keep one record per row, and separate unrelated tables. Then ask a precise question: “Group net revenue by month, show the formula, list excluded rows, and chart the result.” A request like “find insights” leaves too many choices hidden.

The real time saver is the review trail. When code is available, inspect it. Check which columns were used, how missing values were handled, and whether a median would be more meaningful than a mean. Download or recreate the result only after the calculation matches a small sample you can verify manually.

8. Canvas makes revision surgical

Chat is excellent for generating options, but a long conversation becomes clumsy when you need to fix paragraph seven without changing everything else. OpenAI’s Canvas introduction explains that Canvas provides a separate workspace where you can edit directly, highlight a section, request focused feedback, and restore previous versions.

Use Canvas after the outline is stable. Select the weak passage and give a local instruction such as “shorten this to 90 words and preserve all three numbers.” Then compare the revision with the source. Local edits reduce accidental drift in sections you already approved.

Canvas also helps with code because changes and comments remain connected to the larger artifact. It is not a replacement for version control, tests, or editorial review, but it is far easier to inspect than a chain of complete rewrites. If tone is the main problem, our guide to getting ChatGPT to write in your preferred style provides a useful companion process.

9. Search is the right tool for a current fact

Ordinary model knowledge and live web evidence are not the same thing. When a question depends on current documentation, a recent announcement, availability, opening hours, or a changing price, use Search. OpenAI says ChatGPT Search can return timely answers with links, inline citations, and a Sources panel.

Ask for sources you would trust even without AI. For product behavior, request the vendor’s documentation. For a public rule, prioritize the responsible agency. Open the links and make sure each citation supports the sentence attached to it. A citation can be real yet irrelevant, outdated, or too weak for the claim.

Search is usually faster than deep research when the answer is narrow. A request for today’s exchange rate needs a quick lookup. A comparison of five regulatory approaches needs a plan, many documents, and a more substantial review.
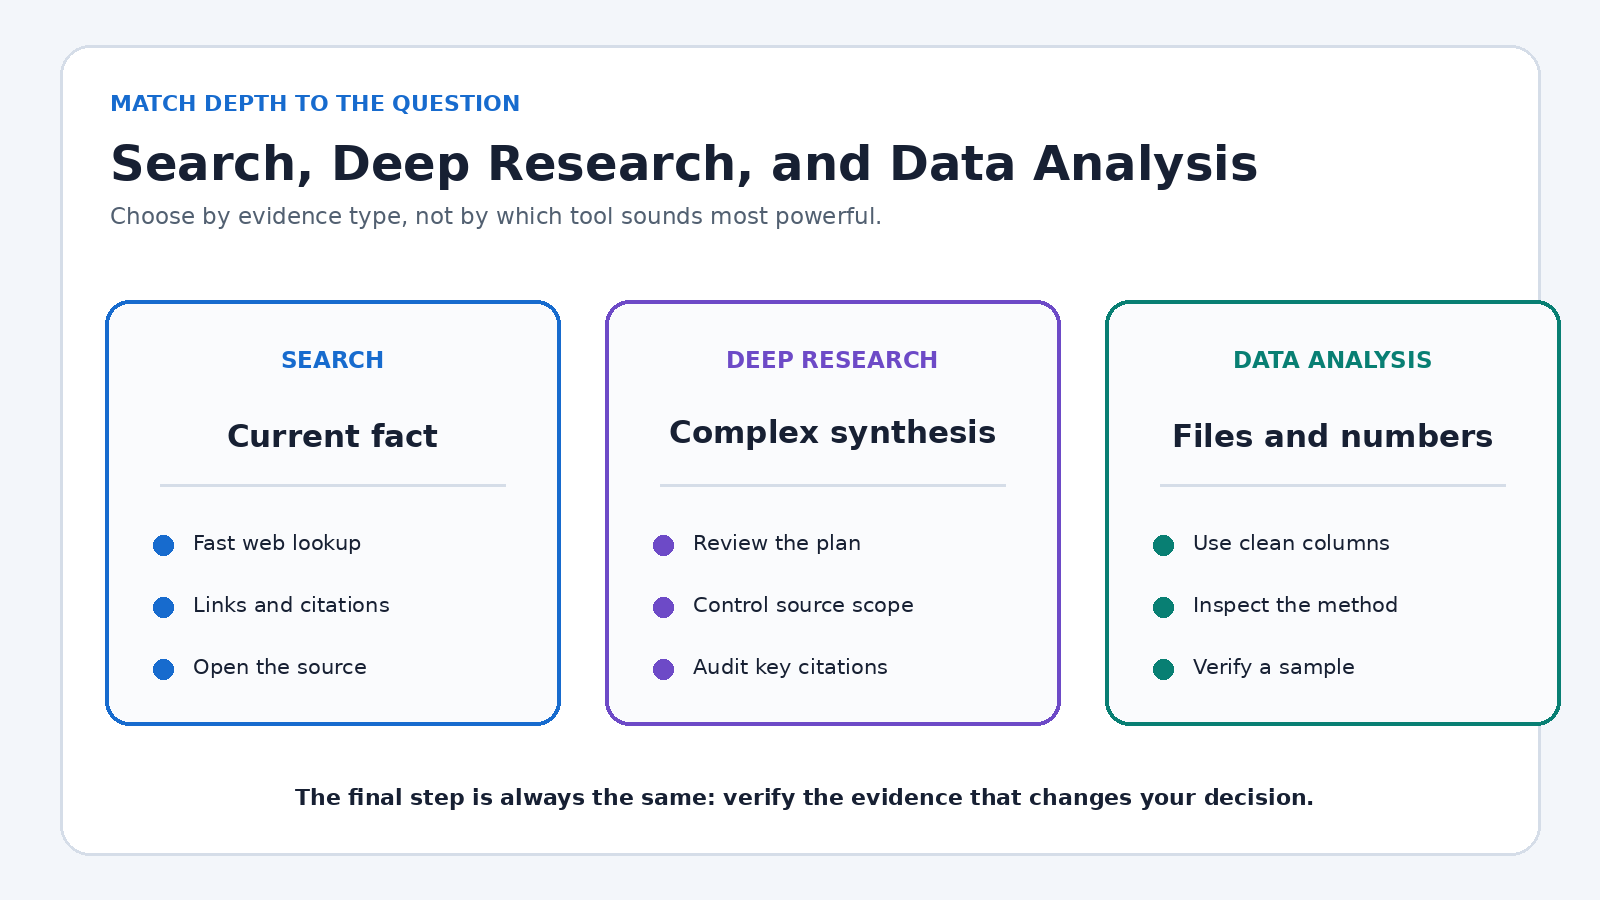
Decision chart for choosing ChatGPT Search, Deep Research, or Data Analysis based on the evidence needed
Use Search for a current fact, Deep Research for broad synthesis, and Data Analysis for files and calculations.

10. Deep Research handles questions with many moving parts

Some questions cannot be answered responsibly from three search results. OpenAI’s Deep Research guide says the feature can work across the public web, specified sites, uploaded files, and enabled apps, then produce a structured report with citations or source links. You can review its proposed research plan and adjust the source scope.

Give it a decision, not just a topic. “Compare these three payroll platforms for a 40 person UK company, using official pricing and security documents, and identify missing evidence” is stronger than “research payroll.” Define the date cutoff, geography, required sources, evaluation criteria, and output table before the run begins.

Then audit the report. Open the decisive citations, check dates, separate vendor claims from independent facts, and look for evidence the tool could not access. Deep Research can compress collection and synthesis, but the decision and accountability remain yours.

11. Scheduled Tasks move work to the right moment

A good answer delivered too late has little value. Scheduled Tasks can support one time reminders, recurring work, and monitoring that notifies you when a meaningful change appears. Current availability, limits, and supported tools vary by plan, so check the product interface and official page for your account.

Schedule outcomes with clear stop conditions. “Every Friday afternoon, remind me to review unresolved support tickets” is better than “help with support.” For monitoring, define what counts as meaningful, where to look, and when the task should stop. Review the Scheduled page periodically so obsolete tasks do not become background noise.

Do not assume a scheduled task can access every project file or tool. The official documentation notes feature limitations. Test the first run while the task is low risk, verify notifications, and keep critical deadlines in your established calendar or operations system.

A simple way to choose the feature

  • You repeat context: use a Project, project instructions, Custom Instructions, or Memory.
  • You need isolation: use Temporary Chat and still check which account preferences apply.
  • You have source material: upload the file, then request evidence tied to the original.
  • You have numbers: use Data Analysis and inspect the method.
  • You are revising an artifact: use Canvas for targeted changes.
  • You need a recent fact: use Search and open the cited source.
  • You need broad synthesis: use Deep Research and audit decisive citations.
  • You need action later: use Scheduled Tasks, then confirm the schedule and notification path.

The pattern is simple: match the feature to the friction. More tools do not automatically create a better workflow. A small setup that removes one repeated action, while preserving a clear review step, is usually the better investment.

A five minute setup that pays off

  1. Choose one recurring task that took at least 20 minutes last week.
  2. Name the bottleneck: missing context, manual calculation, revision, research, or timing.
  3. Select one feature from the list above and define a test output.
  4. Run it on a low risk example, then check every important fact or calculation.
  5. Save only the parts that worked, such as a project instruction, chart prompt, or scheduled reminder.

After three uses, compare the setup and review time with your old process. Keep the workflow if it saves effort without lowering quality. If review takes longer than the original task, narrow the request or return to the simpler method.

Frequently asked questions

Which underrated ChatGPT feature should I try first?

Try Projects if your work spans several conversations or files. It solves a common problem without requiring an elaborate system. Add only current reference material and a short project instruction, then use separate chats for distinct tasks.

Is ChatGPT Search the same as Deep Research?

No. Search is suited to quick, current answers and provides links to sources. Deep Research is intended for complex questions that require a plan, broader source collection, and a documented synthesis. Use the lightest tool that fits the decision.

Can I trust charts and calculations from Data Analysis?

Treat them as work to verify, not automatic truth. Inspect the selected columns, code, assumptions, treatment of missing data, and a small manual sample. Errors in the source file or an ambiguous prompt can still produce a polished but incorrect result.

Do these features work on every ChatGPT plan?

Not always. Availability, limits, models, labels, devices, countries, and workspace permissions can differ. Check the current OpenAI documentation linked above and the tools visible in your own account before building a critical process around a feature.

Final takeaway

The most valuable ChatGPT feature is rarely the flashiest one. It is the feature that removes a predictable piece of friction while leaving you a reliable way to review the result. Organize context with Projects, control personalization with instructions and memory, isolate work with Temporary Chat, inspect files and data, revise in Canvas, choose Search or Deep Research according to depth, and schedule only what you can monitor. That combination turns occasional prompting into a calmer, repeatable way of working.
AI Agent Runtime Security in 2026: Permissions, Logs, and Guardrails for Production Teams

AI Agent Runtime Security in 2026: Permissions, Logs, and Guardrails for Production Teams

An AI agent becomes a security concern at the moment it can do more than produce text. Give it a repository token, a browser, a mailbox connection, a cloud role, or a tool that changes customer records, and a model decision can become a real system event. The practical question is no longer whether the model is intelligent enough to help. It is whether the runtime limits what the agent can reach, records what it actually did, and stops consequential actions when confidence is not enough.

AI agent runtime security is the control layer around an agent while it is operating. It includes workload identity, tool authorization, credential lifetime, network boundaries, data handling, approval gates, traceability, rate limits, and incident response. Prompt instructions still matter, but they cannot carry this burden alone. A sentence telling an agent not to delete production data is not equivalent to a database role that has no delete permission.

This article translates current guidance from OpenAI, OWASP, NIST, AWS, and Google Cloud into an operating model for production teams. The product examples are deliberately labeled. OpenAI SDK controls apply to that SDK, while AWS and Google Cloud identity features apply to their respective environments. The design principles remain useful across stacks, but the implementation details do not magically transfer from one product to another.

Why runtime security is different from model safety

Model safety asks whether a model will generate harmful, disallowed, or unreliable output. Runtime security asks what happens if the output is wrong, manipulated, or simply misunderstood. An agent might correctly summarize an email yet be tricked by instructions hidden inside that email. It might select the intended deployment tool but supply the wrong environment. It might retrieve far more customer data than the user needed. None of those failures requires a cinematic rogue AI. Ordinary ambiguity, prompt injection, stale context, or excessive permissions is enough.

OpenAI’s official agent safety guidance describes prompt injection as untrusted text attempting to override the system’s instructions. It also warns that private data can leak without a deliberate attacker, for example when a model sends more information to a connected tool than the user expected. Crucially, the guidance says mitigations reduce risk but do not make agents perfect. That is the right production assumption: the model is a fallible planner operating inside a security boundary, not the boundary itself.

OWASP frames a related problem as excessive agency. Its guidance identifies three common roots: excessive functionality, excessive permissions, and excessive autonomy. These are useful diagnostic categories. If a support agent only needs to look up an order, do not expose a general SQL console. If it needs read access, do not connect with a role that can update and delete. If a refund is allowed, do not let the agent issue it silently at any value. Each reduction removes a different path from mistaken text to harmful action.

Start with an inventory that describes power, not just software

A conventional application inventory usually names the owner, version, host, and data classification. An agent inventory needs those fields plus a map of its possible actions. Record every model, orchestration service, tool, connector, MCP server, plugin, queue, human approval step, and downstream identity. For each tool, capture whether it reads, creates, changes, sends, executes, or deletes. Also note the resources it can touch and whether an action can be reversed.

This is where many teams discover that the visible agent is not the only relevant identity. The orchestrator may call a tool gateway, which uses a shared service account, which reaches a database and an object store. An audit record that ends at the gateway leaves the final action unattributed. Map the chain from requesting user to agent run, tool call, workload credential, and downstream API event. The companion overview of non-human identity security for agents and cloud workloads explains why those machine identities need owners and life cycles of their own.

Inventory should be an operating process, not a spreadsheet created for launch day. Register an agent before production credentials are issued. Update the entry when a tool or scope changes. Disable its identity when the deployment is retired. Require a named service owner and a security contact, because an alert with no accountable recipient is only a log entry.

Build a permission model around one job

The cleanest production design gives each agent deployment a dedicated identity for one defined purpose. Separate the billing assistant from the incident triage agent, even if they use the same model and orchestration code. Separate development, staging, and production identities. Avoid one shared credential for several agents, because the combined role tends to accumulate every permission any of them needs and makes attribution weaker.

Cloud guidance supports this workload-oriented approach. AWS recommends temporary credentials with IAM roles for workloads and least-privilege policies that specify actions, resources, and conditions. Google Cloud recommends single-purpose service accounts and warns that sharing one across applications can widen privileges and make Cloud Audit Logs harder to attribute. Google also recommends avoiding service account keys where possible. These are provider-specific mechanisms, but they reinforce a general rule: issue a narrow, attributable, short-lived credential at runtime instead of placing a broad static secret in the agent’s environment.

Design the role from the intended transaction, not from the connector’s full menu. A document summarizer may need to read one collection but never share, move, or delete files. A code review agent may read pull requests and post a review comment but not merge to the protected branch. A deployment assistant may prepare a plan while the CI system, after approval, performs the change. The agent does not need every permission involved in the larger business process.

  • Limit resources: scope access to named repositories, buckets, tables, tenants, or queues.
  • Limit verbs: split read, propose, create, update, execute, send, and delete into separate permissions.
  • Limit context: carry the requesting user’s tenant and authorization into downstream checks where appropriate.
  • Limit time: prefer credentials that expire and require fresh authorization for later runs.
  • Limit environment: deny production access from development agents and untrusted execution contexts.

Do not ask the model to enforce these limits. OWASP recommends complete mediation, meaning downstream systems validate requests against security policy. The model may propose an action, but the tool gateway and target service must decide whether that identity can perform it. A denial should remain a denial even if a prompt insists that the situation is urgent.

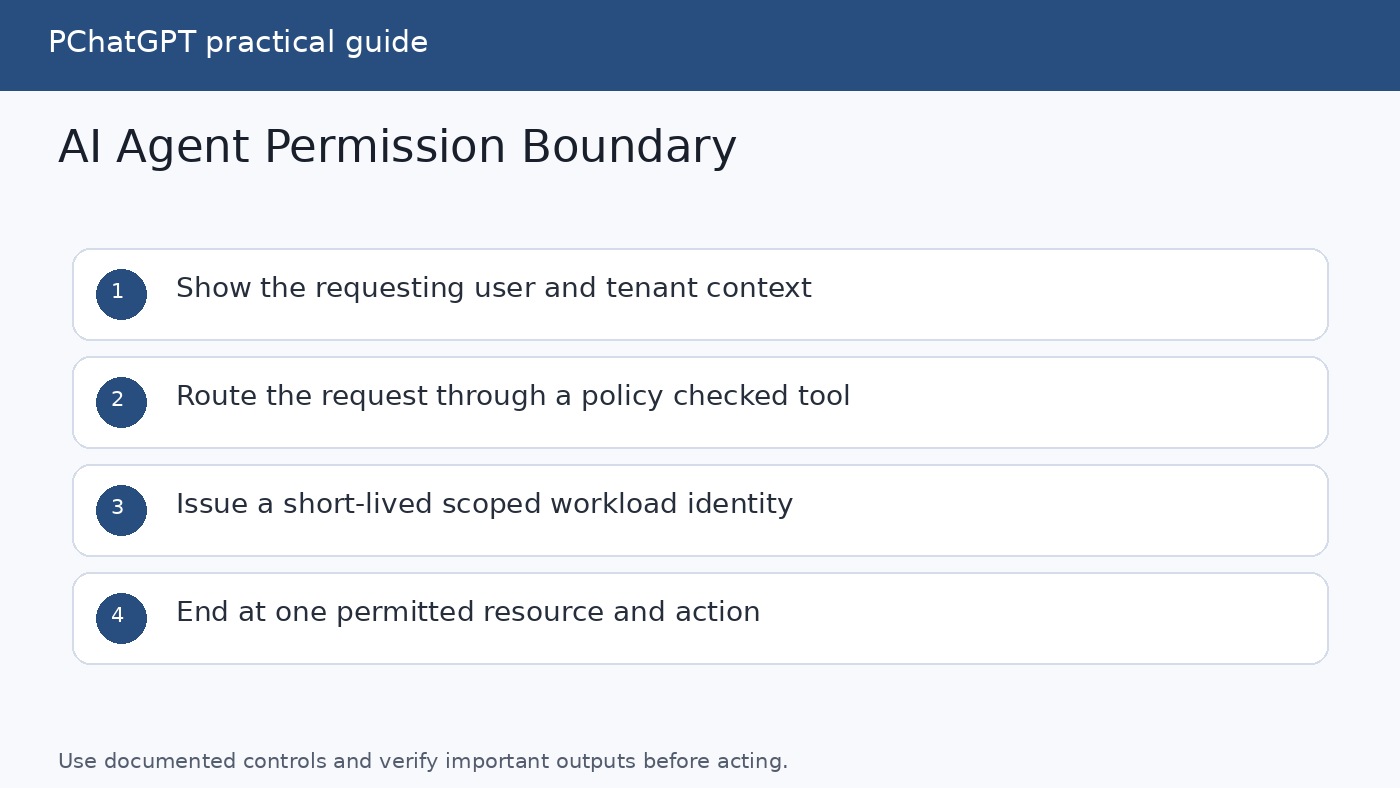
Layered AI agent permission path from user request to policy checked tool and scoped resource
A secure permission path preserves user context, checks the requested action at the tool boundary, and uses a narrowly scoped workload identity at the target.

Treat tools as security interfaces

A tool schema is more than a convenience for function calling. It is a security interface. A general tool such as run_command(text) gives an attacker or mistaken model a large language-shaped control surface. A narrow tool such as get_order_status(order_id) has a smaller action space, a typed parameter, and no write capability. OWASP explicitly recommends minimizing extensions, minimizing their functionality, and avoiding open-ended extensions where possible.

Validate every argument independently of the model. Enforce types, ranges, resource ownership, tenant boundaries, allowed destinations, and state transitions in code. Use allowlists where the business workflow permits them. For a money movement or message send, validate both the object and the recipient. Never treat a plausible model explanation as authorization.

Structured data also helps contain prompt injection. OpenAI’s Agent Builder safety guide recommends structured outputs between workflow nodes to constrain freeform channels, and it advises against placing untrusted variables in higher-priority developer messages. That is specific guidance for OpenAI’s Agent Builder workflow model. The broader engineering lesson is to keep retrieved documents, web pages, emails, and user text labeled as untrusted data, then extract only the fields required for the next step. A schema reduces the room for hidden instructions to travel, although OpenAI notes that structure and isolation reduce rather than eliminate risk.

Network policy should match the tool policy. If an agent only calls an internal ticket API and the model provider, arbitrary outbound internet access is unnecessary. Restrict egress destinations and protocols, isolate code execution, and prevent a tool from reaching metadata services or internal control planes unless that is its explicit job. This turns a broad exfiltration route into a small set of monitored channels.

Place approval gates at consequences, not everywhere

Human review is most useful when the reviewer sees a clear proposed consequence. Approving every read creates fatigue and teaches people to click through. Never asking for approval gives the agent autonomy where judgment belongs. Classify tool actions by impact and reversibility, then set approval requirements accordingly.

Low-risk, bounded reads may run automatically. A proposed change can be generated automatically but held for review. Sending external messages, modifying access, deploying code, moving money, disclosing regulated data, and destructive actions usually deserve stronger checks. The approval view should show the exact target, important parameters, source request, relevant diff, expected side effects, and the identity that will execute. Approval should authorize that specific action, not grant a reusable blank check.

OpenAI’s current Agents SDK documentation distinguishes input, output, and tool guardrails from human-in-the-loop approvals. In that SDK, a run can pause before a side effect and resume after an approval or rejection. This is an available OpenAI SDK pattern, not a claim that every agent platform behaves the same way. Whatever framework you use, put validation beside the tool that creates the side effect. OpenAI’s documentation specifically cautions that agent-level guardrails do not run at every possible boundary.

Guardrails should fail closed for sensitive operations. If a policy service is unavailable, a production deletion should not proceed because the approval check timed out. Define safe behavior for unavailable dependencies, expired approvals, changed parameters, duplicate requests, and retries. Use idempotency controls so a resumed or retried run cannot charge, send, or deploy twice.

Log the decision path and the system event

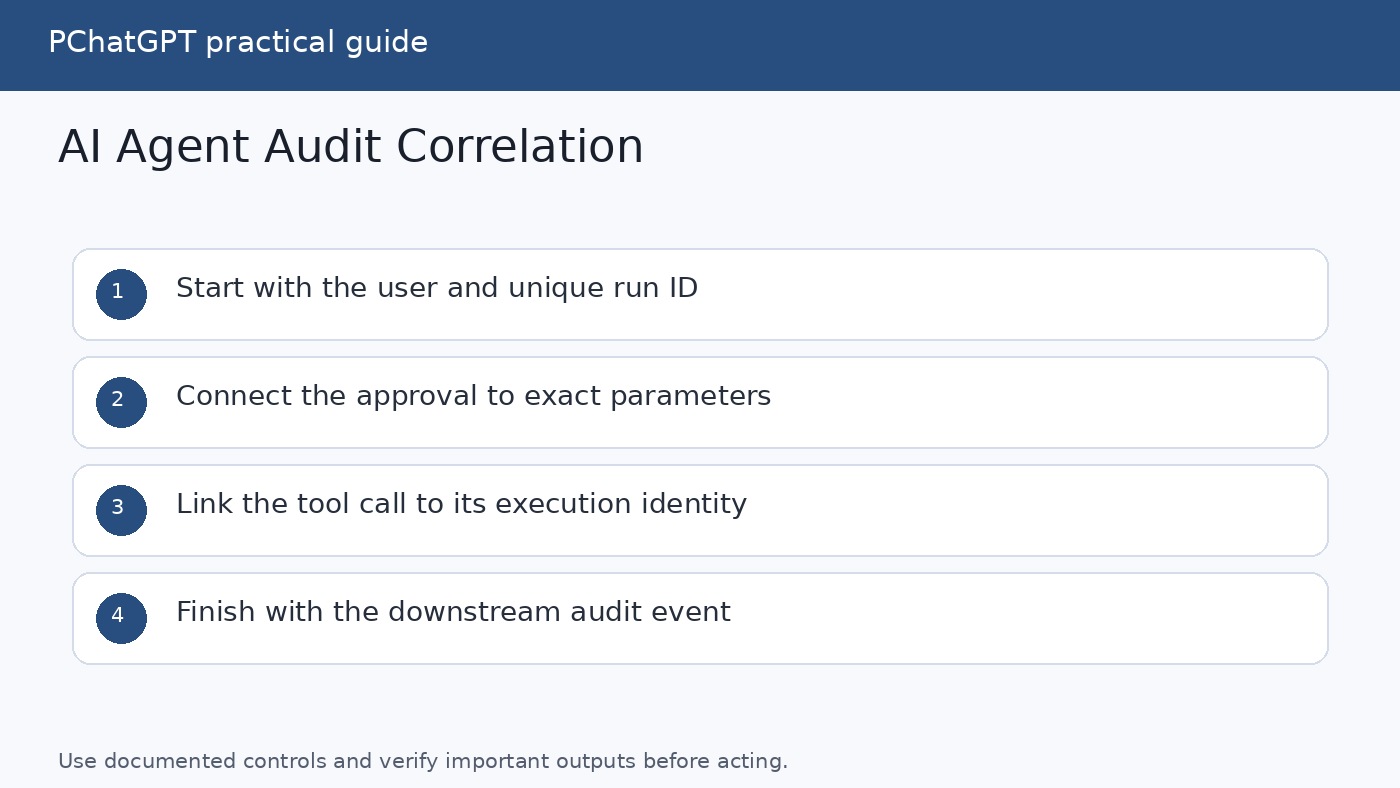
A conversational transcript alone is not an audit trail. It may omit tool arguments, credential identity, policy decisions, retries, and downstream results. Conversely, a cloud API log may show that a service account changed a resource without revealing which user request, agent version, or approval caused it. Production observability has to correlate both layers.

Assign a unique run identifier and propagate it through the orchestrator, tool gateway, approval service, and downstream request metadata where supported. For each material step, record the timestamp, requesting principal, agent and policy version, tool name, validated arguments or a safe representation, target resource, authorization result, approval identity, execution identity, outcome, latency, and error category. Record model and workflow versions needed for investigation, but do not assume that storing hidden reasoning is necessary or appropriate.

Logs can contain prompts, retrieved records, customer data, credentials, or tool output, so more logging is not automatically safer. Redact secrets before ingestion, minimize captured content, restrict log readers, encrypt storage, and set retention from legal, operational, and incident response needs. Keep the security event fields needed for attribution even when sensitive payloads are omitted or hashed. Test that a real on-call investigator can follow one run from request to final API event.

Cloud controls can strengthen this design. AWS describes CloudTrail records as an audit log of actions by IAM identities and AWS services, recommends centralized storage, and provides log file integrity validation. Google Cloud notes that a service account entry alone may not identify the application or person behind it and recommends correlating application or pipeline history with Cloud Audit Logs. These details apply to those cloud products, but the architectural point is universal: a shared machine identity without correlation leaves an accountability gap.

Correlated AI agent audit trail connecting user, run, approval, tool call, and cloud event
A useful audit trail links the human request to the agent run and approval, then continues through the tool identity to the provider or application event.

Detect behavior that permissions still allow

Least privilege limits blast radius, but allowed actions can still be abused. A compromised read-only agent might enumerate every customer record. A message agent may send an unusual volume to approved domains. Build detections around the agent’s expected job: new tools, denied actions, repeated policy failures, unusual resources, large retrievals, abnormal destinations, credential use outside the expected runtime, approval bypass attempts, and sudden changes in action volume.

Rate limits and quotas create time for detection and response. OWASP lists rate limiting as a way to reduce the damage excessive agency can cause, while noting that logging and limits do not prevent the underlying vulnerability. Apply limits by user, agent, tool, tenant, and high-impact action. A global request limit alone may miss a low-volume but sensitive operation.

Alert messages should include the run ID, owner, current credential status, and a safe containment action. Maintain a kill switch that can disable tool execution or revoke the workload identity without taking unrelated services offline. Exercise containment in a nonproduction environment and verify that queued, paused, and retried runs cannot continue after revocation.

Use governance to make the controls durable

NIST’s AI Risk Management Framework is voluntary and organizes risk work around Govern, Map, Measure, and Manage. Its Generative AI Profile applies those functions across the AI life cycle and emphasizes governance, content provenance, pre-deployment testing, and incident disclosure. It is not a product configuration checklist. For an agent program, it is best used to connect technical controls to ownership, risk tolerance, evidence, and recurring review.

Map each agent to its business purpose, affected users, data, dependencies, and credible failure modes. Measure with scenario-based evaluations that include indirect prompt injection, malformed tool arguments, cross-tenant requests, approval changes, unavailable policy services, excessive retrieval, and credential revocation. Manage findings through deployment gates and tracked remediation. Govern the whole process with named owners, exception expiry, incident criteria, and review schedules. The related article on practical generative AI governance rules offers broader organizational context.

Testing must examine the complete system, not only the model response. Verify that unauthorized calls are rejected downstream, sensitive parameters trigger approval, logs correlate, retries are idempotent, and the kill switch stops work already in flight. Re-run relevant scenarios when a model, prompt, tool, permission, policy, connector, or data source changes. A passed evaluation is evidence for one tested configuration, not a permanent certificate of safety.

A production rollout sequence that teams can operate

  1. Define the job: write the allowed outcomes, forbidden actions, data classes, and accountable owner.
  2. Map the path: enumerate inputs, tools, identities, networks, resources, approvals, and downstream logs.
  3. Remove capability: delete unused tools, replace open-ended tools with narrow functions, and separate read from write.
  4. Issue the identity: create a dedicated workload identity with temporary credentials and resource-level conditions where supported.
  5. Enforce at the boundary: validate every tool argument and authorize every request in code or a policy service outside the model.
  6. Gate consequences: require specific approval for high-impact or difficult-to-reverse actions, with clear context for the reviewer.
  7. Correlate evidence: connect user, run, approval, tool, identity, and downstream event while minimizing sensitive log content.
  8. Test failure modes: include prompt injection, over-broad retrieval, service outages, duplicate execution, revocation, and containment.
  9. Release narrowly: start with a small user group, bounded resources, conservative quotas, and an on-call owner.
  10. Review drift: compare actual tool and permission use with the declared job, then remove what is no longer required.

This sequence deliberately starts by removing power before adding detection. Monitoring a general shell tool with an administrator credential is not equivalent to replacing it with a purpose-built, read-only operation. Prevention, approval, detection, and response work together, but they are not interchangeable.

Frequently Asked Questions

Can prompt instructions provide enough security for a production agent?

No. Clear instructions can improve behavior, but untrusted content, ambiguous requests, and model errors can still influence a run. Enforce authorization, validation, resource scope, and approval outside the model so a persuasive prompt cannot grant permission.

Should every AI agent tool call require human approval?

Not necessarily. Requiring approval for every bounded read can create fatigue. Focus mandatory review on actions with meaningful side effects, sensitive disclosure, high value, broad scope, or poor reversibility. Keep automatic actions tightly scoped and observable.

What is the minimum useful audit record for an agent action?

At minimum, connect the requesting principal, run ID, agent and policy version, tool, target, authorization result, executing identity, outcome, and any approver. Preserve correlation to the downstream system event. Minimize or redact prompt and payload content that would expose secrets or personal data.

How often should an agent’s permissions be reviewed?

Review them whenever tools, workflows, data sources, environments, or business purposes change, and on a recurring schedule based on risk. Use observed access to remove unused permissions, but confirm that the observation window covers infrequent legitimate operations before making changes.

Sources

OpenAI Codex for enterprise engineering: lessons from Cisco-style AI workflows

0

OpenAI Codex is most useful in enterprise engineering when it is treated as a controlled software workflow, not a shortcut around engineering process. Large teams already have repositories, access rules, code owners, release windows, incident reviews, and security requirements. An AI coding agent has to fit into that system. If it works outside the system, it becomes another source of unreviewed change.

Cisco-style enterprise AI work is usually about scale, governance, and operational discipline. Cisco publishes broad AI material for infrastructure, security, and enterprise adoption, while OpenAI documents Codex as an agent for software engineering tasks. Bringing those ideas together leads to a simple rule: use Codex where it can create reviewable engineering artifacts, and keep people responsible for scope, approval, production risk, and release decisions.

Architecture before automation

The first enterprise question is not “can Codex write this code?” It is “what is Codex allowed to see and change?” Repository scope should be explicit. A documentation task may only need one folder. A test draft may need the feature module and test utilities. A bug fix may need logs, reproduction steps, and a small set of related files. Giving an agent the whole organization by default is convenient, but it also increases the chance of accidental changes and unnecessary data exposure.

A safe intake process starts with a ticket or issue. The ticket should state the problem, affected repository, allowed files or modules, constraints, test command, and reviewer. If the task touches authentication, payments, security controls, customer data, or deployment scripts, the default should be human-led work with Codex assisting only in narrow drafts or explanations.

Model access, secrets, and rate limits

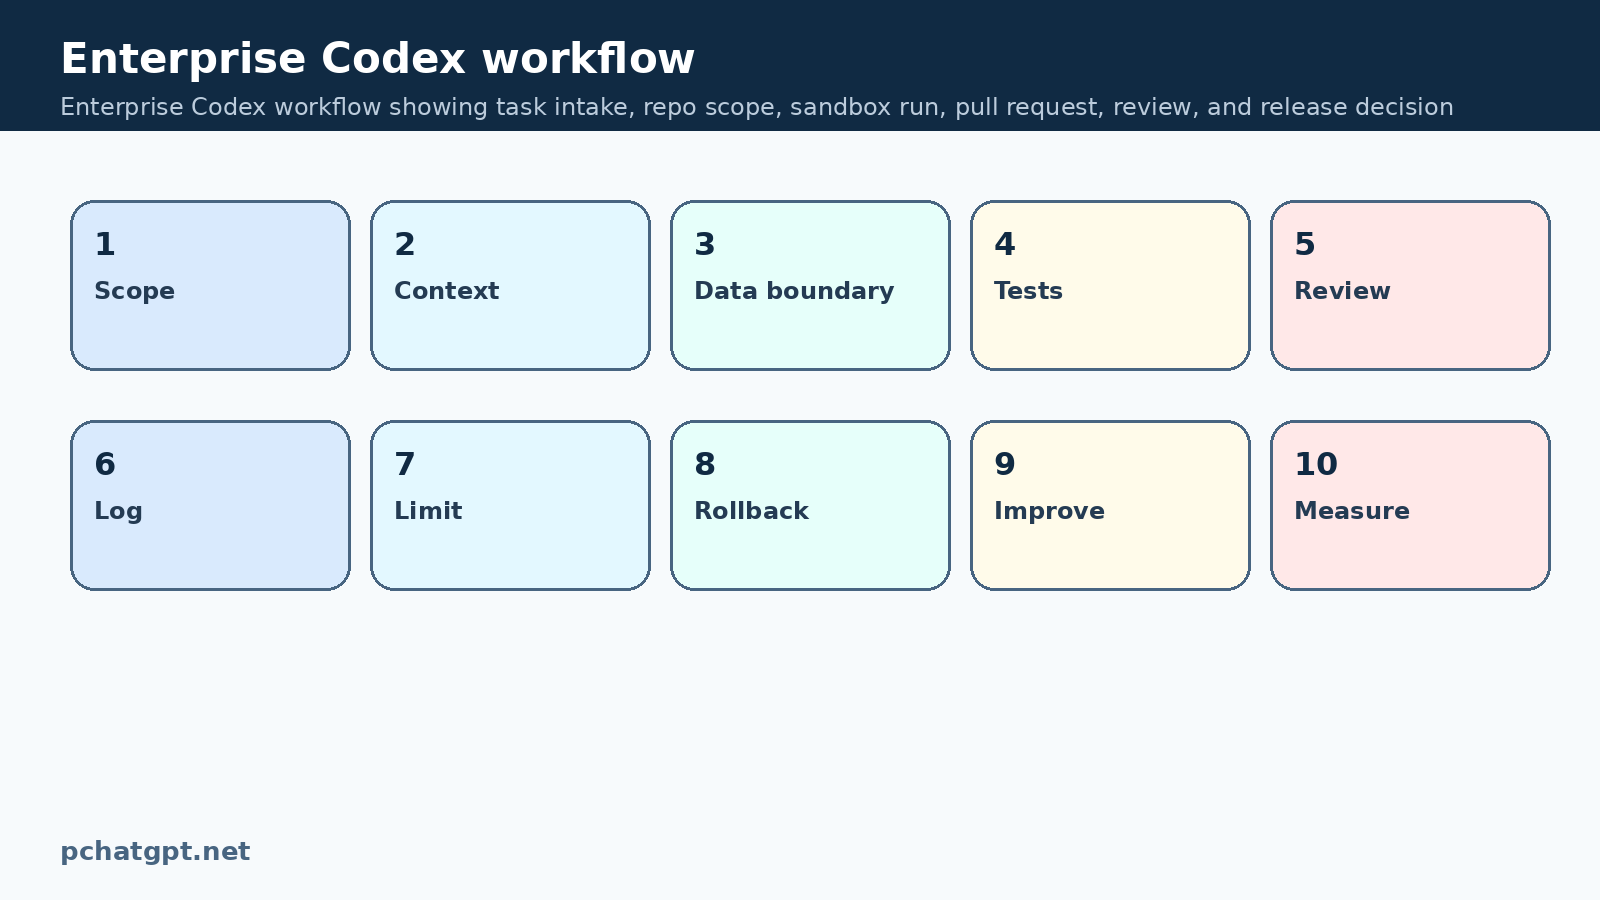
Enterprise Codex workflow showing task intake, repo scope, sandbox run, pull request, review, and release decision

The second question is environment. Codex can help with engineering tasks, but enterprise teams need to decide where commands run, which secrets are available, and whether network access is allowed. A sandbox with no production credentials is the safer default. If a test needs a secret, use a temporary scoped value or a mock. Do not expose production tokens to an agent just to make a local test easier.

Enterprise teams should also record what happened during the run. Keep the task brief, resulting patch, test output, and reviewer decision. This turns AI assistance into auditable engineering work rather than a private chat. It also makes it easier to learn which task types produce reliable patches and which ones waste review time.

The right runtime for the workload

Pull requests are the natural control point. Codex output should arrive as a diff that a person can inspect. The pull request description should explain the change, tests run, dependency changes, known limits, and any files the agent intentionally avoided. If the agent cannot provide that explanation, the reviewer should ask for it before reviewing the code itself.

Reviewers should start with the boundaries: did the patch stay inside the requested scope, did it change dependencies, did it touch secrets or logging, and did it remove tests? After that, they can review correctness. This order matters because a patch can look correct inside one function while creating a broader operational problem.

Cost, data boundaries, and review

OpenAI evaluation guidance is useful beyond model testing. Enterprise engineering teams can create lightweight evaluations for agent work. For example, track whether Codex changed files outside scope, whether tests passed, whether dependency changes were explained, whether reviewers requested major rewrites, and whether the change caused a rollback. These are practical signals, not academic scores.

A measured rollout might begin with documentation, test generation, code explanation, and small bug fixes. After several weeks, the team can compare review time and defect rates. If the evidence is good, Codex can handle larger but still bounded tasks. If the evidence is weak, the answer is not to ban the tool. Tighten the task template, reduce scope, and improve the test harness.

Observability and operating discipline

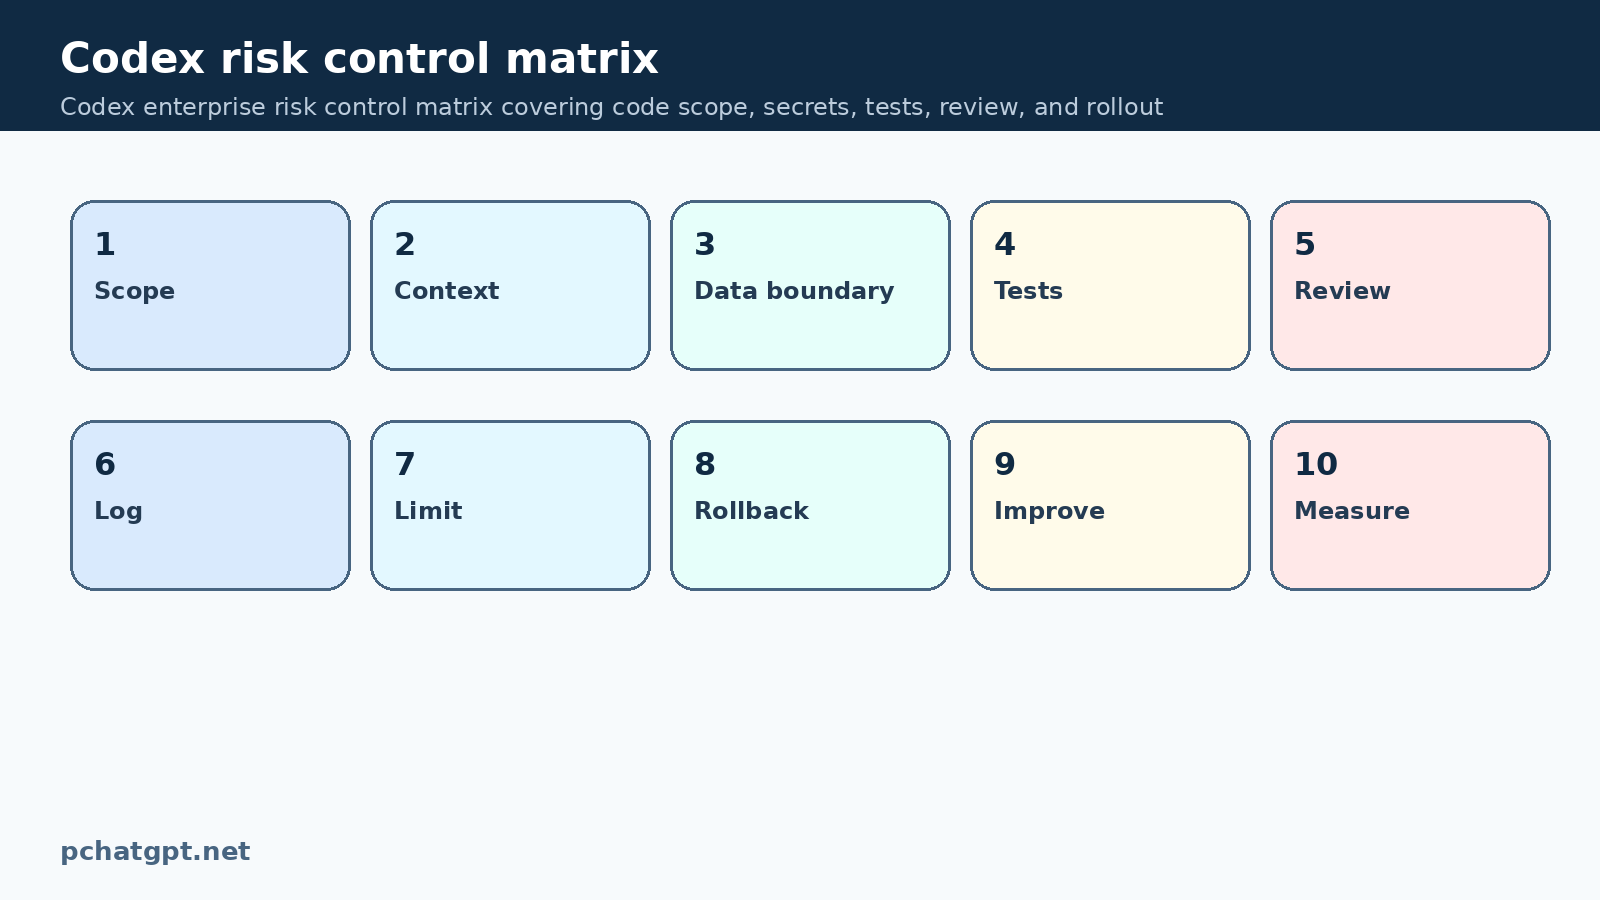
Codex enterprise risk control matrix covering code scope, secrets, tests, review, and rollout

Security teams should be involved early. AI coding agents interact with source code, build systems, logs, and sometimes issue trackers. That makes identity, access control, and data retention important. Decide which repositories are allowed, who can assign Codex tasks, how outputs are logged, and how long prompts or run artifacts are retained. The policy should be written in plain language so engineers can follow it during normal work.

Secrets deserve special treatment. An agent should not need production secrets for most coding tasks. If generated code touches configuration, environment variables, or credential handling, reviewers should inspect that section carefully. Also check for accidental logging of tokens, prompt content, or customer data. A helpful patch can still be unsafe if it makes private data easier to leak.

A practical adoption sequence

Enterprise architecture decisions should remain human decisions. Codex can compare files, draft migration steps, explain a library, or propose a refactor. It should not silently choose a new architecture, replace a critical dependency, or alter deployment policy. Those choices depend on business priorities, support capacity, compliance obligations, and incident history. The agent does not know those constraints unless the team writes them down and enforces them in review.

A useful operating model is to classify tasks by consequence. Low consequence tasks can be agent drafted and lightly reviewed. Medium consequence tasks need owner review and test evidence. High consequence tasks need senior review, security review, or manual implementation with Codex limited to research and explanation. This classification is easier to follow than a vague rule such as “use AI responsibly.”

What to do next

The long term value of Codex in enterprise engineering comes from process learning. Each accepted task teaches the team which prompts, tests, and boundaries work. Each rejected task teaches where the workflow is too broad or the codebase lacks enough tests. Keep a short record of both. Over time, the organization builds an internal playbook instead of relying on vendor demos or scattered enthusiasm.

Codex should make engineering work more reviewable, not less. If it produces smaller pull requests, clearer test plans, and faster explanations of unfamiliar code, it is helping. If it produces large diffs, unexplained dependency changes, or patches that reviewers do not understand, narrow the scope. Enterprise AI adoption succeeds when automation fits inside accountable engineering practice.

Implementation checklist

Before publishing the workflow, write a one page operating note for OpenAI Codex enterprise engineering. Include the owner, allowed users, data that may enter the system, data that must stay out, expected output, review rule, test command, cost limit, and rollback path. This note keeps the article topic grounded in a real working procedure rather than a vague promise. It also gives reviewers something concrete to compare against when the tool behaves differently from the original plan.

Review the setup after the first few real tasks. Check whether OpenAI Codex enterprise engineering saved time, whether users trusted the output too quickly, whether logs were enough to diagnose errors, and whether any step encouraged unsafe copying of private data. Keep the parts that worked, remove unused automation, and tighten the brief where reviewers found repeated mistakes. Small corrections made early are cheaper than repairing a broad system after users depend on it.

A second check should focus on the reader. Someone arriving from search should understand what problem OpenAI Codex enterprise engineering solves, what the tool can do today, what still needs human judgment, and which official documents support the workflow. If a paragraph could appear in any AI article, rewrite it around the actual task. If a claim depends on a product feature, link to the official documentation. If the article suggests an operational habit, make the owner and review point clear.

The final pass is simple: keep the URL stable, keep the promise narrow, and make the article useful to a person who has to configure or review OpenAI Codex enterprise engineering tomorrow. Plain instructions, named controls, and honest limits are better than broad claims about transformation. That is also the safest way to improve an older search page without creating another generic article.

For teams using this guide as a cleanup pass, compare the new article with the old version before calling the job finished. The refreshed page should no longer depend on repeated prompt boilerplate, generic productivity advice, or a copied FAQ. Each section should answer a real search intent for OpenAI Codex enterprise engineering, and every recommendation should be something a reader can apply without guessing which product surface or workflow the article means.

For enterprise Codex adoption, separate product documentation from operating governance. OpenAI sources can support Codex and evaluation workflows, while enterprise AI material can frame broader adoption needs. The article should not imply that any named company endorses the exact process here. It should show how an engineering organization can turn agent output into scoped pull requests, reviewer evidence, and measured rollout decisions.

For OpenAI Codex enterprise engineering, the publication check should also include basic maintenance questions. Who updates the article when the official documentation changes? Which internal link should send readers to a deeper guide? Are image ALT texts specific enough to describe the diagram? Are the FAQ answers short, direct, and different from each other? These small editorial checks reduce low value signals because the page stops looking like a reused shell. They also make the next review faster because evidence, limits, and update ownership are already visible. If one section reads like a generic AI safety paragraph, replace it with a task-specific decision, such as which repository, data class, runtime, reviewer, or official source the reader should check first.

A short owner note should say what changed in the rewrite, which source was checked, and what would trigger another update. That makes OpenAI Codex enterprise engineering easier to maintain during later corpus reviews and prevents the same boilerplate from creeping back into the post.

Official sources used

Related guides

FAQ

Is OpenAI Codex suitable for enterprise engineering teams?

Yes, when the team controls repository scope, runs work in safe environments, reviews pull requests, and measures quality before expanding use.

What should Codex be allowed to change first?

Start with documentation, tests, code explanations, and small bug fixes. Avoid production infrastructure, authentication, payment, and security sensitive changes until the workflow is proven.

How should enterprises measure Codex quality?

Track scope violations, test results, dependency changes, reviewer rewrite rate, rollback rate, and whether the task saved reviewable engineering time.

Can Codex replace senior engineering review?

No. Codex can draft and explain code, but senior engineers still own architecture, security, release risk, and business tradeoffs.

How to Use ChatGPT for Research, Writing, Data, and Automation

ChatGPT becomes much more useful when you stop treating every conversation as a fresh request and start treating it as part of a controlled workflow. The practical goal is not to get a perfect answer in one try. It is to move from a real source, through a visible process, to an output that a person can check and use.

This guide shows how to use ChatGPT for research, writing, data work, and cautious automation. Each workflow has a clear input, a specific job, an expected deliverable, and a review point. That structure matters more than a collection of magic words. It also makes a successful process easier to repeat or hand to a colleague.

Begin with a one minute task brief

Before opening a new chat, write a compact brief. Name the outcome, reader, source material, boundaries, and acceptance test. If one of those pieces is unknown, say that it is unknown instead of letting ChatGPT quietly fill the gap.

  • Outcome: the decision, document, analysis, or action you need.
  • Audience: who will read or use the result and what they already know.
  • Evidence: the notes, files, websites, or data that may support the work.
  • Boundaries: subjects to exclude, confidential details to remove, and claims that need approval.
  • Format: a table, outline, email, report, checklist, or another defined deliverable.
  • Review: the person responsible for checking facts, tone, calculations, and consequences.

A useful opening prompt is: Help me produce [deliverable] for [audience]. Use only [provided material or named sources]. Preserve [important terms]. Mark missing evidence instead of guessing. Return [format], followed by a short verification checklist. This does not guarantee accuracy. It creates a contract that makes omissions and drift easier to spot.

Choose the lightest ChatGPT tool that fits

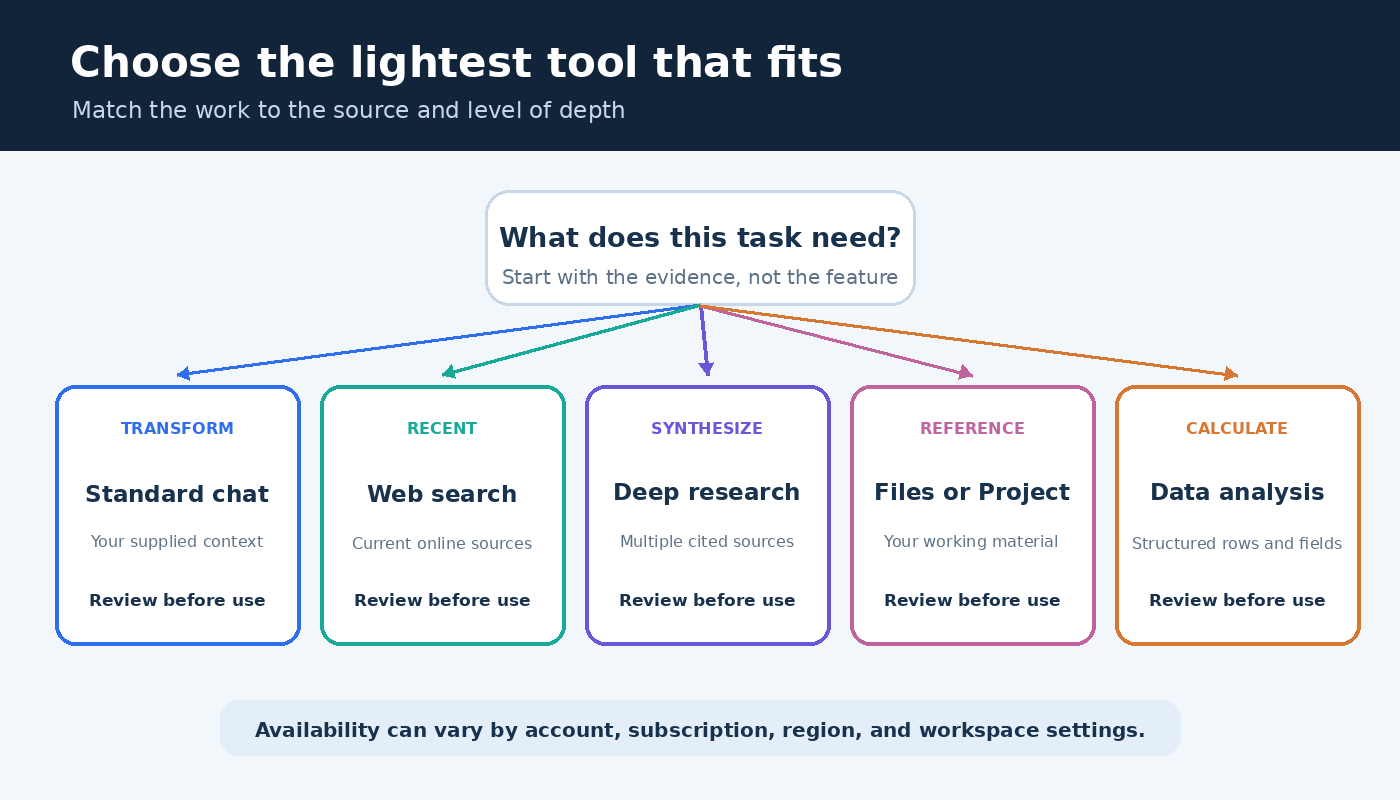
Standard chat is a good starting point for explanation, transformation, brainstorming, and work grounded in material you paste. Web search is more appropriate when recency or online sources matter. Deep research is designed for multi-step questions that require synthesis across sources. OpenAI says deep research can work with the public web, uploaded files, selected sites, and enabled apps, then produce a report with citations or source links. Its plan can be reviewed and adjusted before work begins. Read the official deep research guide for the current controls and availability.

Uploaded files are useful when the answer should be anchored to your own documents. Structured data may be better handled with data analysis than with a long pasted table. Projects can keep chats, files, and project instructions together for ongoing work. OpenAI’s Projects documentation explains how those sources and instructions are organized. Feature access can vary by account, subscription, region, and workspace settings, so use the tools visible in your interface rather than assuming every account looks the same.

Decision map for choosing ChatGPT chat, search, deep research, files, or data analysis based on the work
Start with the work itself: choose a mode based on recency, research depth, private source material, or structured data.

A source-first research workflow

Research quality improves when source selection happens before summary writing. Begin by turning the assignment into a small question tree. Write the main question, the decisions the answer will inform, the claims that need evidence, and the kinds of sources that could settle each claim. This prevents an attractive report from hiding a weak evidence base.

  1. Define scope. State the topic, geography, audience, exclusions, and what a satisfactory answer must cover. Do not add dates or numerical thresholds unless they come from the assignment or a source.
  2. Set source rules. Prioritize primary documentation, original research, official statistics, or direct records as appropriate. Tell ChatGPT to separate source statements from its own synthesis.
  3. Review the plan. For deep research, inspect the proposed plan and source choices. Add missing questions and remove branches that do not support the decision.
  4. Request an evidence table. Ask for columns covering claim, source, exact support, caveat, and verification status. A prose answer can come later.
  5. Open important sources. Confirm that each link works, the cited page says what the report claims, and the context has not changed the meaning.
  6. Write from verified notes. Ask for a synthesis based only on entries you have accepted. Keep unresolved disagreements visible.

Use a prompt such as: Create a research plan for the question below. Break it into answerable subquestions. For each one, name the preferred source type and explain what evidence would support or challenge the conclusion. Do not begin the final report until I approve the plan. After approval, request the evidence table. If a source is inaccessible or only partially relevant, label that limitation rather than treating it as support.

Citations are navigation aids, not automatic validation. Open the decisive references yourself. Check whether a source is primary, whether the passage supports the exact claim, and whether qualifications were dropped. When sources disagree, preserve the disagreement and explain what additional evidence would resolve it. This workflow is slower than accepting the first summary, but much faster than rebuilding a decision after a bad claim is discovered.

A writing workflow that keeps the author in control

Writing is easier to review when planning, drafting, and editing are separate passes. Start with your own purpose and evidence. Ask ChatGPT to diagnose the material before it writes prose: identify the central point, likely reader questions, missing support, and possible structures. Select the structure yourself.

Next, create an evidence-aware outline. Every major section should have a job and a source note. If a section has no evidence, decide whether it is interpretation, an example, or a gap. Then draft one section at a time. Smaller drafts make it easier to catch unsupported transitions and keep your voice. Our guide to using ChatGPT for writing without cheating adds practical guidance for authorship, disclosure, and review.

A strong section prompt can read: Draft this section from the approved outline and notes. Keep the stated audience and purpose. Do not add facts, quotations, examples, or references. If the notes do not support a sentence, insert [evidence needed]. End with a list of claims I should verify.

Do not ask for vague improvement in the revision pass. Assign one editorial lens at a time:

  • Accuracy pass: list factual claims and connect each one to supplied support.
  • Structure pass: find repeated ideas, missing transitions, and sections that do not advance the purpose.
  • Reader pass: flag jargon, undefined terms, and steps that assume hidden knowledge.
  • Voice pass: identify generic phrases and sentences that do not sound like the author.
  • Final proof: check grammar and formatting without changing meaning.

Compare revisions instead of replacing your draft blindly. Accept the changes that solve a named problem and reject those that flatten your viewpoint. Keep original source notes beside the draft until publication. If you want reusable starting points for narrower daily tasks, see these ChatGPT productivity prompts, then adapt their structure to your own evidence and approval rules.

A data workflow built around inspection

For tables and spreadsheets, prepare the file before asking for analysis. OpenAI recommends descriptive headers, plain language column names, and one record per row. Avoid unrelated tables in one sheet and blank rows or columns that split the data. The official data analysis guide also advises reviewing generated code, outputs, methods, and assumptions before relying on a result.

Begin with a data inventory, not a conclusion. Ask ChatGPT to report the sheet names, columns, data types, missing values, duplicate patterns, and suspicious units. Then confirm the intended unit of analysis. A row might represent a transaction, customer, survey response, or monthly total, and confusing those levels can invalidate the result.

After the inventory, state the calculation in ordinary language. Define filters, groupings, denominator, treatment of missing values, and desired output. Ask for an analysis plan before execution. When code is used, inspect it or have a qualified reviewer inspect it. Reconcile at least one important total with the source file or another trusted method. Charts need the same care: check labels, scales, grouping, and whether the visual answers the intended question.

A practical request is: First inspect this file and describe its structure and quality issues. Do not calculate the final metric yet. Then propose a method using the definition below, list assumptions, and show the fields involved. Wait for approval before running the analysis. This staged approach makes a wrong column or denominator visible while it is still easy to correct.

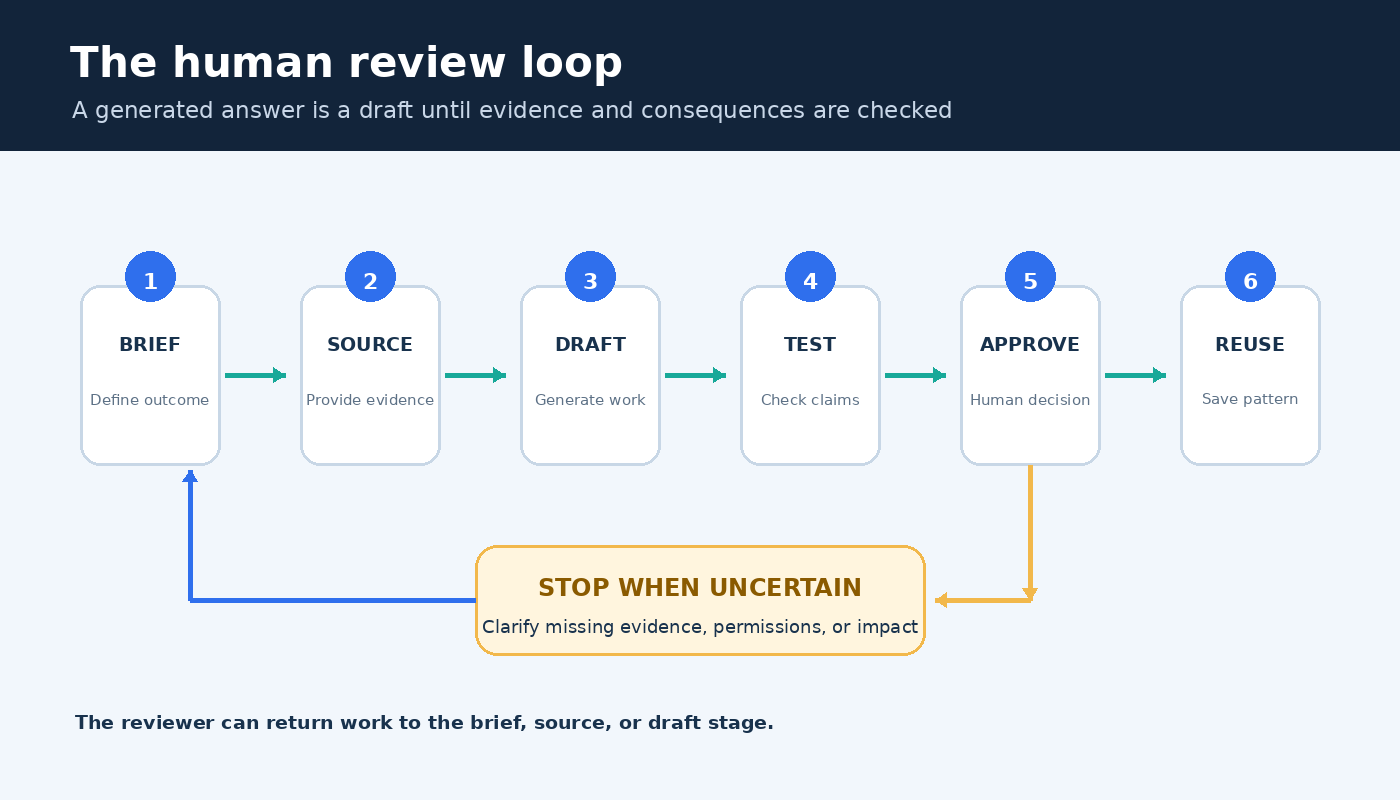
Human review loop for ChatGPT work showing brief, source, draft, test, approval, and reuse stages
A reliable workflow keeps human checks between generated work and any consequential action.

Turn a successful conversation into a reusable system

Reuse should begin only after a workflow has succeeded on real material. Save the brief, input pattern, prompt sequence, expected output, review checklist, and a sanitized example. Record failure conditions as carefully as the happy path. A template that works only when the source is complete should say so.

For ongoing work, a Project can keep relevant chats, references, and instructions together. Keep project instructions short and operational: name the audience, preferred format, approved sources, vocabulary rules, and when to stop for clarification. Do not use project context as an excuse to omit the current task. Files change, goals shift, and an explicit brief helps expose stale assumptions.

Version reusable prompts like working documents. Note what changed and why. Test a revision against an ordinary example, an incomplete input, and an awkward edge case from your real workflow. The objective is not identical prose every time. It is predictable handling of evidence, uncertainty, formatting, and escalation.

Approach automation as controlled delegation

Automation begins when output can trigger a later step, such as creating a ticket, updating a record, sending a message, or scheduling another task. That raises the cost of an error. Start with read-only or draft-only assistance. Let ChatGPT classify incoming material, prepare a proposed update, or draft a response while a person approves the actual change.

Map the workflow before connecting anything. List the trigger, data read, transformation, destination, permissions, possible side effects, and recovery method. Remove unnecessary private information. Use the narrowest access available. Keep a visible log that lets a reviewer connect the input, generated output, approval, and final action.

Define a stop condition for ambiguity. If the input is incomplete, the recipient is uncertain, a claim lacks support, or an action is difficult to reverse, the workflow should pause. The right fallback is often a short review queue, not a more elaborate prompt. OpenAI’s capabilities overview is a useful starting point for checking which built-in tools may be available, but actual controls depend on the account and workspace.

The review gate before you use an answer

Use a final checklist that matches the consequence of the work. A private brainstorming list needs a lighter review than a public claim, customer message, financial calculation, or system update. For important output, confirm that the answer addresses the brief, every material fact has support, calculations match the intended method, private data is handled appropriately, and a named person owns approval.

Also inspect what is absent. ChatGPT may produce a polished answer without exposing missing evidence, competing explanations, or an unasked stakeholder need. Ask it to critique the output against the original acceptance test, but do not let that self-critique replace human review. The person using the result remains responsible for its fit, accuracy, and consequences.

Frequently asked questions

What is the best first ChatGPT workflow for a beginner?

Choose a low-risk task with a source and an answer you can easily compare, such as turning your own meeting notes into an action list. Provide the intended format and ask ChatGPT to mark uncertain items. Check every owner, commitment, and deadline against the notes before using the list.

When should I use deep research instead of normal chat?

Use normal chat for quick explanations, transformations, or discussion based on supplied context. Consider deep research for a multi-step question that needs synthesis across several sources and a documented report. Review its plan and verify the decisive citations yourself.

Can ChatGPT verify its own writing or analysis?

It can help expose claims, assumptions, inconsistencies, and possible errors, but that is not independent verification. Check important claims against original sources and reconcile calculations with the source data or another trusted method. Use a qualified reviewer when the subject requires specialist judgment.

How do I make a ChatGPT workflow safe to automate?

Begin with draft-only output, narrow permissions, clear logs, defined stop conditions, and human approval before consequential actions. Test with ordinary and incomplete inputs. Automate only the portion that remains predictable after review, and keep a recovery path for mistakes.

Generative AI governance: practical rules for safer business use

Generative AI governance should be close to daily work. If the rules sit in a long document that nobody opens, employees will keep using chatbots, copilots, meeting tools, and image generators without a shared standard. A useful program tells people what they can use, what data is allowed, when review is required, and who owns the risk.

This guide keeps the old business AI topic but removes recycled advice. It uses current governance concepts from sources such as the NIST AI Risk Management Framework, ISO AI management guidance, OECD AI principles, OpenAI data controls, and OpenAI safety guidance. The result is a practical operating model for teams that want AI benefits without pretending the tools are harmless.

Make the approved tool list visible

The first governance control is visibility. A company needs to know which AI tools employees use for drafting, coding, meetings, research, design, support, sales, and automation. Without that list, risk hides in browser extensions, free accounts, shared passwords, and personal subscriptions.

Keep the list short at first. Name the tool, owner, purpose, allowed data, account type, review date, and business reason. Mark each tool as approved, approved with restrictions, or not approved for company data. This gives employees a safe default and reduces the pressure to guess during a deadline.

Classify data before it enters a prompt

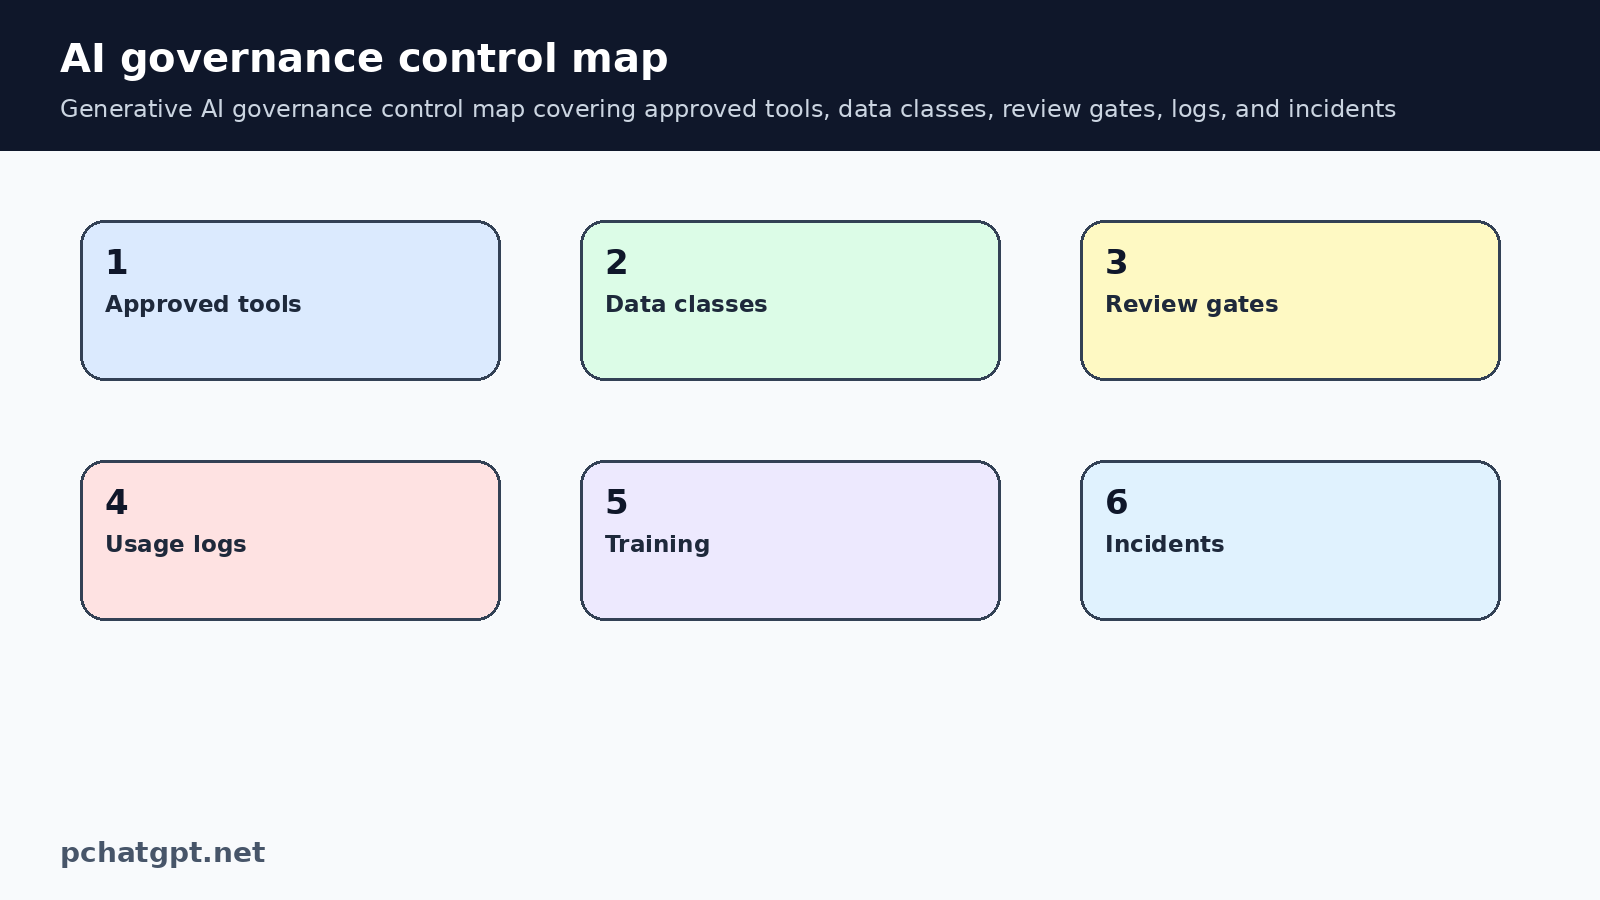
Generative AI governance control map covering approved tools, data classes, review gates, logs, and incidents

Most AI governance failures start with data. A prompt can contain customer names, contracts, financial details, employee records, source code, strategy, credentials, health information, or confidential product plans. Employees may think they are asking a quick question, but the prompt still transfers information into a system.

Use plain data classes that people can remember: public, internal, confidential, and restricted. Public content may be acceptable in approved tools. Internal content may require business settings. Confidential and restricted data should need stronger approval or should stay out of general tools entirely. Long legal wording is less useful than clear examples.

Put human review where consequences are real

Generative AI can draft emails, summarize documents, write code, create images, and suggest decisions. It should not quietly make consequential decisions. Define the work that needs a qualified human review before anything is sent, merged, published, purchased, or used with a customer.

High review areas include legal language, financial advice, hiring, healthcare, security changes, customer support responses, public announcements, pricing, access decisions, and code that affects production systems. The rule can be simple: if a wrong answer can harm a person, customer, partner, or business process, a person must review it.

Log important use without saving everything forever

Governance does not require saving every casual brainstorm. It does require enough record keeping for higher risk workflows. A useful log captures the tool, user, date, purpose, data class, prompt summary, source material, reviewer, and final action.

Logs help when something goes wrong. If a customer receives a bad answer or a report includes unsupported claims, the team can trace the workflow and fix the control. Logs also help managers see which AI use cases create value and which ones only create noise.

Train with real examples from the team

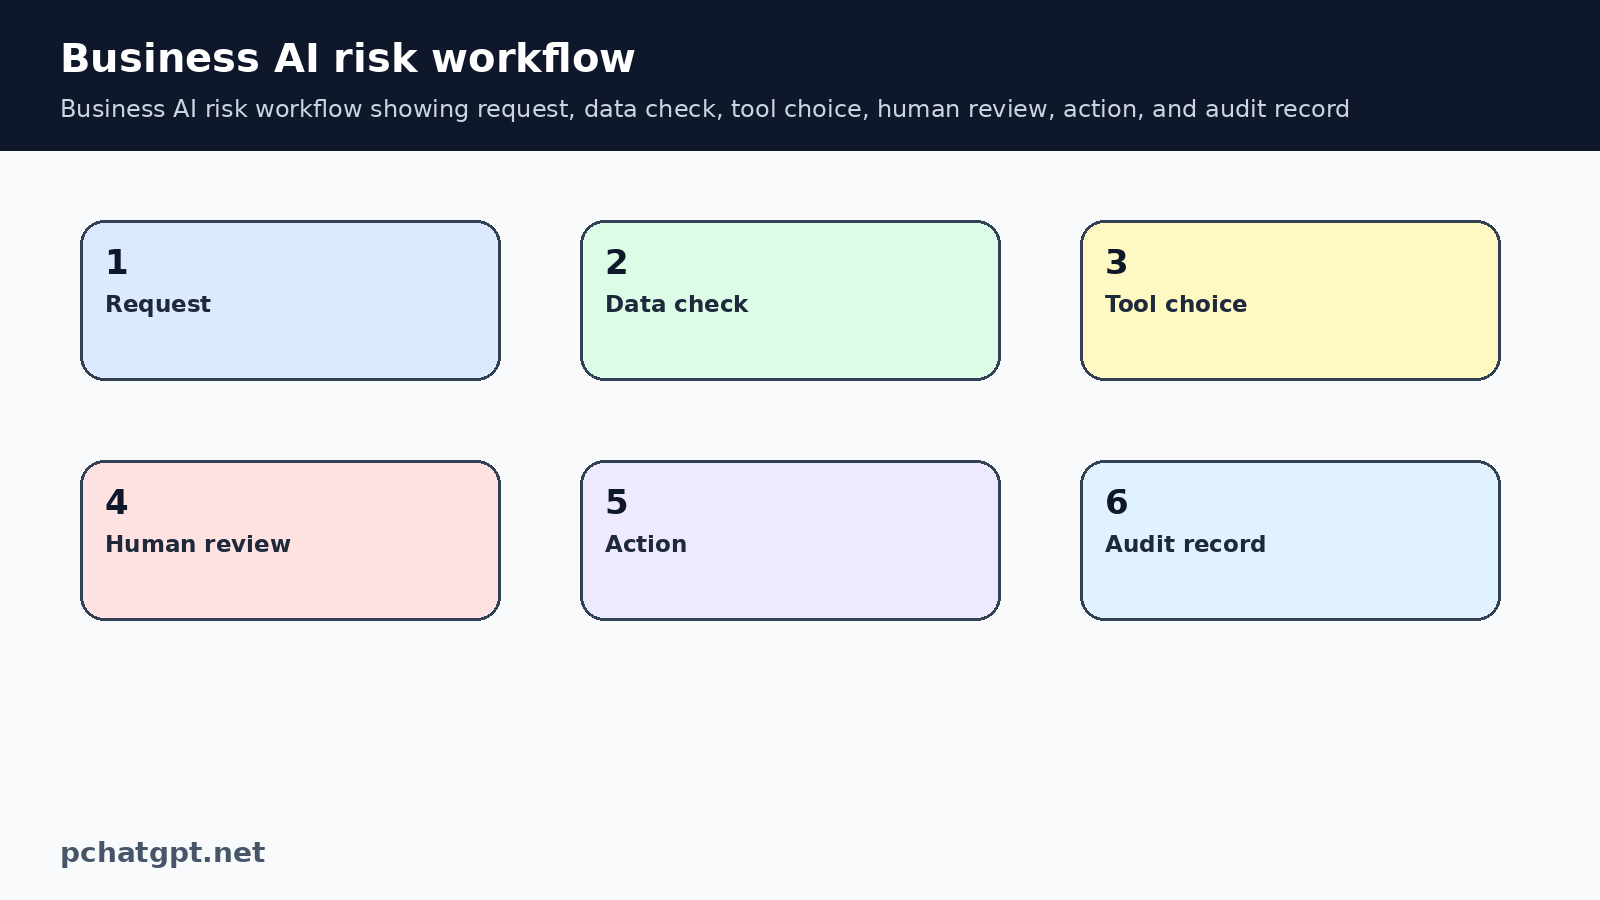
Business AI risk workflow showing request, data check, tool choice, human review, action, and audit record

AI training should use examples from the actual work. Show a safe prompt and an unsafe prompt. Show how to remove personal data. Show when to use an approved account. Show how to check sources. Show where to report a risky output.

Training should also teach healthy skepticism. A polished answer is not the same as a correct answer. Employees need to know how hallucinations happen, why source checks matter, why copied confidential data is risky, and why some decisions need human judgment even when the draft looks convincing.

Check vendors before connecting workflows

The risk changes when AI connects to email, CRM, file storage, calendars, code repositories, support desks, or payment systems. A chatbot that only drafts text is different from an agent that can take actions. Vendor review should match the level of access and consequence.

Before connecting a tool, ask what data it can read, what actions it can take, how permissions work, how logs are kept, how exports and deletion work, and who can approve changes. For higher risk systems, require staged rollout, limited permissions, and a rollback plan.

Use recognized frameworks without drowning the team

NIST frames AI risk work around governing, mapping, measuring, and managing risk. ISO AI management guidance and OECD principles also push teams toward accountability, transparency, safety, privacy, and human oversight. These sources are useful because they give structure, but small teams still need a simple version.

Translate the framework into a working checklist. What is the AI use case? What data enters it? Who is affected? What could go wrong? How will the output be checked? Who owns the decision? What record is kept? That checklist is more useful than a policy that sounds mature but does not change behavior.

Review the policy as products change

AI products change quickly. Plan labels, data controls, admin features, model behavior, connectors, and safety settings can shift. Governance should include a review date for tools and workflows. If a tool gains new access or moves into customer facing work, the review should happen sooner.

The policy should also name what is not allowed. Do not allow employees to paste secrets into prompts. Do not allow AI to send customer messages without approval if the message can affect trust or obligations. Do not allow generated facts into public material without source checks. Clear no rules make the yes rules safer.

Maintenance notes for editors

Keep this page tied to generative AI governance, not to a broad claim that every AI product is useful. Future updates should start by opening the official pages already cited, checking the product surface named in the section, and removing any claim that no longer has a visible source. If a new feature sounds interesting but the source does not describe it clearly, leave it out until it can be verified.

For generative AI governance, the article should also keep its old URL and search intent. Do not turn this post into a news reaction or a general opinion piece during routine cleanup. The useful version of the page explains what a reader can check today, how to limit risk, and when another tool or human review is needed. That practical boundary is what makes the refreshed article more useful than the previous boilerplate.

When adding examples about generative AI governance later, avoid invented performance numbers, launch dates, user counts, prices, benchmarks, or regional availability. Those details can change and they need a direct source. A plain limitation is better than a confident sentence that cannot be checked. Readers trust the page more when it says less and supports the claims it keeps.

Internal links for generative AI governance should stay close to the reader journey. One link can help compare related AI tools. Another can point to safety, governance, memory, or workflow guidance. Do not add unrelated links only to raise a count. The link should answer the next question a careful reader is likely to ask.

The diagrams in this generative AI governance page should teach a process. If the images are replaced later, keep the same standard: clear labels, useful ALT text, strong contrast, and a relationship to the surrounding paragraph. Decorative robot art may look fine, but it does not help a reader make a better decision.

Before saving a future generative AI governance edit, read the page aloud once. Remove phrases that sound like a sales brochure, especially broad claims about transformation, productivity, or innovation. Keep the sentences concrete. Name the setting, workflow, source, review step, or risk. That style is better for readers and safer for an AdSense quality review.

If a future editor wants to add comparisons around generative AI governance, require the same evidence standard for every product mentioned. Compare what the product page says, what the account controls allow, and what a user can verify without private access. Do not rank tools by vibes, screenshots, or affiliate style language.

Keep the generative AI governance FAQ narrow. Each question should resolve one practical concern: tool choice, privacy, review, cost, or policy. If an answer repeats a section above, rewrite it into a shorter decision rule. A concise FAQ helps searchers who scan, and it prevents the page from turning into padded text.

The final live check for generative AI governance should use the public page, not only the editor. Confirm that the canonical still points to the preserved URL, the page remains indexable, both body images load, and the article has no old repeated paragraph from the earlier corpus audit. Save that proof beside this batch so the next remediation run can trust the result.

If the article becomes too broad, split the extra idea into another guide and link to it only when it helps the reader. This keeps generative AI governance clear, avoids topical overlap with nearby posts, and gives the corpus a cleaner set of search intents.

A useful generative AI governance update should include one practical boundary near every major recommendation. Say what the tool can help with, then say what still needs checking by the reader. This rhythm prevents unsupported promises and makes the guidance easier to trust when product pages, plans, or controls change later.

For generative AI governance corpus cleanup, the most important signal is not raw length. Length only helps when it adds original structure, source based limits, and task specific advice. If a new paragraph could be copied into another AI article without changing meaning, rewrite it before publishing.

Keep one small generative AI governance reader scenario in mind while editing. A person has landed on this URL because they need to choose, control, or explain something today. The article should help that person make a safer next move without asking them to trust a vague AI trend summary.

Official sources used

Related guides

FAQ

What is generative AI governance?

Generative AI governance is the set of practical rules, owners, reviews, and controls that guide how a team uses AI tools. It covers tool approval, data handling, human review, logging, training, vendor checks, and incident response.

Does governance slow down AI adoption?

Good governance should reduce confusion rather than block useful work. Employees move faster when they know which tools are approved, what data is allowed, and when review is required.

Which AI work needs human review?

Any work with real consequences should be reviewed by a qualified person. That includes legal, financial, healthcare, hiring, security, customer support, public claims, pricing, access, and production code decisions.

How often should an AI policy be reviewed?

Review the policy whenever a tool gains new access, moves into a higher risk workflow, or changes important controls. A regular scheduled review also helps catch stale product assumptions.

Five lesser known AI tools: when specialist apps beat a blank chatbot

0

Lists of lesser known AI tools often feel random. A focused app is not useful because it is obscure. It is useful when it fits a task so closely that a blank chatbot starts to feel clumsy. That is the standard this article uses.

The five tools below cover different jobs: focus music, presentations, research capture, family planning, and personal knowledge. The point is not to claim they replace ChatGPT. The point is to show when a narrower product can be worth testing, and how to test it without adding subscription clutter.

Use a one week trial, not a vague impression

A specialist AI app needs a practical trial. Pick one job, use the tool for a week, and write down what changed. Did it save time? Did it reduce copying and pasting? Did it create cleaner output? Did it make review easier? A vague feeling that the product is clever is not enough.

This matters because many AI tools look good for a day. The real test happens when the same task repeats. A student, founder, creator, manager, or parent can all benefit from a focused workflow, but only if the tool solves a real friction point.

Brain.fm for attention, not content generation

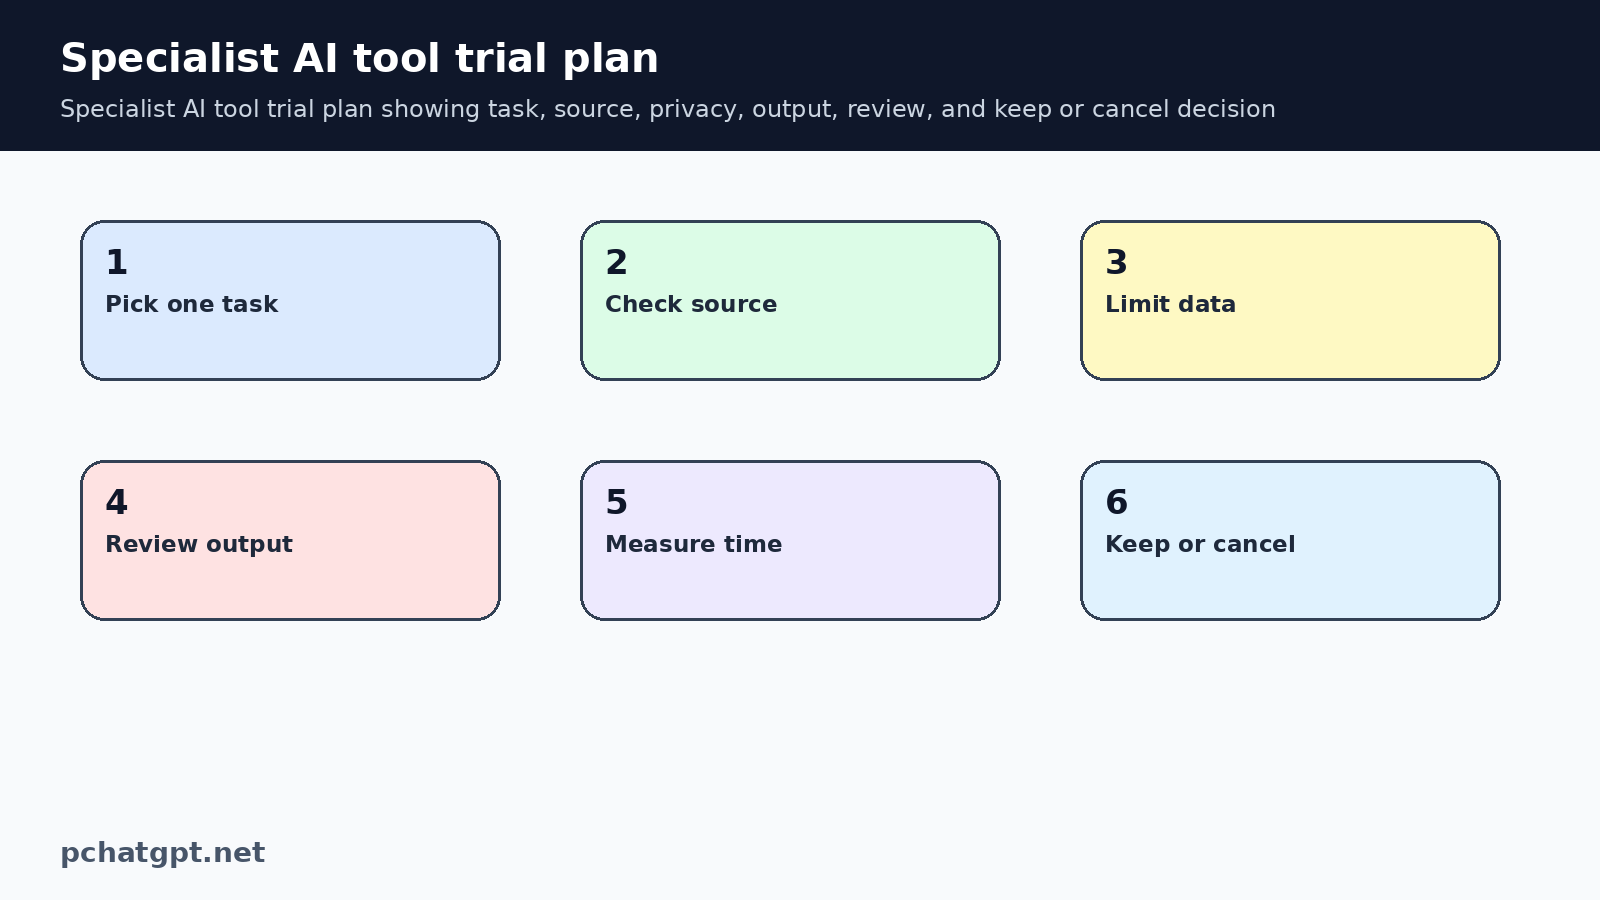
Specialist AI tool trial plan showing task, source, privacy, output, review, and keep or cancel decision

Brain.fm presents itself as functional music for focus, relaxation, meditation, and sleep. That makes it different from writing assistants. It does not draft a document or summarize a PDF. It tries to shape the work environment so the person can stay with the task longer.

The right test is simple. Use it during a work block that normally gets interrupted, then compare your attention with a normal session. If the main problem is distraction, a focus tool may help more than another chatbot. If the problem is unclear thinking, weak research, or missing structure, ChatGPT or a writing tool may be a better starting point.

Beautiful.ai for slide layout work

Beautiful.ai is built around presentation creation. That matters because slide work is partly writing and partly layout. A chatbot can draft an outline, but it does not live inside the slide design process. A presentation tool can help with spacing, hierarchy, templates, and visual consistency.

The best use case is repeated slide work: team updates, sales decks, investor summaries, teaching material, or internal explainers. The user should still own the message and evidence. Treat the tool as a design and structure assistant, not as a substitute for knowing the audience.

Recall for research capture

Recall focuses on saving and summarizing online material. That is useful for people who collect articles, videos, PDFs, and web pages but lose track of why they saved them. The value is not only summary. It is having a research trail that can be searched later.

Use it when the problem is scattered research. A marketer tracking competitors, a student reading sources, or a creator collecting examples may benefit from capture first workflows. The caution is important: open the original source before quoting facts, prices, legal claims, health information, or product promises.

Maple for household coordination

Workflow grid for focus music, presentations, research capture, family planning, and personal knowledge tools

Maple is aimed at family and household planning. That category is easy to overlook because AI productivity is often discussed as office work. Families also coordinate meals, chores, appointments, school tasks, lists, and routines. A shared planning tool may help if it reduces repeated reminders.

The test should be ordinary. Use it for dinners, a grocery list, chores, and one event. At the end of the week, ask whether there were fewer duplicate messages and fewer last minute decisions. If the answer is no, keep the existing calendar and use ChatGPT only for occasional planning prompts.

Mem for personal knowledge

Mem is a note and personal knowledge product with AI features around saved information. This is useful for people who already have notes, decisions, project records, meeting takeaways, and half written ideas. The problem is not generating more content. The problem is finding the right context later.

A personal knowledge tool works best when the user has a review habit. If everything is saved and nothing is cleaned, the system becomes another archive. Test it with one project folder or one topic first. Ask whether it helps retrieve your own context faster than search, folders, or a regular notes app.

How to compare these tools fairly

These products should not be compared as if they do the same job. A focus music tool, a slide builder, a research capture app, a household planner, and a knowledge base solve different problems. A fair comparison asks whether each tool removes a specific step from its own workflow.

Keep the test modest. Do not import your whole life, team, or research archive on day one. Start with safe data, use one repeated task, and decide whether the tool earned a longer trial. If the product cannot show value in a small controlled test, it probably will not become useful just because the setup gets larger.

Where ChatGPT still fits

ChatGPT remains useful around these specialist tools. It can help write the brief for a slide deck, form questions before research, turn household preferences into a meal planning prompt, or summarize notes before they go into a knowledge system. The specialist tool then handles the narrower workflow.

This split keeps the tool stack cleaner. Use a general assistant for flexible thinking and a specialist app when the workflow itself matters. If both tools are doing the same job, keep the one that gives better review, privacy, and integration for the task.

Maintenance notes for editors

Keep this page tied to lesser known AI tools, not to a broad claim that every AI product is useful. Future updates should start by opening the official pages already cited, checking the product surface named in the section, and removing any claim that no longer has a visible source. If a new feature sounds interesting but the source does not describe it clearly, leave it out until it can be verified.

For lesser known AI tools, the article should also keep its old URL and search intent. Do not turn this post into a news reaction or a general opinion piece during routine cleanup. The useful version of the page explains what a reader can check today, how to limit risk, and when another tool or human review is needed. That practical boundary is what makes the refreshed article more useful than the previous boilerplate.

When adding examples about lesser known AI tools later, avoid invented performance numbers, launch dates, user counts, prices, benchmarks, or regional availability. Those details can change and they need a direct source. A plain limitation is better than a confident sentence that cannot be checked. Readers trust the page more when it says less and supports the claims it keeps.

Internal links for lesser known AI tools should stay close to the reader journey. One link can help compare related AI tools. Another can point to safety, governance, memory, or workflow guidance. Do not add unrelated links only to raise a count. The link should answer the next question a careful reader is likely to ask.

The diagrams in this lesser known AI tools page should teach a process. If the images are replaced later, keep the same standard: clear labels, useful ALT text, strong contrast, and a relationship to the surrounding paragraph. Decorative robot art may look fine, but it does not help a reader make a better decision.

Before saving a future lesser known AI tools edit, read the page aloud once. Remove phrases that sound like a sales brochure, especially broad claims about transformation, productivity, or innovation. Keep the sentences concrete. Name the setting, workflow, source, review step, or risk. That style is better for readers and safer for an AdSense quality review.

If a future editor wants to add comparisons around lesser known AI tools, require the same evidence standard for every product mentioned. Compare what the product page says, what the account controls allow, and what a user can verify without private access. Do not rank tools by vibes, screenshots, or affiliate style language.

Keep the lesser known AI tools FAQ narrow. Each question should resolve one practical concern: tool choice, privacy, review, cost, or policy. If an answer repeats a section above, rewrite it into a shorter decision rule. A concise FAQ helps searchers who scan, and it prevents the page from turning into padded text.

The final live check for lesser known AI tools should use the public page, not only the editor. Confirm that the canonical still points to the preserved URL, the page remains indexable, both body images load, and the article has no old repeated paragraph from the earlier corpus audit. Save that proof beside this batch so the next remediation run can trust the result.

If the article becomes too broad, split the extra idea into another guide and link to it only when it helps the reader. This keeps lesser known AI tools clear, avoids topical overlap with nearby posts, and gives the corpus a cleaner set of search intents.

A useful lesser known AI tools update should include one practical boundary near every major recommendation. Say what the tool can help with, then say what still needs checking by the reader. This rhythm prevents unsupported promises and makes the guidance easier to trust when product pages, plans, or controls change later.

For lesser known AI tools corpus cleanup, the most important signal is not raw length. Length only helps when it adds original structure, source based limits, and task specific advice. If a new paragraph could be copied into another AI article without changing meaning, rewrite it before publishing.

Keep one small lesser known AI tools reader scenario in mind while editing. A person has landed on this URL because they need to choose, control, or explain something today. The article should help that person make a safer next move without asking them to trust a vague AI trend summary.

Official sources used

Related guides

FAQ

Are lesser known AI tools better than ChatGPT?

Not automatically. They are better only when they solve a narrow workflow more smoothly than a general assistant. ChatGPT is still a strong baseline for broad drafting, planning, and explanation.

How long should I test a specialist AI app?

A one week trial is usually enough for a repeated personal workflow. For team or business use, test with safe data first and review privacy, export, account ownership, and approval rules.

Should I use all five tools together?

No. The safer approach is to test one tool for one job. Keep it only if it reduces effort after review and does not create unnecessary data or subscription risk.

What should I check before using a new AI app?

Check the official product page, privacy information, export options, cost, and whether the app works where the task already happens. Avoid sensitive data until the use is approved.

Best AI tools guide: choose apps by workflow, privacy, and review effort

0

A best AI tools guide should not read like a shopping list. Most readers already know the famous names. The harder problem is deciding whether a new app deserves a place in a real workflow, or whether it only adds another login, another bill, and another place where data can leak.

This refresh keeps the old search intent but changes the article into a decision guide. It compares general assistants, specialist apps, privacy controls, evidence habits, team use, and cost discipline. The aim is practical: choose fewer tools, use them better, and review their output before it reaches work that matters.

Start with the job the user repeats

The first question is not which tool is popular. The first question is what job repeats often enough to deserve help. A student may need study notes. A marketer may need first drafts and campaign variants. A developer may need code review inside an editor. A manager may need meeting summaries. Those jobs are different, so one ranking cannot settle them.

Write the job as a sentence before testing a tool. For example: I need to turn sales call notes into follow up emails, or I need to compare source documents before writing a report. A clear job makes the test honest. If the app does not remove steps from that job, it is probably not the right tool.

Use ChatGPT as the baseline, not the enemy

AI tool selection scorecard covering job fit, data risk, review effort, integration, and cost

ChatGPT is a useful baseline because it handles broad conversation, drafting, file work, images, learning support, and general reasoning in one place. OpenAI describes ChatGPT as a product surface across web, desktop, and mobile, with plan differences listed on its pricing page. That breadth is why many users should test ChatGPT first before adding a specialist app.

A specialist tool has to earn its place by doing something more specific. It might live inside an IDE, capture meeting transcripts, keep a searchable research library, or build slides with less formatting work. If the specialist app only wraps a chat box around the same task, the extra subscription may not be worth it.

Judge privacy before clever features

Any AI app can look impressive in a demo. The privacy check is less exciting, but it matters more for work. OpenAI publishes data controls for ChatGPT, and other vendors should provide comparable information about retention, training, export, deletion, and account controls. If those details are hard to find, treat that as part of the evaluation.

A simple rule helps: do not put sensitive data into a tool until you know how the tool handles it. Sensitive data includes customer records, employee information, contracts, private financial material, source code, medical details, school records, API keys, and unpublished business plans. The more sensitive the input, the more you should prefer approved accounts, admin controls, and written policy.

Separate creative work from factual work

AI tools can help brainstorm, rephrase, outline, classify, and summarize. Factual work needs another layer. A research answer, product comparison, legal summary, health explanation, or technical instruction should point back to a source the reader can check. Without that source trail, a polished answer is still only an answer that sounds confident.

This is where the best tool depends on the task. A general assistant can help form questions and compare documents. A research tool may be better when source capture is the main need. A writing tool may be better when grammar and style inside email are the pain point. Use the smallest tool that gives enough evidence for the job.

Measure review effort, not only output speed

Map comparing general AI assistants with specialist AI tools for writing, research, coding, meetings, and design

Fast output is useful only if the review stays manageable. If an app generates ten pages that take an hour to fact check, it may not save time. If another app produces a smaller draft with clearer sources and fewer assumptions, that slower looking workflow may be better.

During a trial, track three numbers: time to first usable output, time spent fixing mistakes, and the number of steps removed from the workflow. This is more useful than asking whether the answer looked smart. A good AI tool should reduce total effort after review, not only create more text.

Control subscription sprawl

AI subscriptions multiply quietly. One general assistant, one meeting tool, one design tool, one research tool, and one automation tool can become a recurring cost problem for a small team. The OpenAI pricing page is useful as a baseline because it makes plan comparison visible, but each added app needs its own reason.

Use a monthly cleanup rule. Keep a tool if it supports a repeated job, protects data well enough for the task, and saves time after review. Cancel or pause tools used only for experiments. If a free or included product already solves the job, do not pay for a separate app just because a list called it innovative.

Build a small team policy early

Teams need a short approved list. It should name the tools people can use, the data they may enter, the tasks that need human review, and the person responsible for each account. NIST AI risk guidance is useful here because it frames risk as something teams should map, measure, manage, and govern.

The policy can be plain. Public marketing drafts may be allowed in one tool. Customer data may require a business account or may be prohibited. Code changes may require review before merge. Meeting transcripts may need consent. Clear rules reduce shadow AI because employees know what is safe without guessing.

A practical comparison workflow

Test tools with the same real task. Give each candidate the same brief, the same allowed data, and the same success criteria. Record what worked, what failed, what needed checking, and what would happen if the tool disappeared. Portability matters because workflows should not trap important knowledge in one vendor.

At the end, choose the tool that fits the job with the least new risk. That may be ChatGPT alone. It may be a specialist app. It may be no AI tool at all for that task. A good best AI tools guide should leave room for that answer.

Maintenance notes for editors

Keep this page tied to best AI tools guide, not to a broad claim that every AI product is useful. Future updates should start by opening the official pages already cited, checking the product surface named in the section, and removing any claim that no longer has a visible source. If a new feature sounds interesting but the source does not describe it clearly, leave it out until it can be verified.

For best AI tools guide, the article should also keep its old URL and search intent. Do not turn this post into a news reaction or a general opinion piece during routine cleanup. The useful version of the page explains what a reader can check today, how to limit risk, and when another tool or human review is needed. That practical boundary is what makes the refreshed article more useful than the previous boilerplate.

When adding examples about best AI tools guide later, avoid invented performance numbers, launch dates, user counts, prices, benchmarks, or regional availability. Those details can change and they need a direct source. A plain limitation is better than a confident sentence that cannot be checked. Readers trust the page more when it says less and supports the claims it keeps.

Internal links for best AI tools guide should stay close to the reader journey. One link can help compare related AI tools. Another can point to safety, governance, memory, or workflow guidance. Do not add unrelated links only to raise a count. The link should answer the next question a careful reader is likely to ask.

The diagrams in this best AI tools guide page should teach a process. If the images are replaced later, keep the same standard: clear labels, useful ALT text, strong contrast, and a relationship to the surrounding paragraph. Decorative robot art may look fine, but it does not help a reader make a better decision.

Before saving a future best AI tools guide edit, read the page aloud once. Remove phrases that sound like a sales brochure, especially broad claims about transformation, productivity, or innovation. Keep the sentences concrete. Name the setting, workflow, source, review step, or risk. That style is better for readers and safer for an AdSense quality review.

If a future editor wants to add comparisons around best AI tools guide, require the same evidence standard for every product mentioned. Compare what the product page says, what the account controls allow, and what a user can verify without private access. Do not rank tools by vibes, screenshots, or affiliate style language.

Keep the best AI tools guide FAQ narrow. Each question should resolve one practical concern: tool choice, privacy, review, cost, or policy. If an answer repeats a section above, rewrite it into a shorter decision rule. A concise FAQ helps searchers who scan, and it prevents the page from turning into padded text.

The final live check for best AI tools guide should use the public page, not only the editor. Confirm that the canonical still points to the preserved URL, the page remains indexable, both body images load, and the article has no old repeated paragraph from the earlier corpus audit. Save that proof beside this batch so the next remediation run can trust the result.

If the article becomes too broad, split the extra idea into another guide and link to it only when it helps the reader. This keeps best AI tools guide clear, avoids topical overlap with nearby posts, and gives the corpus a cleaner set of search intents.

A useful best AI tools guide update should include one practical boundary near every major recommendation. Say what the tool can help with, then say what still needs checking by the reader. This rhythm prevents unsupported promises and makes the guidance easier to trust when product pages, plans, or controls change later.

For best AI tools guide corpus cleanup, the most important signal is not raw length. Length only helps when it adds original structure, source based limits, and task specific advice. If a new paragraph could be copied into another AI article without changing meaning, rewrite it before publishing.

Keep one small best AI tools guide reader scenario in mind while editing. A person has landed on this URL because they need to choose, control, or explain something today. The article should help that person make a safer next move without asking them to trust a vague AI trend summary.

Official sources used

Related guides

FAQ

Should I use ChatGPT or a specialist AI tool?

Use ChatGPT when the task is broad, conversational, or exploratory. Use a specialist tool when it works inside the place where the job already happens and removes steps that ChatGPT cannot remove by itself.

How do I compare AI tools without wasting money?

Run a short trial with one repeated task. Measure time saved after review, data controls, source visibility, integration, and whether the tool replaces a real workflow rather than adding another inbox.

Are free AI tools safe for work data?

Do not assume that. Check the vendor privacy terms and data controls first, and avoid sensitive customer, employee, financial, legal, medical, or source code data unless the tool is approved for that use.

What is the biggest mistake in choosing AI apps?

The biggest mistake is choosing from hype instead of workflow fit. A tool is useful when it helps a repeated task, keeps review manageable, and handles data in a way that matches the risk.

ChatGPT for Excel and Google Sheets: A Practical Spreadsheet Workflow

0

ChatGPT for Excel and Google Sheets matters because spreadsheets are where many people already do their work. Budgets, trackers, forecasts, KPI reports, lists, models, and messy exported data often live in Excel or Google Sheets long before they become a polished dashboard or document. OpenAI’s spreadsheet experience puts ChatGPT in a sidebar next to that work, so the task can start from the workbook instead of a blank chat window.

The useful way to read this product is not as a magic spreadsheet button. OpenAI describes it as a spreadsheet-native AI experience for building, updating, and understanding spreadsheets. That wording is important. It can help with formulas, workbook questions, labels, formatting, assumptions, charts, scenarios, and summaries, but the user still has to choose the scope and check the result. A spreadsheet can drive money, payroll, grades, customer lists, or operational decisions. Polished output is not the same as verified output.

This guide explains what OpenAI officially says ChatGPT for Excel and Google Sheets can do, how setup works, where the Excel and Sheets experiences differ, how Skills and apps fit in, and how to use the feature without turning a useful assistant into an unchecked automation layer.

What ChatGPT for Excel and Google Sheets is

OpenAI’s official help article on ChatGPT for Excel and Google Sheets says the feature lives in a sidebar inside Excel and Google Sheets. It is designed to help users build, update, and explain spreadsheets directly, including large files with multiple tabs, formulas, references, and assumptions.

The Excel and Google Sheets versions are separate experiences, but OpenAI says they support similar workflows. You can create a spreadsheet from scratch, ask questions about an existing one, and make updates using natural language. That means the strongest use cases are not one-off formula tricks. The stronger use case is guided spreadsheet work where you ask for a plan, approve the scope, let ChatGPT work on a defined part of the file, and then review the changed cells.

OpenAI also says spreadsheet chats are separate from the main ChatGPT chat history. They do not sync with your ordinary chats, and spreadsheet chats have limited memory support. Treat that as a design boundary. If you want a consistent process, you need to put the rules in the prompt, a saved workflow, a Skill, or your team instructions rather than assuming the sidebar remembers everything from another ChatGPT conversation.

Who can use it

OpenAI lists global availability for Free, Go, Plus, Pro, Business, Enterprise, ChatGPT Edu, and K-12 users. The usage terms differ by plan. Free and Go include limited usage access. Plus and Pro access is subject to the plan’s agentic usage limit. Business, Enterprise, Edu, and K-12 customers had a free preview through June 2, 2026, after which usage follows plan credits and usage terms.

That plan language should keep teams from making broad assumptions. A small personal file may be a light task. A large workbook with many tabs, multi-step edits, and analysis can use more of the agentic usage limit. Business and Enterprise admins can monitor usage and purchase additional credits, according to OpenAI’s help page. If you manage a team, usage policy belongs in the rollout plan, not in an afterthought once people have already started relying on the add-in.

How Excel setup works

For Excel, OpenAI directs users to the Microsoft Marketplace listing for ChatGPT. The basic path is to open Excel on desktop or web, go to Home, choose Add-ins, search for ChatGPT, add it, open ChatGPT from the ribbon, and sign in with a supported ChatGPT account.

Organizations that cannot access the Microsoft Store for the add-in can have a Microsoft 365 admin deploy it internally using OpenAI’s manifest XML file. The admin flow uses the Microsoft 365 admin center, Integrated apps, Deploy Add-in, and Upload custom apps. That deployment detail is useful for companies where end users are not allowed to install marketplace add-ins themselves.

Excel also has a separate Codex workflow in the ChatGPT desktop app. OpenAI says users can use Codex in the ChatGPT desktop app to work directly with an open Microsoft Excel workbook through the ChatGPT for Excel add-in. In that workflow, Codex can inspect and update sheets, formulas, values, formatting, and charts. It can also use code and local files provided as part of the task. OpenAI states that this direct workbook workflow is currently available for Microsoft Excel only.

Four step ChatGPT spreadsheet workflow for scoping, planning, editing, and reviewing Excel or Google Sheets tasks
A safe spreadsheet workflow starts with scope, asks for a plan, applies focused edits, and ends with human review.

How Google Sheets setup works

For Google Sheets, OpenAI points users to the Google Workspace Marketplace listing for ChatGPT. The setup is to install ChatGPT from the marketplace, open Google Sheets, launch ChatGPT from the Extensions menu, and sign in with a supported ChatGPT account.

If an organization uses role based access control, an admin may need to enable the add-in. OpenAI says the setting is under Workspace settings, Permissions and roles, ChatGPT for Excel and Google Sheets, then Enable ChatGPT for Excel and Sheets. OpenAI notes that this applies to both Excel and Google Sheets. That matters for administrators because the permission is not only a Google Sheets switch.

The practical difference is simple: Excel currently has the extra Codex desktop workflow described above, while Google Sheets uses the spreadsheet sidebar experience. Do not promise the same direct desktop control for Sheets unless OpenAI later documents it. For now, explain the difference plainly and build workflows around the supported surface.

What it can do well

OpenAI’s examples are concrete. ChatGPT for Excel and Google Sheets can help build formatted budgets, explain an error in a specific cell, summarize trends across tabs, clean inconsistent labels, remove duplicates, update a table with new assumptions, and create scenario tabs. These are normal spreadsheet jobs, not abstract AI demos.

The best results come when you narrow the request. Instead of saying, “fix this workbook,” ask ChatGPT to inspect a specific tab, identify likely formula issues, propose a plan, and wait before editing. Instead of asking it to “make this better,” say which columns to preserve, which labels can change, which formatting should stay untouched, and what output you expect at the end.

Use the feature for work that benefits from context. Good examples include explaining a formula chain, finding inconsistent categories, summarizing changes between tabs, creating a model template, building a scenario table, and turning raw rows into a cleaner report. Weak examples include asking it to make financial, legal, or tax decisions for you. OpenAI warns that ChatGPT is not a financial, legal, or tax advisor and that outputs should not be considered advice.

Where Skills and apps fit

OpenAI says ChatGPT for Excel and Google Sheets supports Skills and apps. The OpenAI Skills help article describes Skills as reusable, shareable workflows that tell ChatGPT how to do a specific task more consistently. In a spreadsheet setting, that could mean a Skill for monthly budget cleanup, corporate finance formatting, KPI report review, or scenario analysis.

Skills matter because repeated spreadsheet work often has house rules. A finance team may want a specific layout, color convention, review checklist, and naming pattern. A support operations team may want exported tickets cleaned in the same way every week. A founder may want a lightweight investor update template from the same tracker each month. A Skill can carry those instructions so users do not rebuild the same prompt every time.

Apps are different. OpenAI says apps let ChatGPT for Excel and Google Sheets work with connected data sources so spreadsheet work can be grounded in the right context. Availability depends on the ChatGPT account, workspace admin settings, user permissions, and data source entitlements. If an app is missing, users should check whether it has been enabled by the workspace admin.

A practical prompt pattern

Start with a small brief. Name the workbook area, the task, the guardrails, and the review requirement. For example:

Review the Sales Summary tab only. Do not change formatting. Check formulas in columns E through H, explain any likely errors, and propose a fix list before making changes. After I approve the plan, update only the cells we agree on and summarize every changed cell.

That prompt works because it separates inspection from editing. It also tells ChatGPT what not to touch. The review step is not bureaucracy. It is how you prevent a helpful assistant from changing a workbook in a way that looks neat but breaks a later report.

For broader ChatGPT workflows, pair this spreadsheet process with the staged prompting approach in ChatGPT How-To Guide 2026: Practical Workflows for Research, Writing, and Automation. If the spreadsheet task becomes part of a writing or reporting workflow, also review How to Use ChatGPT to Write Without Cheating or Getting Flagged, especially for disclosure, source checking, and final human editing.

Review changed cells before relying on output

OpenAI’s limitation section is direct: outputs may be incomplete or incorrect, and users should review formulas, calculations, citations, and changed cells before sharing or relying on them. For important work, OpenAI recommends duplicating the file first so you can revert if needed.

That advice should become a default habit. Duplicate the workbook before large edits. Ask for a plan before changes. Make ChatGPT list modified tabs, ranges, formulas, assumptions, and citations after the edit. Then check the workbook manually. If the spreadsheet supports decisions about money, customers, grades, contracts, operations, or compliance, have a second person review the output before it leaves the team.

This is also where managers should decide which tasks are allowed. Cleaning labels in a copy of a tracker is low risk. Updating a financial model that will be sent to leadership is higher risk. Pulling information from connected apps or internal files may be useful, but it also raises permission and data handling questions.

Capability map showing ChatGPT spreadsheet tasks such as build, explain, update, summarize, ground, and limit
ChatGPT can help with spreadsheet building, explanation, updates, summaries, and grounded context, but users still need clear limits.

Privacy, security, and admin controls

OpenAI says ChatGPT for Excel runs in Microsoft Excel and ChatGPT for Google Sheets runs in Google Sheets. Your use of those products is governed by your agreements with Microsoft or Google. OpenAI also notes that Microsoft may have the ability to read the content of your Excel workbook, attachments, and prompts as part of Microsoft’s Add-in Marketplace terms.

OpenAI says ChatGPT processes the prompt, attachments, and relevant spreadsheet context so it can update the workbook and send analysis. It also says data is stored locally in the product, users can delete or download data in Settings, and some data logs may be stored with OpenAI for 30 days for safety and integrity purposes.

For enterprise users, OpenAI lists workspace level controls including data and inference residency where available, Enterprise Key Management, and role based access controls. It also says prompts and responses are available in the Compliance API. These controls do not remove the need for a local policy. They give administrators tools to decide who can use the add-in, which connected apps are allowed, how logs are reviewed, and which spreadsheets should stay outside the workflow.

Common mistakes to avoid

The first mistake is asking ChatGPT to repair a whole workbook without defining the scope. That invites accidental edits. The second mistake is skipping the plan step. If ChatGPT cannot explain which tabs and ranges it intends to touch, the task is not ready for execution.

The third mistake is treating spreadsheet output as advice. A model may help find a formula issue or build a scenario table, but it is not your accountant, lawyer, tax advisor, or compliance officer. The fourth mistake is pasting sensitive data into an account or workspace that has not been approved for that data. The fifth mistake is assuming spreadsheet chats have the same context as your main ChatGPT history. OpenAI says they are separate experiences.

A better rule is simple: use ChatGPT to speed up structure, inspection, cleanup, explanation, and draft analysis. Keep humans responsible for final decisions, important calculations, data classification, and external sharing.

Best workflow for teams

Teams should treat ChatGPT for Excel and Google Sheets as a workflow rollout rather than a casual add-in. Start with two or three approved use cases, such as cleaning exported CRM data, reviewing KPI sheets, or creating monthly budget templates. Write a prompt pattern for each use case. Include what users may upload, what they must not upload, whether connected apps are allowed, and when a second review is required.

Then measure the workflow. Track whether users save time, whether reviewers find fewer formula mistakes, whether reports become clearer, and whether any data handling concerns appear. If the tool creates cleaner work but increases review time, adjust the prompts. If people ignore the rules, simplify them. If a Skill captures the process well, share it with the team so the workflow becomes repeatable.

For individuals, the same idea applies at smaller scale. Keep a short note with your best spreadsheet prompts. Separate formula help from data cleanup, scenario planning, and report writing. Save the prompts that produce reliable results, and delete the ones that tempt you to skip review.

Bottom line

ChatGPT for Excel and Google Sheets is useful because it meets spreadsheet users where they already work. The feature can help build, explain, update, and summarize workbook content. Excel users also have a Codex desktop workflow for open Microsoft Excel workbooks, while Google Sheets users work through the Sheets extension experience. Skills and apps can make repeated workflows more consistent and better grounded.

The value comes from discipline. Define the range. Ask for a plan. Preserve what should not change. Duplicate important files. Review formulas, citations, assumptions, and changed cells. Used that way, ChatGPT becomes a practical spreadsheet assistant rather than a risky shortcut.

FAQ

Is ChatGPT for Excel and Google Sheets available to free users?

Yes. OpenAI says the feature is available globally to Free, Go, Plus, Pro, Business, Enterprise, ChatGPT Edu, and K-12 users. Free and Go include limited usage access, while other plans follow their own usage limits and credit terms.

Can ChatGPT directly control Google Sheets through Codex like Excel?

OpenAI’s documented Codex desktop workflow is currently for Microsoft Excel only. Google Sheets users can use the ChatGPT extension experience inside Sheets, but the same direct Excel workbook control should not be assumed for Sheets unless OpenAI documents it.

Should I let ChatGPT edit an important workbook without review?

No. OpenAI says outputs may be incomplete or incorrect and recommends reviewing formulas, calculations, citations, and changed cells before sharing or relying on them. For important work, duplicate the file first so you can revert if needed.

What is the best first prompt to try?

Ask for a plan before edits. A safe starter prompt is: “Review this tab only, do not change formatting, identify formula or data quality issues, and list the exact ranges you would update before making any changes.”

ChatGPT Futures Class of 2026: What OpenAI Announced

0

ChatGPT Futures Class of 2026 is a real OpenAI program, not a forecast or an unofficial label. OpenAI announced the inaugural group on May 6, 2026, recognizing 26 students and young builders from more than 20 universities and institutions. The company said each member would receive a $10,000 grant to continue their work and access to its frontier models.

That timeline is important because the title can sound as if it predicts a graduating class that has not yet arrived. It does not. OpenAI published the announcement during the 2026 graduation season and used “Class of 2026” for the generation being recognized. OpenAI described this cohort as the first to begin and finish college with ChatGPT in the world around them. Students who entered campus in fall 2022 saw ChatGPT become publicly available later that year, then watched generative AI move rapidly into study, research, coding, design, and work.

The useful question is not whether 26 people can represent every student. They cannot. Nor does an awards announcement prove that AI improves education. The better question is what practices these examples make visible. The official announcement points to students building study tools, translating mental health resources, advancing scientific research, creating accessibility tools, and turning side projects into organizations. Those examples suggest a practical model for student AI work: find a meaningful problem, use AI to lower the cost of experimenting, and keep human judgment responsible for the result.

What OpenAI actually announced

OpenAI called ChatGPT Futures an inaugural recognition program for students and young builders using AI in thoughtful, ambitious, and human-centered ways. Its official May 6 announcement provides four concrete facts that anchor this article:

  • The group includes 26 students and young builders.
  • The honorees represent more than 20 universities and institutions.
  • Each class member receives a $10,000 grant to continue advancing their work.
  • Each member receives access to OpenAI frontier models.

OpenAI also framed the cohort as creators, explorers, and advocates rather than members of one technical discipline. That distinction matters. A student builder might write software, conduct research, organize a community, create an accessibility resource, or connect existing tools in a useful way. “Builder” describes an approach to problems, not a degree title.

This is still a company announcement about a program the company created. Readers should not treat its selected stories as a controlled study, an independent ranking of young innovators, or evidence that every AI-assisted project succeeds. The grant amount and access benefit are facts reported by OpenAI. Broader lessons about education and responsible building are interpretations that should be tested against real classrooms, student outcomes, and institutional policies.

Timeline showing students entering college in fall 2022, ChatGPT Study Mode launching in July 2025, and OpenAI announcing the ChatGPT Futures Class of 2026 on May 6, 2026
“Class of 2026” refers to the graduating generation OpenAI recognized in a dated May 2026 announcement. It is not a prediction about an unknown future cohort.

Why the 2022 to 2026 timeline matters

A graduating student in 2026 experienced unusually fast change during a normal four-year degree. At the beginning, generative AI was not yet an ordinary part of campus life. By the end, students and faculty were debating acceptable use, redesigning assignments, testing tutoring workflows, and deciding which information could safely enter an AI system.

That does not mean every member of the graduating class used ChatGPT, or that they all had equal access. It means this generation had to develop norms while the technology was changing. Students often faced a patchwork of course rules. One professor might invite AI-assisted brainstorming, another might allow grammar help with disclosure, and a third might prohibit generative tools entirely. Responsible work therefore begins with permission, not a clever prompt.

The timeline also helps separate three kinds of activity that are often mixed together:

  • Learning with AI: asking for explanations, practice questions, feedback, or alternative examples while still doing the intellectual work.
  • Building with AI: using models to help research, code, design, translate, test, or communicate a project.
  • Submitting AI output: presenting generated material as original work when the relevant rules require independent authorship or disclosure.

These are not ethically equivalent. A student can use the same tool to deepen understanding or to avoid it. Our guide to using ChatGPT for writing without cheating explains the practical difference through permission, verification, disclosure, and authorship. The central test is simple: can the student explain the work, defend the choices, identify the sources, and comply with the rules that govern the assignment?

From AI literacy to student agency

OpenAI argues that education should go beyond teaching how AI works or how to prompt. Its Futures announcement emphasizes agency: the ability to notice a problem and turn an idea into something tangible. That framing is useful when it is paired with accountability.

AI literacy remains necessary. Students need to understand that a confident answer can be false, that generated citations may not exist, and that uploaded information can have privacy or intellectual property implications. Yet literacy alone can become passive. A student may know the vocabulary of hallucinations, bias, and context windows without ever learning how to define a useful problem, interview a user, test a prototype, or revise after failure.

Agency adds action. It asks the student to make choices under uncertainty and see how those choices affect other people. A useful campus project might begin with a narrow need: helping classmates navigate a complex library collection, making a lab protocol easier to understand, or creating a study aid for a course. The first version does not need to become a startup. It needs to be small enough to test and honest enough to learn from.

AI can reduce friction in that process. It can help compare approaches, explain unfamiliar code, draft interview questions, suggest edge cases, or turn rough notes into a test plan. None of those contributions removes the need for subject expertise. In fact, faster production creates more things to inspect. The student must decide which problem deserves attention, what evidence is trustworthy, who might be excluded, and when the system is not ready to use.

A responsible student builder workflow

The strongest lesson to take from ChatGPT Futures is not “move fast at any cost.” It is that a student can start before having perfect credentials, while still working carefully. The following five-step loop turns that idea into a repeatable practice.

  1. Define a real need. Name the person affected, the task they struggle with, and the outcome that would help. “Build an AI study app” is vague. “Help first-year biology students practice identifying where their reasoning breaks down” is testable.
  2. Investigate before generating. Talk to intended users, review course or institutional rules, gather authoritative sources, and identify sensitive data. Do not paste student records, private health information, unpublished research, or credentials into a tool without explicit authorization and suitable protections.
  3. Prototype the smallest useful version. Use AI where it reduces mechanical work, but keep the prototype narrow. Ask for multiple approaches, assumptions, and failure cases. Preserve source material separately so generated content can be compared with evidence.
  4. Evaluate with people and examples. Test ordinary cases and edge cases. Check factual accuracy, accessibility, fairness, privacy, and usability. If an output could influence health, safety, grades, employment, or money, involve qualified reviewers and do not let the prototype make unsupervised decisions.
  5. Document and iterate. Record what the model did, which sources were used, what humans reviewed, known limitations, and changes between versions. A project log makes learning visible and prevents a polished demo from hiding unresolved risks.
Five-step responsible student builder loop: define, investigate, prototype, evaluate, and document, with human review throughout
A useful student AI project cycles through evidence and review. Human responsibility does not disappear when prototyping gets faster.

This loop works for a research assistant, accessibility prototype, campus service, study resource, or early business idea. For longer work, a dedicated workspace can reduce confusion. The ChatGPT Projects guide shows how to separate shared sources, instructions, and task-specific chats. Organization is not proof of accuracy, but it makes review and provenance easier.

Learning should remain active

Student building depends on learning, and learning weakens when the model quietly does every difficult step. OpenAI’s official Study Mode announcement describes a different interaction pattern: guiding questions, scaffolded explanations, knowledge checks, self-reflection, and feedback. It was introduced in July 2025 as a way to help students work through a problem rather than simply receive an answer.

That design points to a useful habit even outside Study Mode. Ask the AI to reveal less, not more. A student can request one hint at a time, attempt a solution before seeing an example, explain a concept in their own words, or ask the system to challenge an assumption. Afterward, the student should close the chat and reproduce the reasoning independently. If the understanding vanishes when the conversation is hidden, the work is not finished.

OpenAI also acknowledged that Study Mode could behave inconsistently and make mistakes. That caveat applies broadly. A conversational style can feel personal and authoritative even when the underlying content is wrong. Verification should match the stakes. A casual brainstorming error may cost minutes. A wrong laboratory instruction, accessibility claim, or mental health recommendation can harm someone.

Good builders therefore design verification into the product rather than adding it after a failure. They link claims to primary material, show uncertainty where it exists, give users a path to report a problem, and establish clear boundaries for what the system cannot do.

What universities and educators can do

Student agency does not require institutions to remove safeguards. It requires clearer conditions for experimentation. Educators can publish assignment-level AI rules, specify acceptable assistance, and ask for process evidence such as notes, drafts, source checks, or reflection. This gives students room to use new tools without forcing them to guess where the boundary lies.

Courses can also assess decisions instead of only polished outputs. A short demo can hide weak reasoning, while a design review exposes it. Ask students why they chose the problem, what alternatives they rejected, where the model failed, whose feedback changed the prototype, and what they would not automate. Those questions reward judgment and make outsourcing the entire task less attractive.

Institutions need suitable technical and governance choices too. OpenAI introduced ChatGPT Edu in May 2024 as a university offering with enterprise-level security, privacy, and administrative controls. That official description does not mean every institution should adopt it, nor does it make all uses automatically compliant. Universities still need procurement review, data classifications, accessibility testing, retention rules, training, and alternatives for students who cannot or do not wish to use a particular tool.

Access is another part of responsibility. A class that requires a paid AI subscription can create an uneven playing field. A project showcase may favor students with stronger networks, more free time, or existing technical confidence. Schools can respond with shared access, mentoring, interdisciplinary teams, small grants, and transparent selection criteria. AI may lower some barriers to prototyping, but it does not erase social and institutional barriers.

How to read the Futures stories critically

The Futures cohort is valuable as a set of examples, not as a complete map of student AI use. Selection programs highlight unusual, visible work. Many worthwhile student contributions are quieter: improving a lab workflow, translating a community document with expert review, helping a club organize accessible events, or creating a small tool that serves one course well.

Readers should also distinguish a project’s mission from evidence of impact. A tool built for accessibility may have an admirable goal, but it still needs testing with the people it intends to serve. A mental health resource may expand access to information, but it requires careful boundaries and qualified oversight. A research prototype may accelerate exploration, but its findings still need reproducible methods and expert scrutiny.

The most credible student builders make those limitations visible. They do not claim that AI alone created the result. They can identify where data came from, explain what was generated, describe who reviewed it, and state what remains uncertain. That is a more durable signal than a dramatic demo.

What the Class of 2026 really reveals

OpenAI’s announcement supports a modest but meaningful conclusion. Students are not merely future users of AI. Some are already deciding which problems to pursue, how tools should fit into human workflows, and which values should guide a project. The important skill is not prompt cleverness. It is the combination of curiosity, domain learning, collaboration, verification, and responsibility.

The Class of 2026 label captures a real historical transition. This graduating generation entered college before ChatGPT became an everyday reference point and left with AI embedded in many conversations about study and work. The 26 honorees are a selected snapshot of that transition, not proof that all students benefited or that every problem is solved.

For a student, the practical invitation is straightforward: choose a problem close enough to understand, start with evidence, build a small test, involve the people affected, and keep a record of what the AI can and cannot do. For educators, the task is to make room for that agency while protecting learning, privacy, access, and academic integrity. Faster tools raise the value of good judgment rather than reducing it.

Frequently asked questions

Is the ChatGPT Futures Class of 2026 an official OpenAI program?

Yes. OpenAI officially announced the inaugural ChatGPT Futures Class of 2026 on May 6, 2026. The announcement says it recognizes 26 students and young builders from more than 20 universities and institutions.

What do members of the ChatGPT Futures Class of 2026 receive?

According to OpenAI, each member receives a $10,000 grant to continue advancing their work and access to OpenAI frontier models. The official post is the source for those benefits.

Does the program prove that ChatGPT improves student learning?

No. It is a recognition program and a collection of selected examples, not a controlled study of learning outcomes. Student projects can offer useful ideas, but claims about educational effectiveness need appropriate evidence.

How can a student use AI without outsourcing the learning?

Start with course rules, attempt the problem, ask for hints or critique, verify claims against primary sources, and reproduce the reasoning without the chat. Document AI assistance when required and keep human review active throughout the project.

Official sources

ChatGPT Mac App Security Update: What OpenAI’s Certificate Rotation Means for Users

0

The ChatGPT Mac app security update was not a routine feature release. OpenAI replaced the certificates used to sign its applications after a compromised TanStack npm package reached two employee devices and exposed limited credential material from internal source code repositories. OpenAI said it found no evidence that customer data, production systems, intellectual property, or published software had been compromised. It still treated the signing material as sensitive and rotated its certificates.

For a Mac user, the practical response is much simpler than the incident report: update OpenAI applications through their built-in updater or an official OpenAI download page. The original notice gave June 12, 2026 as the deadline. OpenAI later amended the notice and extended the migration to June 26, 2026. Both dates have passed, so an old installation should be updated now rather than kept as a working legacy copy.

This guide explains what the incident did and did not establish, why macOS code signing matters, how to update without falling for a fake installer, and what an IT team should check on managed Macs. It relies on OpenAI’s current advisory and Apple’s platform security documentation. It does not assume that every certificate warning comes from this incident, because corporate TLS inspection can create a different kind of certificate error in the ChatGPT app.

What OpenAI reported

OpenAI’s official response to the TanStack npm supply chain attack says the incident began on May 11, 2026 UTC. TanStack, a widely used open source library, was compromised during a broader campaign known as Mini Shai-Hulud. Two OpenAI employee devices in the corporate environment were affected. OpenAI brought in an outside digital forensics and incident response firm, isolated affected systems and identities, revoked sessions, rotated credentials, and temporarily restricted code deployment workflows.

The company said the malware performed credential-focused exfiltration in a limited subset of source code repositories available to those employees. According to the advisory, only limited credential material was successfully removed. The affected repositories included signing certificates for products on several platforms. That exposure prompted OpenAI to re-sign its applications and coordinate with platform providers to prevent new notarizations with previous certificate material.

OpenAI also reported several negative findings that should not be blurred into a broader claim. It found no evidence that user data or OpenAI products were exposed, no evidence that production systems or intellectual property were compromised, and no evidence that malicious software had been signed with an OpenAI certificate. It reviewed notarization activity associated with the earlier certificates and said its published software had not been modified without authorization.

Those statements do not make certificate rotation pointless. Incident response often has to deal with uncertainty. If sensitive material was reachable from an affected environment, replacing it can remove a possible future route for abuse even when investigators find no misuse. The update request was therefore a precaution tied to software identity, not an announcement that the installed ChatGPT app had become malware.

The deadline changed from June 12 to June 26

The OpenAI page still contains parts of its original June 12 wording, including an older heading and FAQ text. At the top of the same page, however, an amendment says the macOS update deadline was extended to June 26, 2026. The amendment is the later instruction and should control how the timeline is read. OpenAI said it had coordinated with Apple, blocked new notarization with the previous certificate, and found no evidence of malicious signing while users completed the move.

This distinction matters because repeating only June 12 now leaves readers with an incomplete version of the notice. The useful current advice is not to argue about which old date applies. If ChatGPT, ChatGPT Classic, Codex, Codex CLI, or Atlas has been sitting on a Mac without updates since that period, move to a current OpenAI release. If the application already updates normally and came from OpenAI, there is no special certificate file for the user to install by hand.

OpenAI’s earlier Axios developer tool compromise advisory describes a separate certificate rotation from April 2026. That event affected a GitHub Actions workflow used in macOS signing. OpenAI said the certificate was probably not exfiltrated but rotated it anyway, with a May 8 deadline. The later TanStack incident required another response. Keeping the two notices separate prevents a confusing timeline in which May 8, June 12, and June 26 appear to describe one unchanged event.

What a code-signing certificate tells macOS

A code signature connects a particular application build to a developer identity and lets the operating system check whether the signed code has changed. Apple’s macOS code-signing documentation explains that apps distributed outside the App Store use an Apple-issued Developer ID certificate and private key. Under the default security settings, those apps also need Apple notarization.

Signing and notarization perform related but different jobs. A developer signs the app. macOS can then verify that the code has not been altered since the developer signed it. Notarization records that Apple received a copy for an automated malware check and found no known malware at that time. A notarization ticket can be stored online or attached to the app without changing the developer’s signature.

Apple’s Gatekeeper documentation describes the checks a Mac applies when software arrives from outside the App Store. Gatekeeper checks that the app came from an identified developer, has appropriate notarization, and was not altered. It also asks for approval the first time downloaded software opens. These checks are why an old or revoked certificate can affect a fresh download or first launch even if the application file itself was once legitimate.

A certificate is not a permanent guarantee that every action inside an app is safe. It is one part of the trust chain. It identifies the signer and helps detect post-signing changes. Users still need a legitimate download source, current software, sensible permissions, and caution around unexpected prompts.

Diagram of the ChatGPT Mac app certificate rotation path from OpenAI signing through Apple notarization and Gatekeeper verification to a current app release.
The update moves users to an OpenAI app signed with current certificate material while macOS checks identity, notarization, and integrity.

Why rotation can require an application update

When a developer replaces a signing certificate, it publishes new application builds signed with the replacement. Existing builds keep the signature they received when they were created. They do not silently acquire the new signature because changing a signed application after release would defeat the integrity check. Users therefore need a newly signed build.

OpenAI said it stopped new notarization with the earlier certificate material. That step reduces the chance that someone could create a new, fraudulent app, sign it with old material, and obtain a fresh notarization that passes default checks. OpenAI then coordinated the full revocation while giving legitimate users time to receive updated builds through normal channels.

Apple explains that it can respond to discovered malware by revoking associated Developer ID certificates, issuing notarization revocation tickets, and updating XProtect signatures. Its macOS malware protection guide also notes that the system checks for revocation information in the background. In this OpenAI case, the company’s stated reason for the rotation was precautionary exposure of signing material, and it reported no malicious OpenAI-signed app. The platform mechanics still explain why old releases can lose support or fail a later trust check.

How to update the ChatGPT Mac app safely

The safest route is the update control inside an app you already installed from OpenAI. If that route is unavailable, type the OpenAI or ChatGPT address yourself and use the official download page. OpenAI’s current macOS download article points users to chatgpt.com/download. The help article says the newer desktop app combines Chat, Work, and Codex. It also says the previous macOS app is now called ChatGPT Classic and remains supported.

Do not fetch an installer from an email attachment, a file-sharing service, a search ad, a direct message, or a site that offers a convenient mirror. The TanStack advisory warns specifically against installers sent through email, messages, ads, file-sharing links, and third-party download pages. A message can copy OpenAI’s logo and wording. The address and delivery path are harder for a fake prompt to imitate when you navigate independently.

  1. Open the installed OpenAI app and accept its normal in-app update if one is offered.
  2. If the updater fails, close the app and visit the official ChatGPT download page in a browser using an address you entered or a saved trusted bookmark.
  3. Download the macOS build offered for your hardware and operating system.
  4. Install the current build without changing macOS security settings or bypassing a Gatekeeper warning.
  5. Launch the app and confirm that it opens normally. Keep the web version available as a temporary fallback if a managed network blocks the desktop client.

The current OpenAI help page lists macOS 14 and either Apple silicon or an Intel processor as the requirements for the new desktop application. That is useful if a very old Mac cannot install the current build. It is not a reason to use an old installer from another site. A user who needs the earlier interface can use the official ChatGPT Classic download linked from OpenAI’s desktop download page, subject to OpenAI’s current support terms.

Do not bypass Gatekeeper to make an old installer work

If macOS blocks a downloaded installer, pause before using “Open Anyway” or disabling security controls. A block can mean the app lacks an acceptable signature, notarization, or current trust status. It can also mean the file was altered or came through an unusual delivery path. The correct first response is to delete the questionable file and download a current copy from OpenAI.

Gatekeeper overrides exist because there are legitimate development and administration cases where a user may need them. They are a poor repair for a consumer app that should already be signed and notarized. OpenAI’s advisory says a fraudulent app using previous material would be blocked by default unless a user explicitly bypassed macOS protections. Overriding the warning removes the exact barrier that the certificate response depends on.

If an organization manages the Mac, contact IT rather than changing system policy. Device management may intentionally prevent overrides. An administrator can confirm the approved package, deployment source, and installed version across the fleet without asking users to weaken local controls.

Decision tree for safely handling a ChatGPT Mac update prompt by preferring the in-app updater, using OpenAI's official download page, and stopping on unexpected Gatekeeper warnings.
A safe update path avoids links delivered through messages and never treats a Gatekeeper bypass as a normal installation step.

A certificate warning may be a network problem instead

Not every certificate message in ChatGPT for macOS points to the 2026 signing-certificate rotation. OpenAI’s network troubleshooting guide describes a “wrong SSL certificate” message caused by SSL inspection or decryption on a network. That is about the certificate presented during a secure network connection, not the Developer ID signature attached to the application bundle.

The symptoms and remedies differ. For the app-signing issue, install a current OpenAI release through an official channel. For a TLS inspection issue, OpenAI recommends upgrading and restarting the app, checking whether the problem follows the company network, and involving the network administrator. It says organizations should avoid SSL inspection for public OpenAI domains when possible. If corporate policy requires inspection, the administrator may need guidance from OpenAI Support.

A quick isolation test can help. If the same current app connects on a trusted personal hotspot but fails on company Wi-Fi, the network path deserves attention. Do not interpret that result as permission to remove company security software yourself. Give IT the error text, the affected network, whether coworkers see it, and whether the web version works.

What users do not need to do

OpenAI’s TanStack FAQ says customer passwords and API keys were not affected, so the advisory did not instruct users to reset them. A password change is appropriate if you reused a password, approved a suspicious login, entered credentials into a fake installer, or saw an account alert. It is not part of the routine certificate migration described by OpenAI.

You also do not need to import a certificate into Keychain Access, download a profile, run a Terminal command from an email, or install a browser extension to “restore trust.” OpenAI’s remediation is delivered as newly signed application builds. An unsolicited guide that asks for an administrator password or tells you to disable Gatekeeper should be treated as suspicious.

Windows and iOS users did not need to perform a special update for this certificate deadline, according to the TanStack response. OpenAI said it was re-signing applications across platforms but identified macOS users as the group that had to take action. Normal operating-system and app updates remain sensible on every platform.

Practical checks for a personal Mac

Start with provenance. Ask where the installed application came from. If you used OpenAI’s site or the app’s own updater, that is a much better starting point than a download directory or software mirror. Then check whether the app updates and launches without a macOS trust override.

Review unexpected files in Downloads, especially disk images or packages named ChatGPT, OpenAI, Codex, or Atlas that arrived through a message. Delete copies you did not request. If you entered your Mac password into a suspicious installer, disconnecting from the network and seeking qualified incident-response help is more appropriate than repeatedly launching the file.

For current product use after the update, PChatGPT’s ChatGPT Mac app guide covers shortcuts, app permissions, voice, and low-risk ways to test integrations. Keep the security question separate from feature setup: a legitimate app can still request permissions that do not make sense for your workflow, so grant access only when a feature needs it.

Checklist for IT and security teams

A managed fleet needs more than a broadcast telling employees to click Update. First, inventory the OpenAI applications in use. The TanStack notice names ChatGPT Desktop, Codex App, Codex CLI, and Atlas. Current packaging has since changed, so inventory both present and legacy names rather than assuming every user has one standard application.

Second, distribute packages from an approved source and document who owns future updates. If users cannot run in-app updates because of permissions or network policy, push the current package through device management. Test on a small group before broad deployment, but do not preserve an old certificate build merely because it still opens on a Mac that launched it before revocation.

Third, monitor help-desk tickets for two separate patterns: macOS trust blocks during installation, and TLS certificate errors during connection. The first points toward package provenance, signing, notarization, or an outdated build. The second may come from an inspecting proxy or secure web gateway. Treating both as “the certificate problem” wastes time and may lead users toward unsafe workarounds.

Finally, remind staff that update deadlines create good phishing material. An attacker does not need a stolen signing key to send a convincing fake notice. Clear internal instructions should name the approved update route and say that support will never send a disk image through chat or ask a user to disable Gatekeeper. For the publication’s broader sourcing and correction standards, see About PChatGPT.

What the incident means for everyday users

The incident was serious because development credentials can sit close to the systems that establish software identity. OpenAI’s public findings were also limited: two corporate devices, a subset of repositories, and limited credential material. The company did not report customer data theft, altered public builds, or malicious software signed with its certificates. Both halves belong in an accurate account.

The user action is deliberately ordinary. Install a current build from the developer, let macOS perform its checks, and avoid unfamiliar download routes. There is no benefit in turning a precautionary update into a panic about every existing conversation or account.

There is one lasting habit worth keeping. When a vendor announces a security-driven update, read the current advisory rather than a screenshot of its first version. In this case the deadline changed, the desktop product lineup later changed, and the official download instructions remained the reliable anchor.

FAQ

Was the ChatGPT Mac app itself hacked?

OpenAI said it found no evidence that its published software was altered or that malicious software was signed with an OpenAI certificate. The incident affected two employee devices and exposed limited credential material from some internal repositories, which is why OpenAI rotated signing certificates as a precaution.

Is the update deadline June 12 or June 26, 2026?

June 12 was the original deadline shown in parts of OpenAI’s notice. An amendment at the top of the official page extended the macOS update deadline to June 26, 2026. Both dates have passed, so users with an old build should update through the app or an official OpenAI download page now.

Should I change my ChatGPT password or API key?

Not because of this advisory alone. OpenAI said customer passwords and API keys were not affected. Change credentials if you entered them into a suspicious installer, received an account security alert, or have another reason to believe your own account was exposed.

Where should I download the current ChatGPT app for Mac?

Use the application’s built-in updater or OpenAI’s official download page at chatgpt.com/download. Do not use installers delivered through email, messages, ads, file-sharing links, or third-party download sites, and do not bypass a macOS security warning to force an old package to open.