
OpenAI Codex is most useful in enterprise engineering when it is treated as a controlled software workflow, not a shortcut around engineering process. Large teams already have repositories, access rules, code owners, release windows, incident reviews, and security requirements. An AI coding agent has to fit into that system. If it works outside the system, it becomes another source of unreviewed change.
Cisco-style enterprise AI work is usually about scale, governance, and operational discipline. Cisco publishes broad AI material for infrastructure, security, and enterprise adoption, while OpenAI documents Codex as an agent for software engineering tasks. Bringing those ideas together leads to a simple rule: use Codex where it can create reviewable engineering artifacts, and keep people responsible for scope, approval, production risk, and release decisions.
Architecture before automation
The first enterprise question is not “can Codex write this code?” It is “what is Codex allowed to see and change?” Repository scope should be explicit. A documentation task may only need one folder. A test draft may need the feature module and test utilities. A bug fix may need logs, reproduction steps, and a small set of related files. Giving an agent the whole organization by default is convenient, but it also increases the chance of accidental changes and unnecessary data exposure.
A safe intake process starts with a ticket or issue. The ticket should state the problem, affected repository, allowed files or modules, constraints, test command, and reviewer. If the task touches authentication, payments, security controls, customer data, or deployment scripts, the default should be human-led work with Codex assisting only in narrow drafts or explanations.
Model access, secrets, and rate limits
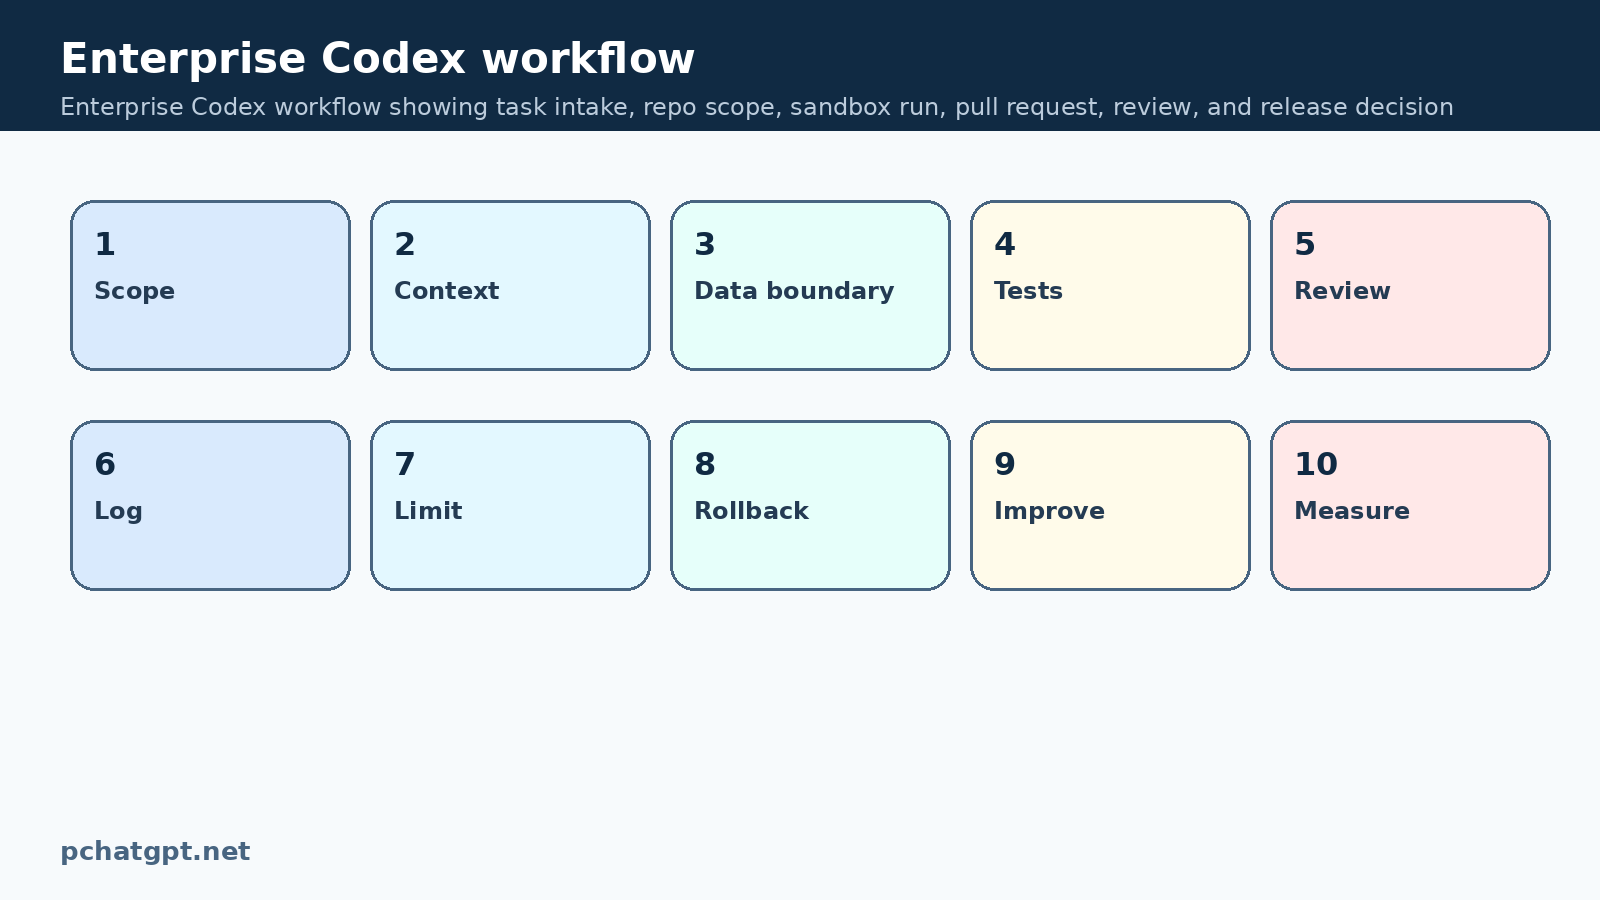
The second question is environment. Codex can help with engineering tasks, but enterprise teams need to decide where commands run, which secrets are available, and whether network access is allowed. A sandbox with no production credentials is the safer default. If a test needs a secret, use a temporary scoped value or a mock. Do not expose production tokens to an agent just to make a local test easier.
Enterprise teams should also record what happened during the run. Keep the task brief, resulting patch, test output, and reviewer decision. This turns AI assistance into auditable engineering work rather than a private chat. It also makes it easier to learn which task types produce reliable patches and which ones waste review time.
The right runtime for the workload
Pull requests are the natural control point. Codex output should arrive as a diff that a person can inspect. The pull request description should explain the change, tests run, dependency changes, known limits, and any files the agent intentionally avoided. If the agent cannot provide that explanation, the reviewer should ask for it before reviewing the code itself.
Reviewers should start with the boundaries: did the patch stay inside the requested scope, did it change dependencies, did it touch secrets or logging, and did it remove tests? After that, they can review correctness. This order matters because a patch can look correct inside one function while creating a broader operational problem.
Cost, data boundaries, and review
OpenAI evaluation guidance is useful beyond model testing. Enterprise engineering teams can create lightweight evaluations for agent work. For example, track whether Codex changed files outside scope, whether tests passed, whether dependency changes were explained, whether reviewers requested major rewrites, and whether the change caused a rollback. These are practical signals, not academic scores.
A measured rollout might begin with documentation, test generation, code explanation, and small bug fixes. After several weeks, the team can compare review time and defect rates. If the evidence is good, Codex can handle larger but still bounded tasks. If the evidence is weak, the answer is not to ban the tool. Tighten the task template, reduce scope, and improve the test harness.
Observability and operating discipline
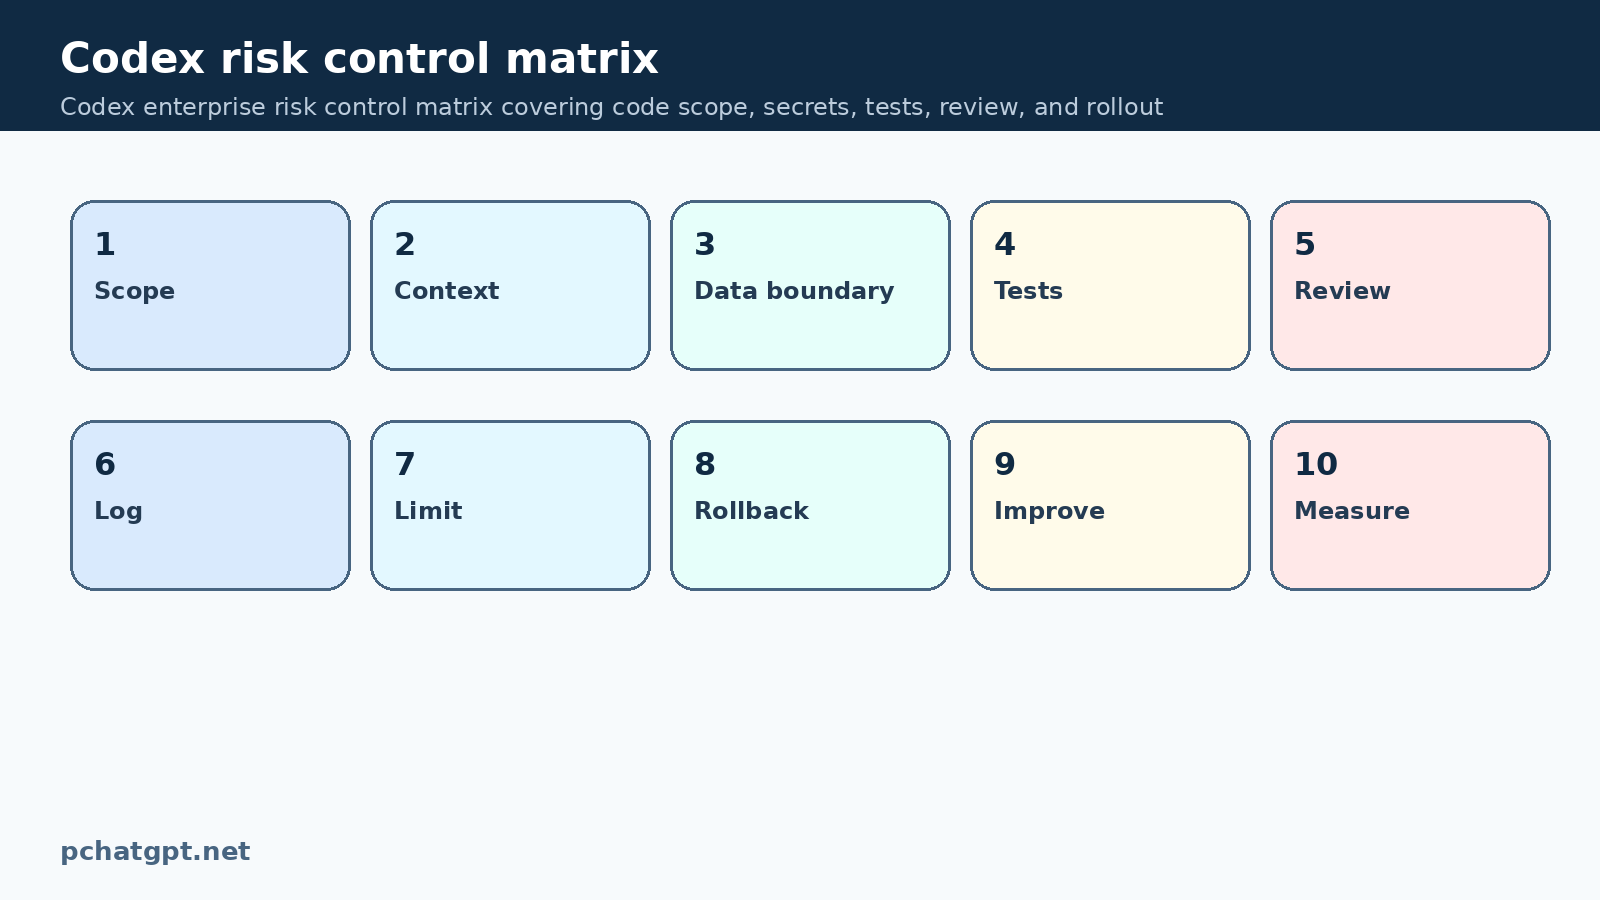
Security teams should be involved early. AI coding agents interact with source code, build systems, logs, and sometimes issue trackers. That makes identity, access control, and data retention important. Decide which repositories are allowed, who can assign Codex tasks, how outputs are logged, and how long prompts or run artifacts are retained. The policy should be written in plain language so engineers can follow it during normal work.
Secrets deserve special treatment. An agent should not need production secrets for most coding tasks. If generated code touches configuration, environment variables, or credential handling, reviewers should inspect that section carefully. Also check for accidental logging of tokens, prompt content, or customer data. A helpful patch can still be unsafe if it makes private data easier to leak.
A practical adoption sequence
Enterprise architecture decisions should remain human decisions. Codex can compare files, draft migration steps, explain a library, or propose a refactor. It should not silently choose a new architecture, replace a critical dependency, or alter deployment policy. Those choices depend on business priorities, support capacity, compliance obligations, and incident history. The agent does not know those constraints unless the team writes them down and enforces them in review.
A useful operating model is to classify tasks by consequence. Low consequence tasks can be agent drafted and lightly reviewed. Medium consequence tasks need owner review and test evidence. High consequence tasks need senior review, security review, or manual implementation with Codex limited to research and explanation. This classification is easier to follow than a vague rule such as “use AI responsibly.”
What to do next
The long term value of Codex in enterprise engineering comes from process learning. Each accepted task teaches the team which prompts, tests, and boundaries work. Each rejected task teaches where the workflow is too broad or the codebase lacks enough tests. Keep a short record of both. Over time, the organization builds an internal playbook instead of relying on vendor demos or scattered enthusiasm.
Codex should make engineering work more reviewable, not less. If it produces smaller pull requests, clearer test plans, and faster explanations of unfamiliar code, it is helping. If it produces large diffs, unexplained dependency changes, or patches that reviewers do not understand, narrow the scope. Enterprise AI adoption succeeds when automation fits inside accountable engineering practice.
Implementation checklist
Before publishing the workflow, write a one page operating note for OpenAI Codex enterprise engineering. Include the owner, allowed users, data that may enter the system, data that must stay out, expected output, review rule, test command, cost limit, and rollback path. This note keeps the article topic grounded in a real working procedure rather than a vague promise. It also gives reviewers something concrete to compare against when the tool behaves differently from the original plan.
Review the setup after the first few real tasks. Check whether OpenAI Codex enterprise engineering saved time, whether users trusted the output too quickly, whether logs were enough to diagnose errors, and whether any step encouraged unsafe copying of private data. Keep the parts that worked, remove unused automation, and tighten the brief where reviewers found repeated mistakes. Small corrections made early are cheaper than repairing a broad system after users depend on it.
A second check should focus on the reader. Someone arriving from search should understand what problem OpenAI Codex enterprise engineering solves, what the tool can do today, what still needs human judgment, and which official documents support the workflow. If a paragraph could appear in any AI article, rewrite it around the actual task. If a claim depends on a product feature, link to the official documentation. If the article suggests an operational habit, make the owner and review point clear.
The final pass is simple: keep the URL stable, keep the promise narrow, and make the article useful to a person who has to configure or review OpenAI Codex enterprise engineering tomorrow. Plain instructions, named controls, and honest limits are better than broad claims about transformation. That is also the safest way to improve an older search page without creating another generic article.
For teams using this guide as a cleanup pass, compare the new article with the old version before calling the job finished. The refreshed page should no longer depend on repeated prompt boilerplate, generic productivity advice, or a copied FAQ. Each section should answer a real search intent for OpenAI Codex enterprise engineering, and every recommendation should be something a reader can apply without guessing which product surface or workflow the article means.
For enterprise Codex adoption, separate product documentation from operating governance. OpenAI sources can support Codex and evaluation workflows, while enterprise AI material can frame broader adoption needs. The article should not imply that any named company endorses the exact process here. It should show how an engineering organization can turn agent output into scoped pull requests, reviewer evidence, and measured rollout decisions.
For OpenAI Codex enterprise engineering, the publication check should also include basic maintenance questions. Who updates the article when the official documentation changes? Which internal link should send readers to a deeper guide? Are image ALT texts specific enough to describe the diagram? Are the FAQ answers short, direct, and different from each other? These small editorial checks reduce low value signals because the page stops looking like a reused shell. They also make the next review faster because evidence, limits, and update ownership are already visible. If one section reads like a generic AI safety paragraph, replace it with a task-specific decision, such as which repository, data class, runtime, reviewer, or official source the reader should check first.
A short owner note should say what changed in the rewrite, which source was checked, and what would trigger another update. That makes OpenAI Codex enterprise engineering easier to maintain during later corpus reviews and prevents the same boilerplate from creeping back into the post.
Official sources used
- https://developers.openai.com/codex/
- https://help.openai.com/en/articles/11369540-using-codex-with-your-chatgpt-plan
- https://platform.openai.com/docs/guides/evals
- https://platform.openai.com/docs/guides/production-best-practices
- https://www.cisco.com/c/en/us/solutions/ai.html
Related guides
- https://pchatgpt.net/ai-coding-agents-dependency-aware-developer-environments-2026/
- https://pchatgpt.net/generative-ai-governance-2026-business-ai-rules/
FAQ
Is OpenAI Codex suitable for enterprise engineering teams?
Yes, when the team controls repository scope, runs work in safe environments, reviews pull requests, and measures quality before expanding use.
What should Codex be allowed to change first?
Start with documentation, tests, code explanations, and small bug fixes. Avoid production infrastructure, authentication, payment, and security sensitive changes until the workflow is proven.
How should enterprises measure Codex quality?
Track scope violations, test results, dependency changes, reviewer rewrite rate, rollback rate, and whether the task saved reviewable engineering time.
Can Codex replace senior engineering review?
No. Codex can draft and explain code, but senior engineers still own architecture, security, release risk, and business tradeoffs.