Calling AI a “partner” can sound grander than the technology deserves. ChatGPT does not share your goals, carry professional responsibility, or notice every consequence of a bad decision. Yet the way people work with AI has changed. A one-off prompt can now sit inside a continuing project, draw on selected sources, conduct multi-step research, and, in agent mode, move from analysis toward action. The useful 2026 question is not whether software has become a colleague. It is how to design a collaboration in which the system contributes continuity and initiative without inheriting human authority.
This guide takes a narrow view of that shift through current ChatGPT workflows. The central idea is simple: treat AI partnership as an operating model. Give the system a bounded role, a controlled context, a reviewable assignment, and a clear stopping point. Keep purpose, judgment, permission, and accountability with people. That produces a more useful assistant than either extreme: a chatbot that forgets the job after every exchange, or an agent given a vague goal and too much access.
What changed from tool use to continuing collaboration?
A traditional software tool waits for an explicit command and returns a predictable transformation. A calculator evaluates an expression. A spellchecker flags a pattern. Generative AI is less deterministic. It interprets an instruction, creates a response, and can adapt after feedback. The interaction becomes collaborative when four conditions appear together: the work continues across sessions, relevant context remains available, the system can perform several dependent steps, and a person can inspect or redirect the process.
ChatGPT Projects provide one practical example. OpenAI’s Projects documentation describes workspaces that group chats, reference files, and project instructions around ongoing work. That means a research brief, source set, editorial rules, and separate working conversations can live within one boundary. Shared projects can also let members build on a common context. They are not synchronous co-editing rooms, and shared chats can be branched rather than edited together in real time. The collaboration is based on a common source layer, not on pretending the model is another employee.
Research has also become less like asking for an instant answer. OpenAI’s current deep research overview says the feature can conduct multi-step investigation, use supplied files and selected sources, show progress, and return a cited report. The same page also acknowledges limitations, including incorrect inferences, hallucinated facts, difficulty judging authority, and imperfect confidence calibration. That combination of greater initiative and persistent fallibility defines the real shift. The assistant can do more of the route planning, while the user needs a stronger method for checking the destination.
The collaboration stack: purpose, context, work, approval
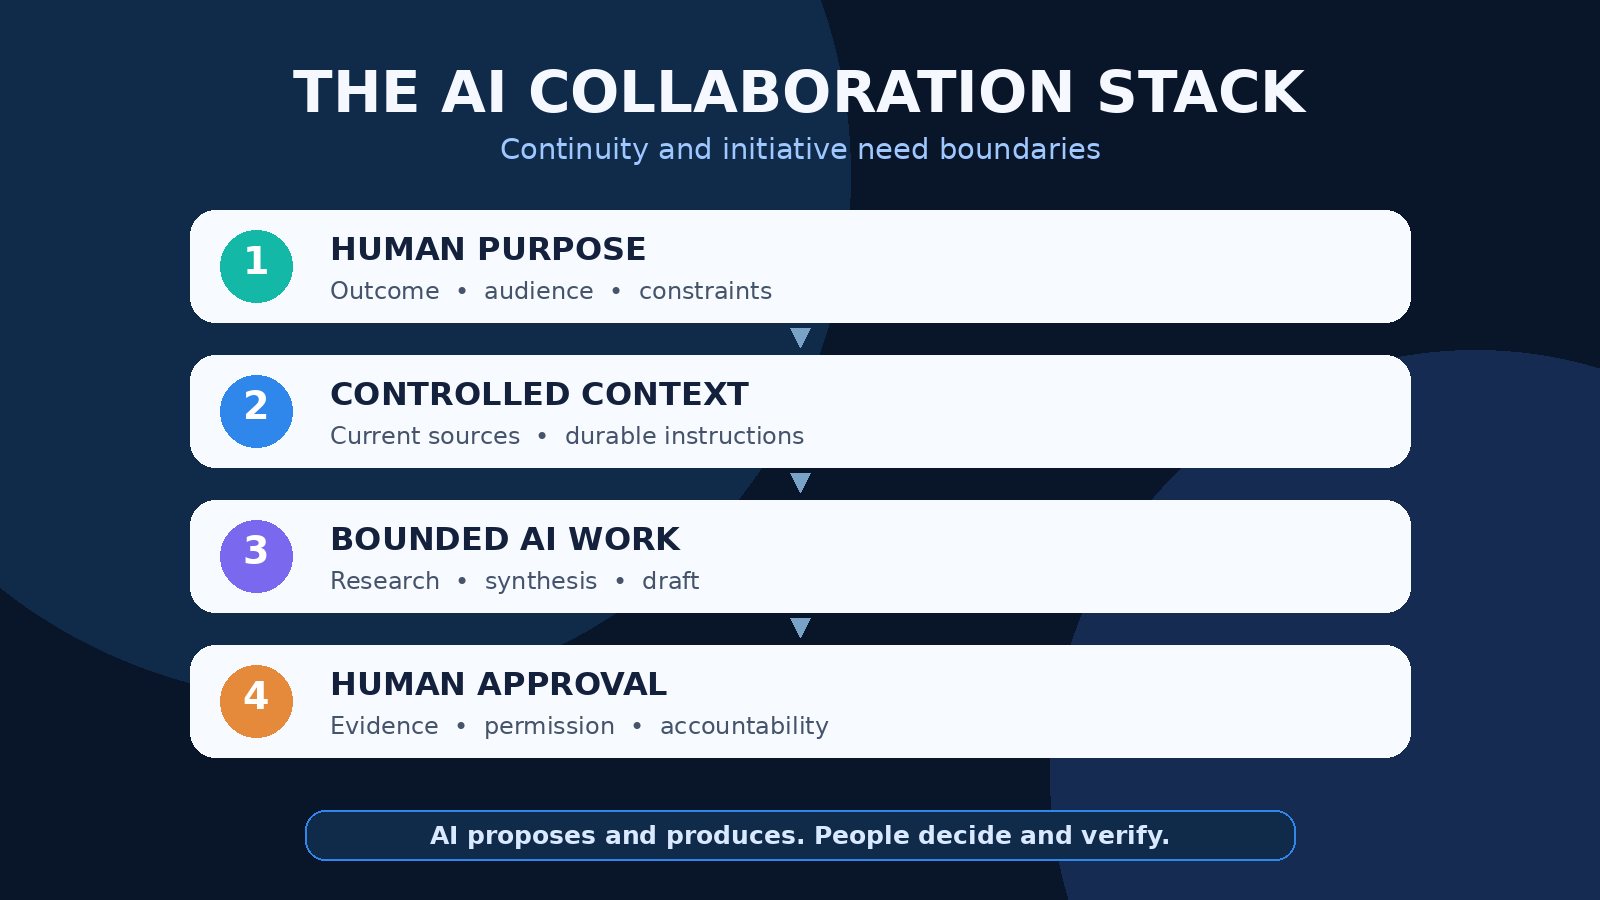
A useful partnership has four layers. Each layer answers a different question. Mixing them into one long prompt makes errors harder to diagnose.
Purpose belongs to the human. State the outcome, audience, constraints, and reason the work matters. “Help with our launch” leaves too much undefined. “Prepare an evidence map for an editor deciding whether our product claim is supportable” supplies a real decision. The person also names what must not happen, such as contacting a customer, changing a live document, or treating an inference as a verified fact.
Context should be selected, not dumped. Put governing documents, current source material, and durable instructions in the workspace that needs them. Remove superseded files or mark their status. A larger pile is not automatically better context. Contradictory drafts, unlabeled notes, and stale policies invite the model to blend incompatible claims. A short source register with owner, date, status, and purpose often adds more value than another hundred pages.
AI work should be bounded by a deliverable. Ask for an outline, comparison, question list, evidence table, draft, or proposed action. Require the response to separate supplied facts, external findings, assumptions, and open questions. A concrete deliverable creates something a person can review. “Think deeply” is not a control, while “list each material claim beside its source and flag unsupported claims” is.
Approval remains a separate human step. A polished response is not proof. Before publication or action, verify important quotations against the source, check calculations, resolve conflicts, and confirm names, recipients, dates, quantities, and permissions. If the task can change an external system, approval should concern the exact proposed change, not a vague instruction to continue.
Use Projects as a shared context hub, not a truth machine
A Project can reduce repetitive prompting because its files, instructions, and conversations remain organized around the same effort. One chat can examine user research, another can build an outline, and a third can challenge the first draft. This separation is easier to audit than one endless conversation, while the project still supplies common material.
Start with a short project charter. Include the desired outcome, audience, accepted source hierarchy, required output format, prohibited actions, and escalation rule. For example: “Use approved product documentation before meeting notes. If two sources conflict, quote both and ask the owner. Do not create performance claims from anecdotes. Mark every recommendation as proposal until an editor approves it.” Durable rules belong in project instructions. The immediate question belongs in the chat prompt.
Shared context needs ownership. Assign one person to maintain instructions and one owner for each critical source. Team members should label drafts as draft, approved, or superseded. When someone moves an old conversation into a project, they should identify which assumptions remain valid. Without these habits, memory can preserve confusion just as effectively as it preserves useful context.
The sharing boundary matters too. OpenAI states that members of a shared project can view chats and files, and files may be downloadable. Once shared, the project uses project-only memory, which keeps members’ outside memories and conversations out of the shared context. That is a helpful boundary, but it does not make material inside the project private from other members. Review the membership list and the actual file before adding customer, employee, legal, or commercially sensitive material.
For a detailed setup, see PChatGPT’s ChatGPT Projects guide. Its practical distinction between chats, sources, instructions, and project memory is especially useful when a team wants continuity without creating one unreadable thread.
Memory helps continuity, but it is not an authoritative record
OpenAI’s Memory FAQ describes memory as context from chats, files, and connected apps that can personalize later responses when enabled. The current experience includes controls for reviewing and changing a memory summary, but the documentation also says the summary may not show every factor that shaped a response. A saved or synthesized memory is therefore a convenience layer, not a controlled database.
Do not rely on memory for a fact that must be exact. Put an approved requirement, policy clause, or current specification in a named source and cite it in the task. Ask the assistant to distinguish the source from anything recalled. If the source changes, replace it deliberately and note the change. For isolated work, use a project-only boundary where appropriate. For a sensitive one-off discussion that should not create or use memories, OpenAI documents Temporary Chat as the relevant option.
Memory can also create a subtle authority problem. A preference repeated from an earlier chat may sound like a current requirement. A personal detail may be irrelevant to a team assignment. A prior conclusion can anchor new analysis even after the evidence changes. Start consequential tasks with a short context check: “List the project sources and assumptions you plan to use. Do not begin the draft until I confirm them.” This turns invisible continuity into a reviewable handoff.
Move from conversation to research with an evidence contract
Deep research is most useful when the question genuinely requires synthesis across multiple sources. It is excessive for a quick definition and insufficient by itself for a decision that needs expert judgment. Before a run, write an evidence contract that says what counts as an acceptable source, the period or jurisdiction that matters, what should be excluded, how uncertainty should be shown, and what output will be reviewed.
For a product policy comparison, an evidence contract might prioritize current vendor documentation and regulator publications, exclude affiliate summaries, require a link for each material claim, and create an unresolved column whenever sources disagree. For a literature review, it might define eligible study designs and ask for direct quotations around limitations. The contract narrows the model’s search space and gives the reviewer a checklist.
After the report arrives, sample the evidence before polishing the prose. Open several citations, confirm they support the sentence, and check whether qualifiers survived the summary. Search the report for numbers, dates, superlatives, and causal language because those claims deserve extra scrutiny. Read at least one source that argues against the report’s direction. If a key source is inaccessible or ambiguous, label the gap instead of allowing fluent synthesis to hide it.
Do not describe this as verification by the AI. The system can collect and organize evidence, but the acceptance act belongs to a competent person. A good research workflow makes that handoff visible with columns such as claim, source, excerpt, model interpretation, reviewer decision, and follow-up.
Agent mode changes the risk because output can become action
OpenAI’s ChatGPT agent overview describes a system that can combine browsing, analysis, a terminal, and connected information, while letting the user interrupt, take over, or stop. It also says permission is requested before consequential actions. The same official page warns about model mistakes and prompt injection, including malicious instructions hidden in web content. The important boundary is no longer only whether an answer is correct. It is whether a mistaken or manipulated answer can change something outside the chat.
Match authority to reversibility. It may be reasonable for an agent to gather public pages and prepare a comparison. Drafting a calendar proposal is riskier but still reviewable. Sending invitations, submitting a form, changing permissions, publishing content, deleting records, or making a purchase requires a much tighter checkpoint. Keep credentials and unrelated connected apps unavailable unless the task needs them.
For every action task, specify allowed sites, allowed operations, prohibited operations, spending or quantity limits where relevant, and an exact stop condition. Ask for a preview of the final payload. Then inspect the destination, recipient, and values before approval. After execution, read the target system rather than trusting a completion message. A confirmation generated by the same process is not independent evidence that the state changed correctly.
A five-stage workflow for responsible AI collaboration
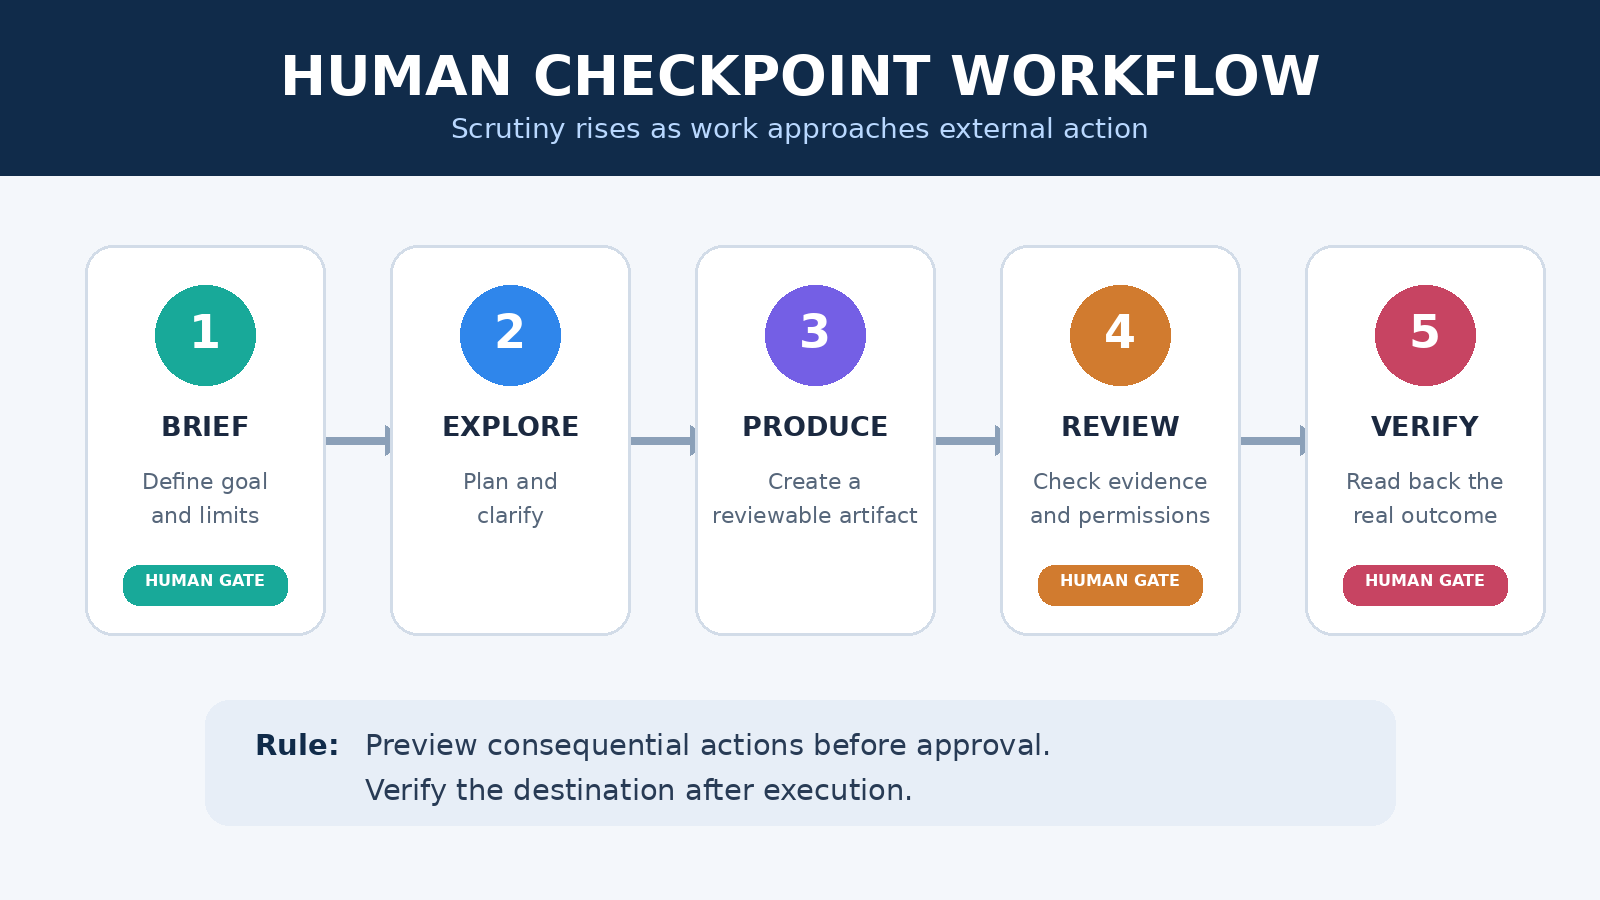
- Brief: A person defines the outcome, audience, allowed data, source rules, and prohibited actions. If the assignment affects another person, name the responsible reviewer.
- Explore: ChatGPT asks clarifying questions, organizes supplied context, and proposes a plan. The user corrects scope before substantial work begins.
- Produce: The system creates a bounded artifact such as an evidence table, draft, analysis, or action preview. Claims stay connected to sources, and uncertainty stays visible.
- Review: A person checks evidence, reasoning, tone, privacy, permissions, and downstream effects. The reviewer either accepts, revises, or rejects the artifact.
- Verify: If anything is published, sent, scheduled, or changed, read back the destination. Record what changed, who approved it, and any follow-up needed.
This workflow lets the assistant take initiative inside a controlled lane. It also prevents a common failure: allowing the model to define the goal, select the evidence, judge its own output, and execute the result. Those are separate responsibilities for a reason.
Privacy and data choices are part of the collaboration design
Before uploading a source or connecting an app, ask whether the task can be completed with less data. Redact unnecessary personal details, use a smaller excerpt, and separate clients or projects that should not share context. Access should follow the work, not convenience. Disconnect an app when the continuing benefit no longer justifies the exposure.
For individual ChatGPT accounts, OpenAI’s Data Controls FAQ explains the setting that determines whether conversations help improve models. It also distinguishes Temporary Chats, which do not appear in history, create memories, or train models and are deleted from OpenAI’s systems after the documented retention period. These controls address different questions. Turning off model improvement does not remove chat history, and turning off memory is not the same as changing training preferences.
Organizations should use the controls and contractual terms applicable to their workspace rather than copying assumptions from a personal account. Define which data classes may enter the system, who can share projects, which apps may connect, how access is reviewed, and where approvals are logged. The PChatGPT AI productivity tools guide provides a useful comparison of conversational assistance, bounded agent work, and repeatable automation.
How to measure whether the partnership is actually useful
Do not measure success by response volume or how human the conversation feels. Measure the work. Useful indicators include the time from brief to reviewable artifact, the proportion of material claims with valid sources, reviewer correction rate, number of unresolved questions surfaced before publication, and the frequency of prevented or reversed actions. For recurring workflows, track stale-source incidents and permission exceptions.
Compare against the previous human process on the same kind of task, but do not invent a performance claim from a handful of examples. Record the input class, reviewer standard, and failure categories. A faster draft that creates more verification work may not save time. A slower evidence table that exposes missing information may be far more valuable.
Quality should improve through the operating system, not through faith in a future model. Tighten the brief when outputs drift. Improve source labels when the assistant blends versions. Add a checkpoint when reviewers repeatedly catch the same risky transition. Remove access that is not producing clear value. The goal is a workflow that remains understandable even as models and interfaces change.
FAQ
Is AI really a partner in 2026?
It can function as a continuing collaborator in a workflow because it can retain selected context, conduct multi-step work, and respond to feedback. It is not a legal, moral, or professional partner. People still own the purpose, permissions, review, and consequences.
What is the safest first step for team collaboration with ChatGPT?
Choose one low-risk, reversible task and create a small source set with clear project instructions. Ask ChatGPT for a reviewable artifact, not an external action. Have a named person check the evidence and record what needed correction before expanding the workflow.
Should a team rely on ChatGPT memory for project requirements?
No. Memory is useful for continuity but is selective and can change. Store controlling requirements in an approved, named source, point to that source in the prompt, and ask the assistant to flag conflicts rather than resolve them silently.
When should AI collaboration stop before action?
Stop for human approval whenever the next step can send a message, publish content, spend money, disclose data, change permissions, delete a record, accept terms, or otherwise affect another person or system. Review the exact payload, then verify the destination after execution.
Final perspective
The important evolution is not from obedient machine to digital coworker. It is from isolated generation to a continuing, tool-using workflow. Projects can preserve selected context. Memory can reduce repetition. Deep research can organize a long investigation. Agent mode can bridge analysis and action. Each gain also creates a new responsibility: curate the context, define evidence, limit authority, and verify outcomes.
A trustworthy AI partnership is therefore deliberately asymmetrical. The system may propose, search, synthesize, draft, and prepare. A person decides why the work matters, what information is appropriate, which claims are acceptable, and whether an action should occur. That boundary does not make collaboration weaker. It is what makes the collaboration dependable.